Overview
CalCOFI data is available through various portals, each serving different purposes and user needs. Since 2026-09, every dataset — integrated into the database or still a holding — also has one calcofi.io page (/datasets/{dataset_key}/) joining every endpoint it can be reached through: the release Parquet, a CF netCDF, ERDDAP, and the archive or aggregator portals below, each with its own publication status. That page, not this chapter, is now the record — the tables here are generated from the same registries the page reads, so the two can never disagree.
Data Flow
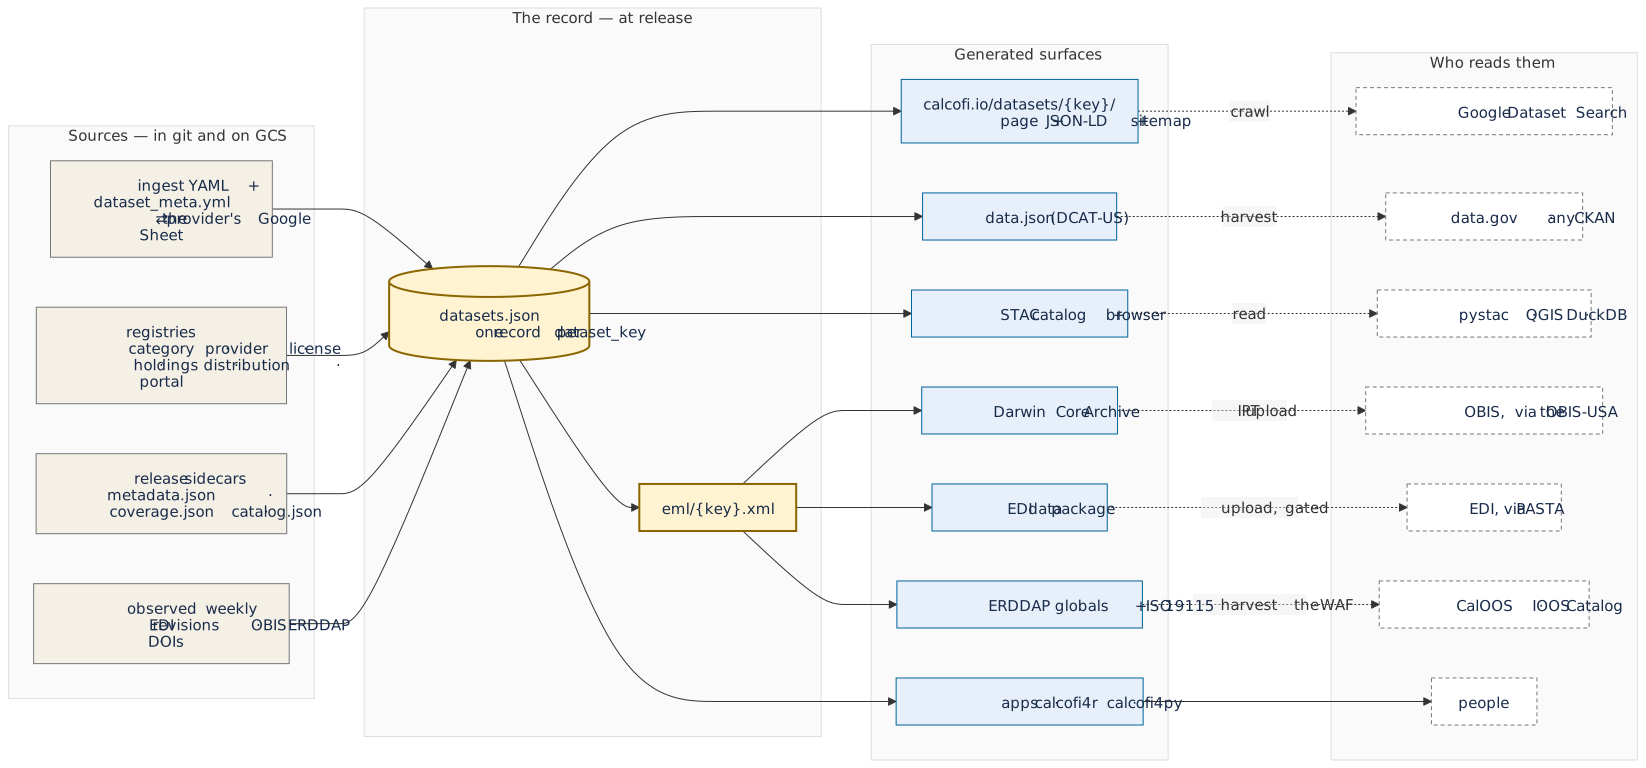
While it would be ideal for CalCOFI data to be available through a single portal, each portal has its strengths and limitations. Figure 10.1 is the flow as it runs today: what we author and observe (left) becomes one record per dataset at release, that record generates every surface a portal can read, and each portal or meta-portal is pointed at one of those static files.
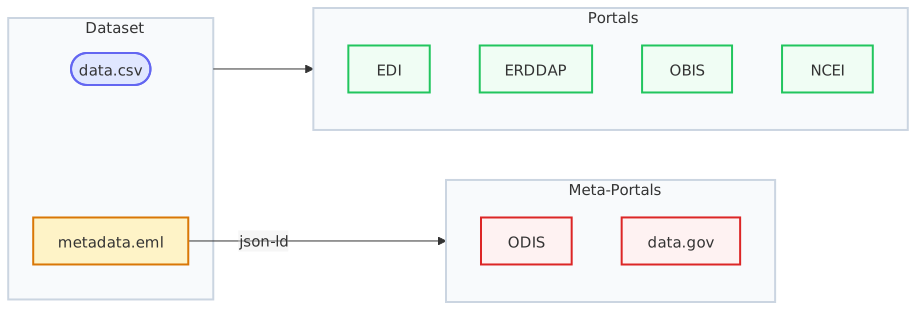
In practice, CalCOFI is a partnership with various contributing members, so the authoritative dataset might flow differently, such as from EDI to the database to the other portals. The other portals, such as OBIS or ERDDAP, serve different audiences or purposes. The dataset catalog is what now feeds the meta-portals directly — ODIS crawls its sitemap and JSON-LD, Google Dataset Search its JSON-LD, and data.gov its DCAT-US data.json — rather than each meta-portal having to know about every downstream portal individually.
Portal capabilities
While some portals serve as data repositories, others provide advanced data access and visualization tools, and a few are meta-portals that index the others rather than holding data themselves. Table 10.1 is generated from CalCOFI/workflows’ metadata/portal.csv — the same registry datasets.json’s registrations[] and this book both read — so a portal added there (CalOOS and the IOOS Catalog joined in 2026-09) shows up here without anyone hand-editing a table.
EDI
Environmental Data Initiative
- Complete dataset archives using DataOne software and EML metadata
- DOIs issued for all datasets ensuring citability
- Full archive allowing for any data file types
- Basic spatial and temporal filtering through web interface
- Download in original formats with metadata
- Access through DataOne API
- Links:
Publishing there is manual, in four steps (publish_to-edi.qmd, generic per dataset; the package is built from the release’s own eml/{dataset_key}.xml plus CSV entities exported from the core — for the bottle database three tables totalling 2.1 GB plus the shared vocabulary table). (1) An EDI account for the open edi scope, held by Erin, with Ben granted editor access through the EML access element — created once at dashboard.edirepository.org. Every release already stages the package at gs://calcofi-db/publish/edi/{dataset_key}/{dataset_key}_{version}/ for review (the dataset page lists it as built, not deposited), version being the release it was last rebuilt from (a package is rebuilt only when its dataset changed — see After every release); every entity’s EML url points at that staged copy, and the EML is checked against the EML 2.2 schema (EML::eml_validate(), inside check_eml()) on every run, a reused package included. (2) Set EDI_USER/EDI_PASS (or an EDI API key as EDI_KEY) wherever the pipeline runs and render the notebook: PASTA evaluate runs automatically against staging and the report lands beside the package; fix what it names and re-render. (3) Once evaluate is clean, render with CALCOFI_PUBLISH_EDI=true to create (or, on a later release, update) the package against production — this mints a DOI and a scope.identifier.revision, recorded in metadata/edi_packages.csv. (4) Add the DOI back as an archive row in metadata/distribution.csv (portal: edi) and as the dataset’s doi in its metadata/{provider}/{dataset}/dataset_meta.yml, so the record and the citation carry it from the next release on. CCE-LTER’s knb-lter-cce packages stay theirs and are never republished.
NCEI
National Centers for Environmental Information
- Long-term archival of oceanographic data
- DOIs issued for dataset submissions
- Standardized metadata using ISO 19115-2
- Basic search interface with geographic and temporal filtering
- Data preserved in original submission formats
- Access through NCEI API services
- Links:
OBIS
Ocean Biodiversity Information System
- Specialized in marine biodiversity data
- Standardized using DarwinCore fields
- Extended measurements supported via extendedMeasurementOrFact, the OBIS-ENV-DATA pattern (De Pooter et al. 2017)
- Powerful filtering by space, time, and taxonomic parameters
- Multiple download formats (CSV, JSON, Darwin Core Archive)
- Full REST API access
- Published through the OBIS-USA Integrated Publishing Toolkit (
ipt-obis.gbif.us), one resource per dataset whose taxa resolve to WoRMS
- Links:
Uploading is manual, and deliberately so. publish_to-obis.qmd writes data/darwincore/{dataset_key}_{version}.zip and a {dataset_key}_manifest.json, and stages both at gs://calcofi-db/publish/dwca/{dataset_key}/ so a provider — and the dataset page, which lists the archive as built, not deposited — can inspect the bundle before any upload; nothing in the pipeline talks to a portal. CalCOFI has no IPT of its own — the resources live on the OBIS-USA IPT, ipt-obis.gbif.us, under Ben’s login. Before a first upload, the OBIS records that already cover the same source are listed (the notebook queries api.obis.org/v3/dataset and prints the curated rows from metadata/distribution.csv) and resolved with their owners: a provider’s own record is never duplicated, and a historical CalCOFI record is retired or cross-referenced only with its owner’s agreement. Then: open (or create) the resource → upload the zip’s files as the source → map the Event core plus the Occurrence and ExtendedMeasurementOrFact extensions exactly as meta.xml describes them → publish a new version. Afterwards, record the OBIS dataset id and the IPT resource id as distribution.csv rows (portal = obis / ipt, kind = archive) and stamp uploaded_utc + uploaded_hash into the manifest. That last step is what makes a dataset page honest: the record reports built, not uploaded / published (vX) / stale — data changed in vY by comparing the uploaded hash with the archive’s own, so it says when an upload is due. Re-upload only when the content_hash changed — it is deterministic over the archive’s CSV bytes.
ERDDAP
Environmental Research Division Data Access Program
- Tabular and gridded data server
- Advanced subsetting by space, time, and parameters
- Multiple output formats (CSV, JSON, NetCDF, etc.)
- RESTful API with direct data access
- Built-in data visualization tools
- No persistent identifiers but stable URLs
- Links:
Zenodo
- One DOI per integrated-database release, via the GitHub integration on CalCOFI/workflows — a concept DOI covers every version, a version DOI each one
- Archives the pipeline itself at the release tag, plus
catalog.json / metadata.json
- Link: zenodo.org
CalOOS
The SCCOOS + CeNCOOS regional data portal
- Registering erddap.calcofi.io gives every existing CoastWatch-fed module a calcofi.io distribution beside it
- What data.ioos.us (the national IOOS Catalog) harvests for this region — likely the only IOOS-level registration CalCOFI needs
- Link: data.caloos.org
The dataset catalog, and who registers where
datasets.json (calcofi4db::build_dataset_catalog(), calcofi4db ≥ 4.1.0) is the record this whole chapter is a rendering of: one entry per dataset, its registrations[] naming every portal above with a status of published, planned (usually linking the tracking issue) or n/a. Table 10.2 reads it from the promoted release (the snapshot under data/ that every render refreshes), so it cannot drift from what calcofi.io/datasets/{dataset_key}/’s own Access table shows.
After every release: rebuild what changed, list what is due
The four publishers — publish_to-edi.qmd, publish_to-obis.qmd, publish_to-netcdf.qmd and publish_to-erddap.qmd — are targets in the same targets pipeline as the release, each depending on test_release, so they run after a release is tested and promoted and always read the promoted version. Most releases change a few datasets and leave the rest alone, so each publisher fingerprints, per dataset, what its output is a function of (calcofi4db::publish_fingerprint()): the dataset’s rows in every table it reads, identified by the release’s own row signatures rather than by bytes or version (a dataset_key partition is signed by its catalog content_hash, a shared object is read once and its per-dataset signatures cached by content_hash); the dataset’s catalog record and the registries the output carries; and the publisher’s own code. An unchanged fingerprint with the output still on disk is reused — the package, archive or file keeps the release it was built from, and records the release it was confirmed against — and anything else is rebuilt, the notebook naming the input that moved (publish_decide()). The slowest outputs — the full-resolution CTD netCDF and the EDI CSV exports — are therefore paid for once per change, not once per release.
Whether a portal is behind is a second, separate comparison: the bytes built now against the bytes the portal was last given (publish_upload_status(): never uploaded, current or changed since {version}). publish_status.qmd, the target that runs after all four, makes that comparison for every dataset on every portal and writes the to-do list to gs://calcofi-db/publish/portal_status.csv and calcofi.io/workflows/publish_status.html; Table 10.3 says where each portal’s copy is recorded.
Archive of record, per dataset
Every dataset has one portal that holds its citable, DOI-bearing copy — its archive of record — and the others are either aggregators and services that read from it or do not apply. The rule is stated per dataset, in one sentence, in metadata/dataset_status.csv’s publish_policy column (CalCOFI/workflows), carried into datasets.json as status.publish_policy (calcofi4db ≥ 4.6.3) and shown on each dataset page above its Archives & portals table. The rules behind the sentences:
- A provider’s own archive is the archive of record, and is never republished. The nine CCE-LTER-adjacent datasets live in
knb-lter-cce on EDI (phyllosoma, phytoplankton, euphausiids, picoplankton, the Farallon bird and mammal census) or in CCE-LTER’s DataZoo exports (ZooDB, ZooScan); DIC is NCEI accession 0301029; the mesopelagic fish and the Dungeness crab megalopae are UC San Diego Library deposits; CUFES is SWFSC’s CoastWatch ERDDAP dataset.
- CalCOFI’s own program datasets get an EDI package from the release — bottle, CTD casts, METS — built by
publish_to-edi.qmd from eml/{dataset_key}.xml and the release tables, staged at gs://calcofi-db/publish/edi/ for review, deposited only with credentials and CALCOFI_PUBLISH_EDI=true. NCEI for these is planned through the SWFSC data manager.
- OBIS is the archive of record for occurrences of named taxa. The SWFSC ichthyoplankton is published there (through the OBIS-USA IPT); every other biological dataset’s Darwin Core Archive is built and staged at
gs://calcofi-db/publish/dwca/ each release, and its upload is the provider’s call (planned). Environmental datasets do not apply.
- NCEI is the provider’s to deposit for NOAA-collected data (SWFSC’s ichthyoplankton and CUFES), so it reads
n/a on those rather than planned.
- Zenodo holds the integrated database release itself, one DOI per version.
Table 10.4 states that policy per dataset, as the record carries it.
Getting the data through calcofi.io
The portals above are where CalCOFI data is discoverable outside calcofi.io; calcofi.io itself is a fourth way in, and it is where the record lives:
- The dataset catalog — one page per dataset (and per holding not yet ingested), with its coverage, every distribution above, its citation and provenance, and machine surfaces (
{key}.json, {key}.jsonld, the sitemap and data.json described above).
- Data Access — query the release Parquet directly from R, Python or a browser with DuckDB; no credentials, no API server.
- Libraries —
calcofi4r::cc_datasets() / calcofi4py.cc_datasets() read the same datasets.json this page’s tables do, into a data frame; cc_get_db() / cc_query() for the data itself.
- Cite This Data —
cc_cite() in calcofi4r / calcofi4py for exactly the datasets a query touched, checked citations, licences and DOIs.
- Explore — interactive exploration (the Explorer, Station and Hexagon Explorers, CTD Transects) without writing a query at all; each app’s Sources panel links back to the same dataset pages.
De Pooter, Daphnis, Ward Appeltans, Nicolas Bailly, Sky Bristol, Klaas Deneudt, Menashè Eliezer, Ei Fujioka, et al. 2017.
“Toward a New Data Standard for Combined Marine Biological and Environmental Datasets — Expanding OBIS Beyond Species Occurrences.” Biodiversity Data Journal 5: e10989.
https://doi.org/10.3897/BDJ.5.e10989.