---
title: "Ingest CCE-LTER Picoplankton and Bacteria Abundance"
calcofi:
target_name: ingest_cce_lter_picoplankton_bacteria
workflow_type: ingest
dependency:
- ingest_swfsc_ichthyo
output: data/parquet/cce-lter_picoplankton-bacteria/manifest.json
provider: cce-lter
dataset: picoplankton-bacteria
workflow_url: https://calcofi.io/workflows/ingest_cce-lter_picoplankton-bacteria.html
questions_file: metadata/cce-lter/picoplankton-bacteria/questions.csv
dataset_meta:
dataset_name: Picoplankton and Bacteria Abundance (CalCOFI Cruise)
# display trio, read by the release `dataset` table and the
# consumer apps (calcofi4db >= 3.15.0) — see NEWS for why these
# left the apps' own hardcoded maps
dataset_name_short: "Picoplankton & Bacteria"
category: "Picoplankton & Bacteria"
color: "#1f88cc"
# publishes the consolidated core: the source shape is wrangled in the notebook
# and projected into the shared core tables.
tables_owned:
- {table: sample, shared: true, note: "core event dimension (bottle grain)"}
- {table: obs, shared: true, note: "core occurrence headline (bio, flow-cytometry cell counts by taxon)"}
- {table: taxon, shared: true, note: "shared taxa reference"}
- {table: dataset_taxon, shared: true, note: "picoplankton population -> taxon_key crosswalk"}
- {table: measurement_type, shared: true, note: "shared registry across datasets"}
erd:
color: "#bbe0f0"
editor_options:
chunk_output_type: console
---
## Overview
**Source**: Datazoo table download (`https://oceaninformatics.ucsd.edu/datazoo/catalogs/ccelter/datasets/159/datatables/159/download`),
16,017 rows, 16 columns (73 cruises, 2004-11-02 to 2023-07-18).
- **Provider**: `cce-lter` (matches the existing provider group used by
`ingest_cce-lter_euphausiids`/`_zoodb`/`_zooscan` -- an earlier draft of
this notebook used the unhyphenated `ccelter`, which would have created a
duplicate, inconsistent provider group)
- **Grain**: one row per bottle/depth per cast (station-level, multiple depths per cast)
- **Scope decision**: no bounding-box filter applied -- source is already
scoped to CalCOFI/CCE cruises by the provider. `studyName` (e.g.
`2004-11-02-C-33RR`) is the cruise identifier used for key resolution, NOT
the `Cruise` column (which is a separate YYYYMM short code, e.g. `200411`
-- kept as a raw field but not used for joins).
- **Completeness**: Depth, Heterotrophic Bacteria, Synechococcus, and
Picoeukaryotes are >99.9% populated. Prochlorococcus is ~80% populated
(3,228/16,017 blank) -- plausible non-detection at higher latitudes/depths,
not yet confirmed with the provider (see Questions, Q01). `Notes` is 100%
blank in the current export; it is read and normalized to `NA` rather than
dropped, so a future export that starts populating it flows through without a
schema change. No literal-zero values appear
in any measurement column in this export (confirmed directly against the
raw file) -- unlike ZooDB, there is no analyzed-but-absent convention to
encode; blank simply means not measured.
```{mermaid}
graph LR
  A[Datazoo table 159<br/>16,017 rows] --> B[rename + type-cast]
  B --> C[picoplankton_bacteria_bottle<br/>position + depth, one row per bottle]
  B --> D[picoplankton_bacteria_measurement<br/>long format: 4 measurement types]
  C -.studyName -> cruise_key.-> E[(shared refs)]
  D -.bottle_id.-> C
```
## Setup
```{r}
#| label: setup
devtools::load_all(here::here("../calcofi4db"))
devtools::load_all(here::here("../calcofi4r"))
librarian::shelf(
  CalCOFI/calcofi4db, CalCOFI/calcofi4r,
  DBI, dplyr, DT, fs, glue, here, htmltools, janitor, jsonlite, knitr,
  lubridate, purrr, readr, sf, stringr, tibble, tidyr, units,
  quiet = T)
options(readr.show_col_types = F)
options(DT.options = list(scrollX = TRUE))

source(here("libs/ingest.R"))
cc <- read_calcofi_meta(here("ingest_cce-lter_picoplankton-bacteria.qmd"))
provider <- cc$provider
dataset <- cc$dataset
dataset_name <- cc$dataset_meta$dataset_name
tables_owned <- cc$tables_owned
dir_label <- glue("{provider}_{dataset}")
dir_parquet <- here(glue("data/parquet/{dir_label}"))
dir_stage <- cc_stage_path("parquet", dir_label, create = TRUE)
db_path <- here(glue("data/wrangling/{dir_label}.duckdb"))
meas_type_csv <- here("metadata/measurement_type.csv")
d_meas_type <- read_measurement_type(meas_type_csv)

if (overwrite) {
  if (file_exists(db_path)) file_delete(db_path)
  if (file_exists(paste0(db_path, ".wal"))) file_delete(paste0(db_path, ".wal"))
  if (dir_exists(paste0(db_path, ".tmp"))) dir_delete(paste0(db_path, ".tmp"))
}
dir_create(dirname(db_path))
con <- get_duckdb_con(db_path)
load_duckdb_extension(con, "spatial")
```
## Read Source Data
Fetched reproducibly by `libs/download_picoplankton_bacteria.R` into
`{dir_data}/cce-lter/picoplankton-bacteria/`. The dataset page links to the
Datazoo table download, but that URL redirects to a *Login / Accept Data
Agreement* form and so cannot be fetched unattended; EDI carries the same table
(the Datazoo DOI resolves to `knb-lter-cce.159`), so we pull from there. The
revision is deliberately unpinned — this series is ongoing — and the revision
actually used is reported below. Columns are renamed per
`metadata/cce-lter/picoplankton-bacteria/flds_redefine.csv`.
```{r}
#| label: read-source
source(here("libs/download_picoplankton_bacteria.R"))
pico_csv <- download_picoplankton_bacteria(
  path_expand(glue("{dir_data}/{provider}/{dataset}")),
  overwrite = overwrite_all)
stopifnot("picoplankton/bacteria CSV not found" = file_exists(pico_csv))

sync_to_gcs(
  local_dir = path_dir(pico_csv),
  gcs_prefix = glue("archive/{provider}/{dataset}"),
  bucket = "calcofi-files-public",
  exclude = c(".DS_Store", "*.tmp", "*.gdoc"))
d_raw <- read_csv(pico_csv, col_types = cols(.default = "c"))
cat(glue("Read {format(nrow(d_raw), big.mark=',')} rows, {ncol(d_raw)} columns"), "\n")
```
## Clean, Type-Cast
Canonical names from `metadata/cce-lter/picoplankton-bacteria/flds_redefine.csv`.
`studyName` (the cruise identifier string, e.g. `2004-11-02-C-33RR`) is
retained separately from `Cruise` (the YYYYMM short code) -- only the former
is used for cruise-key resolution. The four measurement columns
(Heterotrophic Bacteria, Prochlorococcus, Synechococcus, Picoeukaryotes) are
NOT kept as wide columns -- they are pivoted to long format below, following
the `bottle_measurement`/`zoodb_measurement` pattern used elsewhere in the
integrated DB.
```{r}
#| label: clean-cast
d_clean <- d_raw |>
  transmute(
    study_name       = studyName,
    cruise_code      = Cruise,
    datetime_utc     = as_datetime(`Datetime GMT`),
    latitude         = suppressWarnings(as.numeric(`Latitude (º)`)),
    longitude        = suppressWarnings(as.numeric(`Longitude (º)`)),
    line             = suppressWarnings(as.numeric(Line)),
    station          = suppressWarnings(as.numeric(Station)),
    cast_number      = suppressWarnings(as.integer(`Cast Number`)),
    bottle_number    = suppressWarnings(as.integer(`Bottle Number`)),
    assoc_bottle_number = suppressWarnings(as.integer(`Associated Bottle Number`)),
    depth_m          = suppressWarnings(as.numeric(`Depth (m)`)),
    het_bacteria_n_ml    = suppressWarnings(as.numeric(`Heterotrophic Bacteria (number/ml)`)),
    prochlorococcus_n_ml = suppressWarnings(as.numeric(`Prochlorococcus (number/ml)`)),
    synechococcus_n_ml   = suppressWarnings(as.numeric(`Synechococcus (number/ml)`)),
    picoeukaryotes_n_ml  = suppressWarnings(as.numeric(`Picoeukaryotes (number/ml)`)),
    notes            = na_if(Notes, "")) |>
  mutate(
    site_key = if_else(
      is.na(line) | is.na(station), NA_character_,
      sprintf("%05.1f %05.1f", line, station)),
    bottle_id = row_number())

n_all <- nrow(d_clean)
cat(glue("{format(n_all, big.mark=',')} rows read, no bounding-box filter applied ",
         "(source pre-scoped to CalCOFI/CCE cruises)"), "\n")
dbWriteTable(con, "picoplankton_bacteria_bottle", d_clean, overwrite = TRUE)
```
## Pivot Measurements to Long Format
Unlike ZooDB, this source has no analyzed-but-absent convention -- every
blank cell in the raw export is genuinely not measured (confirmed: zero
literal `0` values appear in Heterotrophic Bacteria or Prochlorococcus,
only blanks). So this pivot simply drops NA, with no explicit-zero
retention logic needed.
`measurement_type` codes are unit-less (`het_bacteria`, not
`het_bacteria_n_ml`) -- units live in `measurement_type.csv`'s `units`
column, matching the convention used by `bottle_measurement`/
`zoodb_measurement` elsewhere in the DB. An earlier draft baked the unit
into the type code itself; fixed here.
```{r}
#| label: pivot-long
pb_meas_map <- tribble(
  ~measurement_type,     ~value_col,
  "het_bacteria",         "het_bacteria_n_ml",
  "prochlorococcus",      "prochlorococcus_n_ml",
  "synechococcus",        "synechococcus_n_ml",
  "picoeukaryotes",       "picoeukaryotes_n_ml")

sql_parts <- purrr::pmap_chr(pb_meas_map, function(measurement_type, value_col) {
  glue(
    "SELECT bottle_id, '{measurement_type}' AS measurement_type,
     CAST({value_col} AS DOUBLE) AS measurement_value
     FROM picoplankton_bacteria_bottle WHERE {value_col} IS NOT NULL")
})

sql_create <- glue(
  "CREATE OR REPLACE TABLE picoplankton_bacteria_measurement AS
   SELECT ROW_NUMBER() OVER (ORDER BY bottle_id, measurement_type) AS measurement_id, *
   FROM (
     {paste(sql_parts, collapse = '\nUNION ALL\n')}
   ) sub")
dbExecute(con, sql_create)
n_meas <- dbGetQuery(con, "SELECT COUNT(*) FROM picoplankton_bacteria_measurement")[[1]]
cat(glue("picoplankton_bacteria_measurement: {format(n_meas, big.mark=',')} rows"), "\n")
for (col in pb_meas_map$value_col) {
  tryCatch(
    dbExecute(con, glue('ALTER TABLE picoplankton_bacteria_bottle DROP COLUMN "{col}"')),
    error = function(e) NULL)
}
```
## Register Measurement Types
Registers this dataset's `measurement_type` codes into the shared
`metadata/measurement_type.csv` and loads the `measurement_type` table into
this connection -- an earlier draft referenced `measurement_type` as a FK
target in Schema Documentation / Validate without ever creating it, which
would fail. Pattern matches `ingest_calcofi_phyllosoma.qmd`'s `finalize` step.
Two layers, since 2026-09-12 (measurement-faces plan D9, Ben's decision):
- The **four source codes** (`synechococcus`, `prochlorococcus`,
`picoeukaryotes`, `het_bacteria`) stay in the registry and stay the vocabulary
of the source-shaped `picoplankton_bacteria_measurement` table. They are **not
deleted** -- a registry row is statused, never removed -- but from this render
on they name a *taxon*, not an `obs` measurement type, so they stop appearing
in `obs_env` and therefore in the measurements catalog at the next release.
- One **canonical type**, `picoplankton_abundance`, is what `obs` carries. The
organism moves into `obs.taxon_key`, which is what puts these counts under
Biology beside every other cell count and gives *Synechococcus* and
*Prochlorococcus* a species page. It is registered with
`register_measurement_types()`, the helper that writes the registry with
`na = ""` and keeps it sorted.
```{r}
#| label: register-measurement-types
pb_types <- tribble(
  ~measurement_type, ~description,                              ~units,
  "het_bacteria",     "Heterotrophic bacteria abundance (FCM)",  "number/ml",
  "prochlorococcus",  "Prochlorococcus abundance (FCM); ~80% populated, see Q01", "number/ml",
  "synechococcus",    "Synechococcus abundance (FCM)",           "number/ml",
  "picoeukaryotes",   "Picoeukaryote abundance (FCM)",           "number/ml") |>
  mutate(is_canonical = TRUE,
         grain        = "obs",
         `_source_column` = case_when(
           measurement_type == "het_bacteria"    ~ "Heterotrophic Bacteria (number/ml)",
           measurement_type == "prochlorococcus" ~ "Prochlorococcus (number/ml)",
           measurement_type == "synechococcus"   ~ "Synechococcus (number/ml)",
           measurement_type == "picoeukaryotes"  ~ "Picoeukaryotes (number/ml)"),
         `_source_table` = "picoplankton_bacteria_measurement",
         `_source_datasets` = "cce-lter_picoplankton-bacteria",
         `_qual_column` = NA_character_, `_prec_column` = NA_character_)

# upsert so a units/description correction propagates on re-run, and keep the
# registry sorted so its on-disk order is deterministic across ingests
# upsert, not delete-and-replace: the literal below carries no valid_min/
# valid_max, and the naive `filter(!= x) |> bind_rows()` destroyed those
# curated bounds on every re-run (it silently un-declared euphausiid_abundance
# and the picoplankton types mid-release, failing the bounds gate).
d_meas_type <- upsert_measurement_types(d_meas_type, pb_types)
new_types <- pb_types
write_csv(d_meas_type, meas_type_csv, na = "")

# the canonical type `obs` carries. One quantity -- cells per millilitre by flow
# cytometry -- for all four populations; WHICH population is `obs.taxon_key`, not
# a suffix on the type name. No `nerc_p01`: P700A90Z / P701A90Z each name one
# organism's count, so neither is an exact concept for the pooled type, and an
# inexact controlled-vocabulary id is left empty by the registry rule. The two
# organism-specific P01s stay on their own rows above, where they are exact.
pb_canonical <- tribble(
  ~measurement_type,        ~description, ~units,
  "picoplankton_abundance",
  paste("Picoplankton and bacteria cell abundance by flow cytometry (FCM);",
        "the population counted is obs.taxon_key"),
  "number/ml") |>
  mutate(valid_min = 0, is_canonical = TRUE, grain = "obs",
         category  = "Picoplankton & Bacteria",
         `_source_column` = paste(
           "Synechococcus (number/ml)", "Prochlorococcus (number/ml)",
           "Picoeukaryotes (number/ml)", "Heterotrophic Bacteria (number/ml)",
           sep = "; "),
         `_source_table`    = "picoplankton_bacteria_measurement",
         `_source_datasets` = "cce-lter_picoplankton-bacteria",
         `_qual_column` = NA_character_, `_prec_column` = NA_character_,
         units_nerc_p06 = "http://vocab.nerc.ac.uk/collection/P06/current/UCML/")
d_meas_type <- register_measurement_types(pb_canonical, meas_type_csv)

dbWriteTable(con, "measurement_type", d_meas_type, overwrite = TRUE)
cat(glue("measurement_type: {nrow(d_meas_type)} types registered ",
         "({nrow(new_types)} source codes upserted, canonical ",
         "`picoplankton_abundance` registered)"), "\n")
```
## Resolve Ship and Cruise Keys
`cruise_key` in the shared `cruise` table is a natural key in format
`YYYY-MM-NODC`, built by the real `calcofi4db::derive_cruise_key_on_casts()`
function (confirmed from `ship.R`). That function needs a `ship_code` column
(matched against `ship.ship_nodc`) and a `datetime_utc` column, and accepts
the target table directly via `table_name=` (confirmed via
`ingest_calcofi_mets.qmd`'s usage) -- no need to rename anything to `casts`.
This source has no `ship_code` natively -- only `studyName` (e.g.
`2004-11-02-C-33RR`), whose trailing code (`33RR`) is the ship code embedded
in the string -- so extract that into a `ship_code` column, then call the
real function against `picoplankton_bacteria_bottle` directly rather than
reimplementing its SQL by hand (an earlier draft did this incorrectly).
```{r}
#| label: resolve-keys
load_prior_tables(
  con, parquet_dir = cc_stage_path("parquet", "swfsc_ichthyo"),
  tables = c("ship", "cruise", "grid"), geom_tables = c("grid"), as_view = TRUE)
# extract trailing ship code from studyName (e.g. "2004-11-02-C-33RR" -> "33RR")
# NOTE (Q02, resolved): verified against the live release DB for 3 sample
# codes (33RR, 32NM, 31JD); all matched real casts.parquet rows. Still not
# verified across all 73 distinct studyName formats in this dataset.
dbExecute(con, "
  ALTER TABLE picoplankton_bacteria_bottle ADD COLUMN IF NOT EXISTS ship_code VARCHAR")
dbExecute(con, "
  UPDATE picoplankton_bacteria_bottle
  SET ship_code = regexp_extract(study_name, '[0-9A-Z]+$')")
# the study's own designation ("2004-11-02-C-33RR" -> 200411, the cruise START
# month) is the fallback when no reference cruise's date span holds the sample
dbExecute(con, "
  ALTER TABLE picoplankton_bacteria_bottle ADD COLUMN IF NOT EXISTS cruise_ym VARCHAR")
dbExecute(con, "
  UPDATE picoplankton_bacteria_bottle
  SET cruise_ym = regexp_replace(study_name, '^(\\d{4})-(\\d{2}).*$', '\\1\\2')")
cruise_key_result <- derive_cruise_key_on_casts(
  con, table_name = "picoplankton_bacteria_bottle", datetime_col = "datetime_utc",
  cruise_ym_col = "cruise_ym")
cruise_key_result$key_stats |>
  datatable(caption = "cruise_key resolution: span > source designation > month")
n_ck <- dbGetQuery(con, "SELECT COUNT(*) FROM picoplankton_bacteria_bottle WHERE cruise_key IS NOT NULL")[[1]]
n_all <- dbGetQuery(con, "SELECT COUNT(*) FROM picoplankton_bacteria_bottle")[[1]]
cat(glue("cruise_key match: {n_ck}/{n_all} ({round(100*n_ck/n_all,1)}%)"), "\n")
```
## Add Spatial
```{r}
#| label: spatial
add_point_geom(con, "picoplankton_bacteria_bottle", lon_col = "longitude", lat_col = "latitude")
assign_grid_key(con, "picoplankton_bacteria_bottle") |> datatable(caption = "Grid assignment")
```
## Load Dataset Metadata
```{r}
#| label: load-dataset-metadata
d_dataset <- ingest_yaml_to_dataset_df(read_ingest_yaml(here()))
dbWriteTable(con, "dataset", d_dataset, overwrite = TRUE)
cat(glue("dataset: {nrow(d_dataset)} datasets registered"), "\n")
```
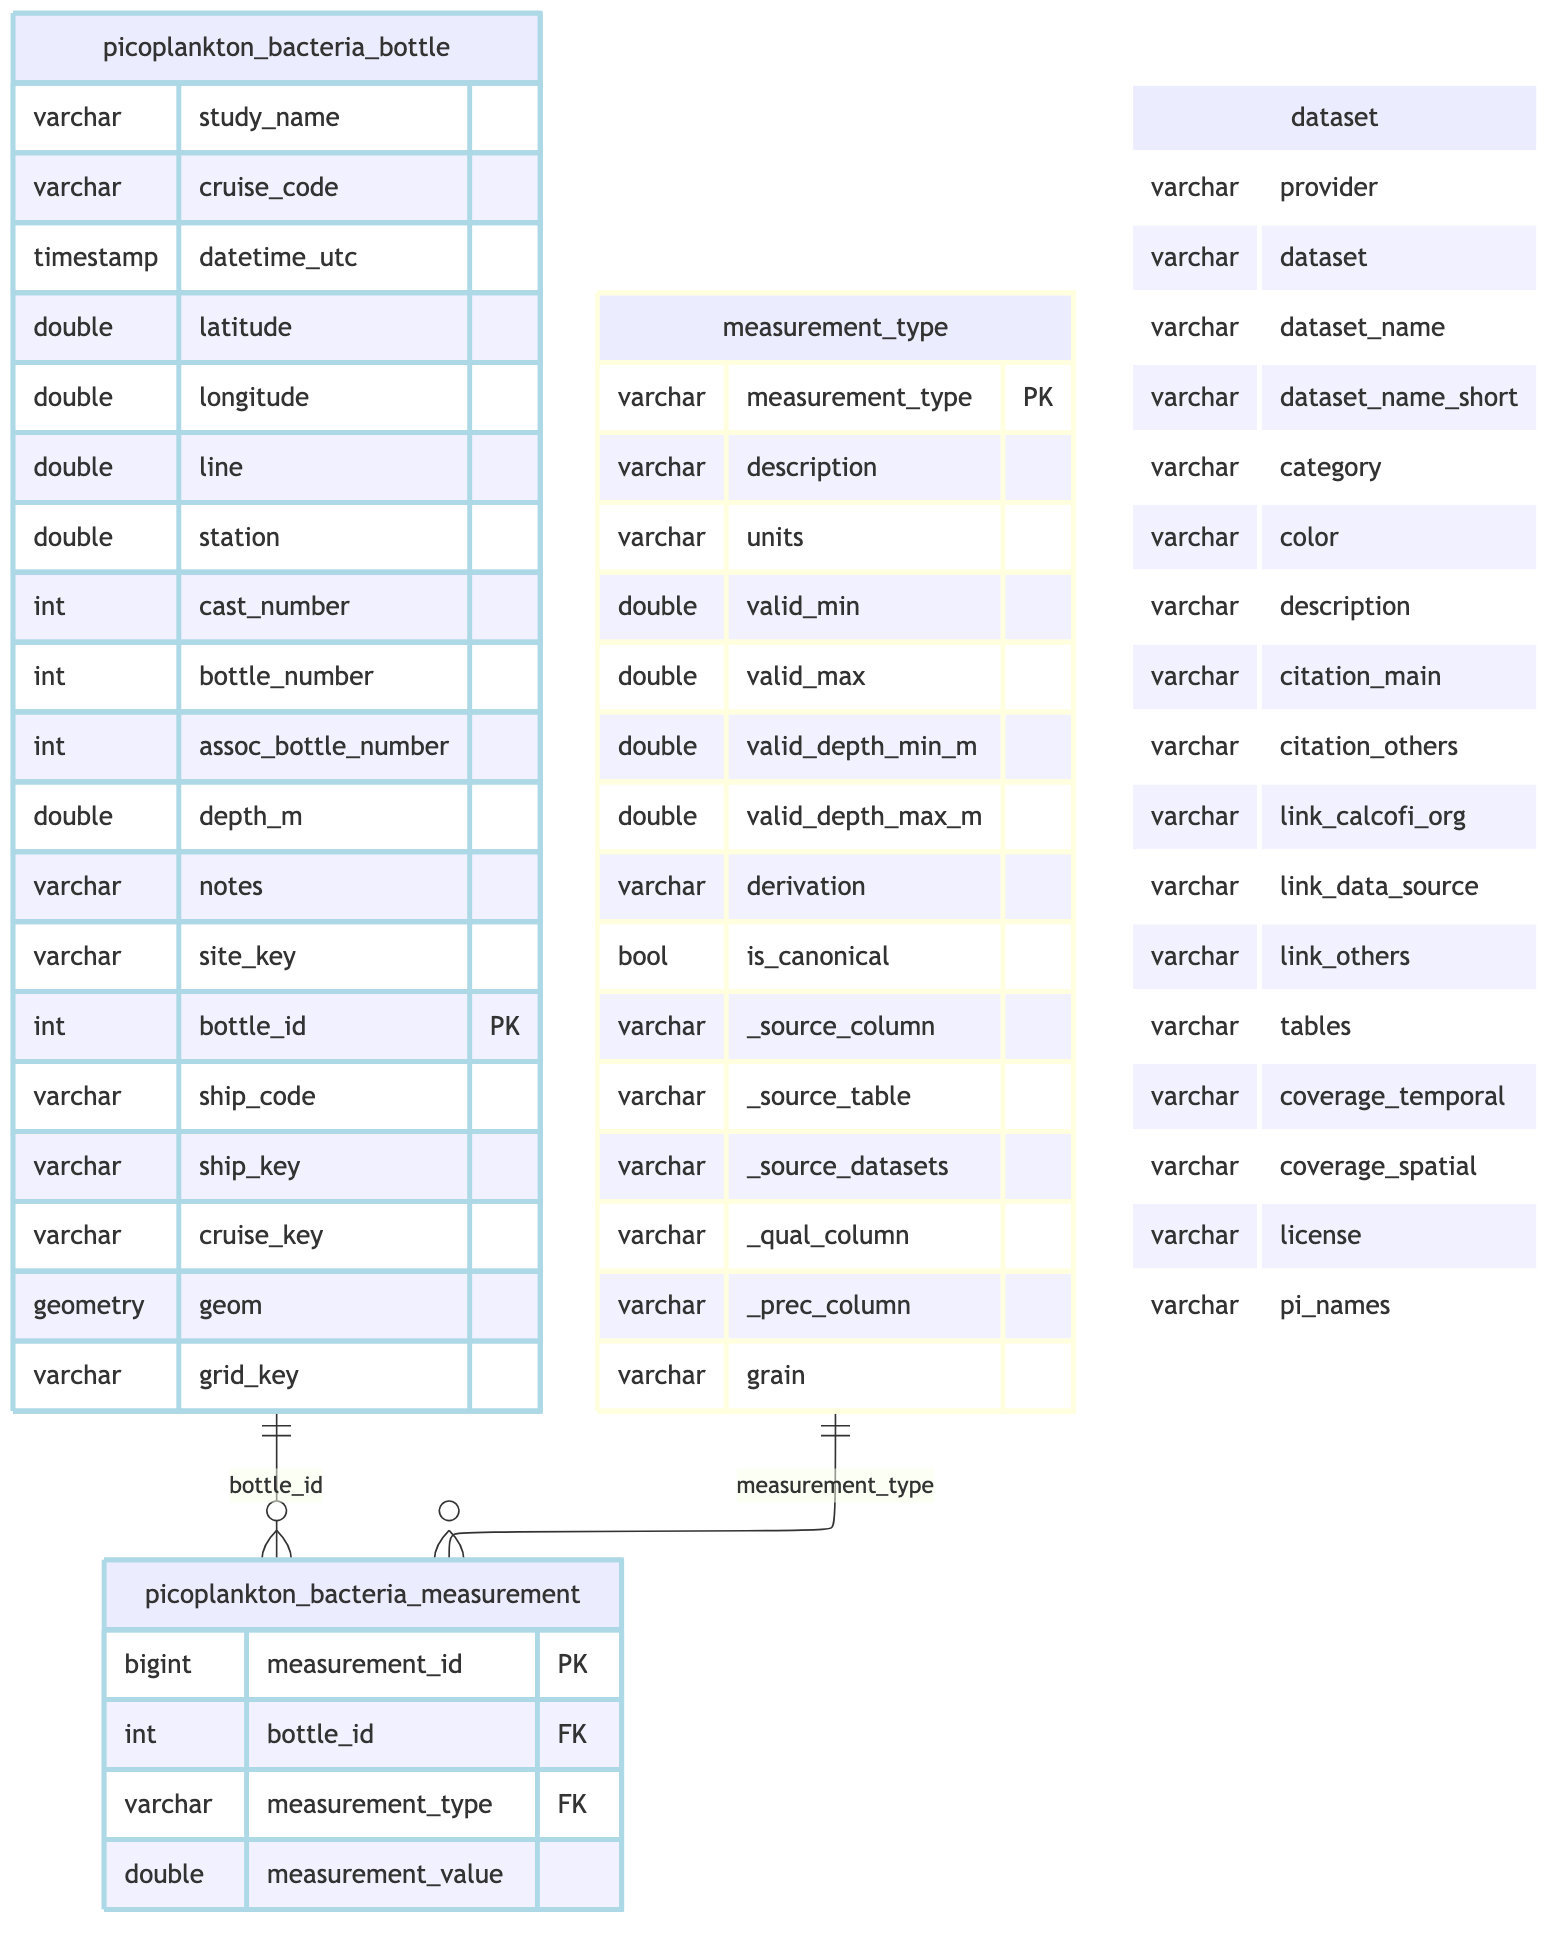
## Schema Documentation
```{r}
#| label: schema
pb_rels <- list(
  primary_keys = list(
    picoplankton_bacteria_bottle = "bottle_id",
    picoplankton_bacteria_measurement = "measurement_id",
    measurement_type = "measurement_type"),
  foreign_keys = list(
    list(table = "picoplankton_bacteria_measurement", column = "bottle_id",
         ref_table = "picoplankton_bacteria_bottle", ref_column = "bottle_id"),
    list(table = "picoplankton_bacteria_measurement", column = "measurement_type",
         ref_table = "measurement_type", ref_column = "measurement_type")))

cc_erd(
  con, tables = c("picoplankton_bacteria_bottle", "picoplankton_bacteria_measurement",
                  "measurement_type", "dataset"),
  rels = pb_rels,
  colors = list(lightblue = c("picoplankton_bacteria_bottle", "picoplankton_bacteria_measurement"),
                lightyellow = "measurement_type", white = "dataset"))
build_relationships_json(
  rels = pb_rels, output_dir = dir_parquet, provider = provider, dataset = dataset)
```
## Validate
```{r}
#| label: validate
results <- validate_for_release(con, checks = "all", strict = FALSE)
cat("Validation:", ifelse(results$passed, "PASSED", "FAILED"), "\n")
if (length(results$errors) > 0)
  cat("Errors:\n", paste("-", results$errors, collapse = "\n"), "\n")
# NULL cruise_key is the expected unmatched remainder pending confirmation of
# study_name -> cruise_key format (see Questions, Q02); not a hard failure.
n_dup <- dbGetQuery(con,
  "SELECT COUNT(*) FROM (SELECT bottle_id, COUNT(*) n FROM picoplankton_bacteria_bottle GROUP BY bottle_id HAVING COUNT(*)>1)")[[1]]
cat(glue("picoplankton_bacteria_bottle bottle_id duplicates: {n_dup}"), "\n")
n_orphan <- dbGetQuery(con,
  "SELECT COUNT(*) FROM picoplankton_bacteria_measurement m
   LEFT JOIN picoplankton_bacteria_bottle b ON m.bottle_id = b.bottle_id
   WHERE b.bottle_id IS NULL")[[1]]
cat(glue("Orphan measurements (no matching bottle): {n_orphan}"), "\n")
n_orphan_type <- dbGetQuery(con,
  "SELECT COUNT(*) FROM picoplankton_bacteria_measurement m
   WHERE m.measurement_type NOT IN (SELECT measurement_type FROM measurement_type)")[[1]]
cat(glue("Orphan measurement_types (not registered): {n_orphan_type}"), "\n")
```
## Data Preview
```{r}
#| label: preview
cols <- dbGetQuery(con,
  "SELECT column_name FROM information_schema.columns
   WHERE table_name='picoplankton_bacteria_bottle' AND data_type NOT LIKE 'GEOMETRY%'")$column_name
dbGetQuery(con, glue("SELECT {paste(cols, collapse=', ')} FROM picoplankton_bacteria_bottle LIMIT 100")) |>
  datatable(caption = "picoplankton_bacteria_bottle — first 100 rows", rownames = FALSE, filter = "top")
dbGetQuery(con, "SELECT * FROM picoplankton_bacteria_measurement LIMIT 100") |>
  datatable(caption = "picoplankton_bacteria_measurement — first 100 rows", rownames = FALSE, filter = "top")
```
## Emit Core Tables
Project this dataset into the shared consolidated core model
(`design_env-bio-consolidation.md`), the
same projection `release_database.qmd` uses to assemble the cross-dataset
release. This is a bottle-shaped sample — leaf grain `bottle_id`, and since the
export carries no cast-level event table the bottle is its own root — with an
`obs` headline of the four flow-cytometry counts.
**Realm `bio`, since 2026-09-12** (measurement-faces plan D9; Ben: these counts
belong under Biology, where the datasets catalog already files this dataset).
Until then the arm emitted `realm = 'env'` with a NULL `taxon_key`, on the
reading that "the four FCM types ARE the measurement vocabulary". They are not:
each one names an *organism* counted by the same instrument in the same units.
So the quantity is one canonical `measurement_type`
(`picoplankton_abundance`, cells per ml) and the organism is
`obs.taxon_key` — which is the shape every other cell count in the database
already has, and the only shape that reaches
`build_taxa_catalog()` (it reads `obs_bio`) so that
`/species/worms-160572/` is a page rather than a 404.
Two of the four populations are genera an authority keys — *Synechococcus*
(WoRMS 160572) and *Prochlorococcus* (WoRMS 345515), the same organisms NERC's
S25 attaches to the P01s `P700A90Z` and `P701A90Z` on the two registry rows.
The other two, `picoeukaryotes` and `het_bacteria`, are **operational classes**:
a size fraction of the eukaryotes and a trophic fraction of the bacteria, neither
of which is a taxon. Their identity is **not** dropped — they take a
dataset-local `taxon_key` (`cce-lter_picoplankton-bacteria:picoeukaryotes`,
`…:het_bacteria`) declared one at a time in `local_allow` below and in
`release_database.qmd`'s `TAXON_LOCAL_ALLOW`, exactly as ZooScan's
eggs / multiples / nauplii / others and phytoplankton's undefined codes do. That
is the established mechanism for a real class in the source that no authority can
key; `check_taxon_ids()` fails the release on any dataset-local key not on that
list, so a genuinely unresolved taxon cannot hide among them.
```{r}
#| label: emit_core
ds_key <- "cce-lter_picoplankton-bacteria"
# filter the crosswalk to THIS dataset -- an unfiltered read leaks other datasets'
# taxa into this shard. This dataset has no measurement_taxon.csv rows: the
# composite-decomposition registry is for an ingest whose taxon comes ONLY from a
# measurement_type name (cufes, phyllosoma, dungeness crab). Here the vocabulary
# is declared with append_dataset_taxon() instead, because that is the only path
# that mints a dataset-local key for the two operational classes -- and two
# sources of truth for one taxon_key is what the taxon plan's D1 removed.
mt_taxon <- read_csv(here("metadata/measurement_taxon.csv"),
                     col_types = cols(worms_id = "i", itis_id = "i",
                                      bin_value = "d", .default = "c")) |>
  filter(dataset_key == ds_key)
tx_over  <- read_csv(here("metadata/taxon_override.csv"), show_col_types = FALSE)

# This projection lives here, in the notebook that owns the dataset, not in a
# switch(dataset_key, ...) arm inside calcofi4db. The reusable SHAPES stay in the
# package (sample_arm_self / compat_measurement_sql), so this is a declaration.
#
# The vocabulary is DECLARED here and RESOLVED by the package (taxon plan D1,
# calcofi4db >= 3.29.0): append_dataset_taxon() stages one `dataset_taxon` row
# per source code with `taxon_key` empty and the AphiaID we supply carried along
# as `ds_source_json`; resolve_dataset_taxon() fills the key from the authorities
# and mints a dataset-local key where no authority answers. `ds_taxa_code` is the
# source's own measurement column name, VERBATIM, because that is what the
# measurement rows join on -- rewriting it would orphan every observation.
#
# The two AphiaIDs are not guesses: they are what NERC's S25 (biological entity)
# concept behind each P01 is owl:sameAs (probed 2026-09-11,
# .claude/plans/2026-09-11 measurement-faces-probe/nvs_probe.json).
d_vocab <- tibble::tribble(
  ~ds_taxa_code,      ~ds_scientific_name, ~ds_common_name,            ~worms_id, ~rank,
  # no ds_common_name for the two genera: the source supplies no vernacular, and
  # repeating the scientific name as a "common name" would publish one we invented
  "synechococcus",    "Synechococcus",     NA_character_,              160572L,   "Genus",
  "prochlorococcus",  "Prochlorococcus",   NA_character_,              345515L,   "Genus",
  # no scientific name to look up: a size class and a trophic class, not taxa
  "picoeukaryotes",   NA_character_,       "picoeukaryotes",           NA_integer_, NA_character_,
  "het_bacteria",     NA_character_,       "heterotrophic bacteria",   NA_integer_, NA_character_)
n_staged <- append_dataset_taxon(con, ds_key, d_vocab)

# cross-reference: resolve each taxon against BOTH authorities (cached in
# metadata/taxon_xref.csv, so a re-run costs no API calls). This fills the
# `worms_id` COLUMN on itis:-keyed taxa without touching their key, backfills
# `itis_id` the other way, replaces an id its authority has deprecated so the key
# is always an accepted id, and fetches the real `taxonomic_status` with the date
# it was checked. Must precede the lineage fetch, which should ask about the
# accepted id, not the deprecated one.
ensure_taxon_xref(con, mt_taxon, tx_over,
                  cache_csv = here("metadata/taxon_xref.csv"))

# lineage: fetch each taxon's WoRMS classification (cached in
# metadata/taxon_lineage.csv) and stage it as the `taxon` hierarchy
# build_taxon_reference() reads. Without it a taxon reaches the release with a
# key and a name and NOTHING else -- no rank, no parent_taxon_key, no
# classification -- so hierarchy rollups silently match nothing.
ensure_taxon_lineage(con, mt_taxon, tx_over,
                     cache_csv = here("metadata/taxon_lineage.csv"))
n_taxon    <- build_taxon_reference(con, mt_taxon, tx_over)
n_ds_taxon <- resolve_dataset_taxon(con, mt_taxon, tx_over)
n_tx_group <- build_taxon_group(con, read_taxon_group_rules(here("metadata/taxon_group.csv")))

# the ingest asserts its own crosswalk (D6). Two of the four populations are
# OPERATIONAL, not taxonomic, so they key dataset-locally BY DECLARATION -- one
# key at a time, with the reason, so a genuinely unresolved taxon cannot hide
# among them. The same two keys are declared in release_database.qmd's
# TAXON_LOCAL_ALLOW, which is the gate that fails the release.
local_allow <- tibble::tribble(
  ~ds_taxa_code,    ~why,
  "picoeukaryotes", "a <2-3 um SIZE fraction of the eukaryotic plankton, not a taxon",
  "het_bacteria",   "the heterotrophic (non-cyanobacterial) fraction of the bacteria, a TROPHIC class")
obs_codes <- dbGetQuery(con,
  "SELECT DISTINCT measurement_type AS c FROM picoplankton_bacteria_measurement")$c
chk_taxon <- check_dataset_taxon(
  con, ds_key, allow = paste0(ds_key, ":", local_allow$ds_taxa_code),
  codes = obs_codes)
cat(glue("vocabulary: {n_staged} populations staged; {nrow(local_allow)} keyed ",
         "dataset-locally by declaration; taxon {n_taxon}, ",
         "dataset_taxon {n_ds_taxon}, taxon_group {n_tx_group}"), "\n")
append_sample(con, sample_arm_self(
  ds_key, "picoplankton_bacteria_bottle", "bottle_id", "bottle",
  dt_col = "datetime_utc", site_expr = "site_key",
  depth_min = "depth_m", depth_max = "depth_m"))

# realm 'bio'; ONE measurement_type for the quantity, the organism in taxon_key.
# The join to dataset_taxon is INNER on purpose: a source column that never
# reached the vocabulary would silently vanish from obs, and the parity assert
# below (n_obs == every measurement row) is what catches it.
append_obs(con, glue("
  SELECT 'bio', '{ds_key}', {ns_key(ds_key, 'bottle', 'b.bottle_id')},
         b.grid_key, b.cruise_key, b.latitude, b.longitude,
         CAST(b.datetime_utc AS TIMESTAMP), b.depth_m, b.depth_m,
         dt.taxon_key, NULL::VARCHAR, 'picoplankton_abundance', m.measurement_value,
         NULL::VARCHAR, NULL::DOUBLE
  FROM picoplankton_bacteria_measurement m
  JOIN picoplankton_bacteria_bottle b USING (bottle_id)
  JOIN dataset_taxon dt ON dt.dataset_key = '{ds_key}'
                       AND dt.ds_taxa_code = m.measurement_type"))

core <- list(
  sample        = dbGetQuery(con, "SELECT COUNT(*) FROM sample")[[1]],
  obs           = dbGetQuery(con, "SELECT COUNT(*) FROM obs")[[1]],
  taxon         = n_taxon,
  dataset_taxon = n_ds_taxon,
  taxon_group   = n_tx_group)
cat(glue(
  "core projection — sample={core$sample %||% 0} obs={core$obs %||% 0} ",
  "taxon={core$taxon %||% 0} dataset_taxon={core$dataset_taxon %||% 0} ",
  "taxon_group={core$taxon_group %||% 0}\n"))
# every measurement on a bottle must reach obs, and must reach it WITH a taxon
n_obs <- dbGetQuery(con, "SELECT COUNT(*) FROM obs")[[1]]
n_exp <- dbGetQuery(con,
  "SELECT COUNT(*) FROM picoplankton_bacteria_measurement m
   JOIN picoplankton_bacteria_bottle b USING (bottle_id)")[[1]]
stopifnot(
  "obs must be one row per measurement" = n_obs == n_exp,
  "every picoplankton obs must carry a taxon_key" =
    dbGetQuery(con, "SELECT COUNT(*) FROM obs WHERE taxon_key IS NULL")[[1]] == 0,
  "obs must carry exactly one measurement_type" =
    dbGetQuery(con, "SELECT COUNT(DISTINCT measurement_type) FROM obs")[[1]] == 1)
cat(glue("obs parity: {format(n_obs, big.mark=',')} rows, all taxon-resolved"), "\n")
dbGetQuery(con, "
  SELECT o.taxon_key, t.scientific_name, t.rank, COUNT(*) AS n_obs,
         COUNT(*) FILTER (WHERE o.measurement_value > 0) AS n_present,
         MIN(year(o.datetime)) AS year_min, MAX(year(o.datetime)) AS year_max
  FROM obs o LEFT JOIN taxon t USING (taxon_key)
  GROUP BY ALL ORDER BY n_obs DESC") |>
  datatable(caption = paste(
    "obs by taxon — what the species catalog will count. The two genera get a",
    "page at /species/worms-160572/ and /species/worms-345515/; the two",
    "operational classes keep their identity in a declared dataset-local key."),
    rownames = FALSE)
stopifnot(
  "every obs.sample_key must resolve in sample" =
    dbGetQuery(con, "SELECT COUNT(*) FROM obs o LEFT JOIN sample s USING (sample_key)
                     WHERE s.sample_key IS NULL")[[1]] == 0)
# serve the retired per-dataset table name as a VIEW over the core, so
# in-notebook consumers and ad-hoc queries keep working against the old name.
# Written out rather than taken from compat_measurement_sql(): that shape returns
# obs.measurement_type, which is now the canonical `picoplankton_abundance` for
# every row, so the view would lose the very thing this table is keyed by. The
# source's own column name comes back from dataset_taxon.ds_taxa_code, which is
# where it is now stored verbatim.
invisible(dbExecute(con, "DROP TABLE IF EXISTS picoplankton_bacteria_measurement_src"))
invisible(dbExecute(con, "ALTER TABLE picoplankton_bacteria_measurement RENAME TO picoplankton_bacteria_measurement_src"))
invisible(dbExecute(con, glue(
  "CREATE OR REPLACE VIEW picoplankton_bacteria_measurement AS
   SELECT o.obs_id                          AS measurement_id,
          split_part(o.sample_key, ':', 3)  AS bottle_id,
          dt.ds_taxa_code                   AS measurement_type,
          o.measurement_value, o.measurement_qual
   FROM obs o
   LEFT JOIN dataset_taxon dt ON dt.dataset_key = '{ds_key}'
                             AND dt.taxon_key   = o.taxon_key
   WHERE o.dataset_key = '{ds_key}'")))
cat(glue("compat view picoplankton_bacteria_measurement over obs: ",
         "{dbGetQuery(con, 'SELECT COUNT(*) FROM picoplankton_bacteria_measurement')[[1]]} rows"), "\n")
```
## Write Parquet Outputs
```{r}
#| label: write-parquet
dir_create(dir_parquet)
mismatches <- list(cruise_keys = collect_cruise_key_mismatches(con, "picoplankton_bacteria_bottle"))
tbls_out <- core_output_tables(con, extra = c("measurement_type", "dataset"))
parquet_stats <- write_parquet_outputs(
  con = con, output_dir = dir_parquet,
  tables = tbls_out,
  sort_by = list(obs = c("grid_key", "measurement_type")),
  strip_provenance = FALSE, mismatches = mismatches)

build_relationships_json(
  rels = core_relationships(tbls_out), output_dir = dir_parquet,
  provider = provider, dataset = dataset)
parquet_stats |> mutate(file = basename(path)) |> select(-path) |>
  datatable(caption = "Parquet export statistics")
```
## Write Metadata
```{r}
#| label: write-metadata
d_tbls_rd <- read_csv(here("metadata/cce-lter/picoplankton-bacteria/tbls_redefine.csv"))
d_flds_rd <- read_csv(here("metadata/cce-lter/picoplankton-bacteria/flds_redefine.csv"))
metadata_path <- build_metadata_json(
  con = con, d_tbls_rd = d_tbls_rd, d_flds_rd = d_flds_rd,
  metadata_derived_csv = c(here("metadata/core_dictionary.csv"),
                           here("metadata/cce-lter/picoplankton-bacteria/metadata_derived.csv")),
  output_dir = dir_parquet, tables = tbls_out,
  set_comments = TRUE, provider = provider, dataset = dataset,
  workflow_url = cc$workflow_url, tables_owned = tables_owned)
```
## Upload to GCS
```{r}
#| label: upload-gcs
if (Sys.getenv("CALCOFI_SKIP_GCS") == "") {
  sync_to_gcs(local_dir = dir_stage, sidecar_dir = dir_parquet, gcs_prefix = glue("ingest/{dir_label}"), bucket = "calcofi-db")
} else cat("CALCOFI_SKIP_GCS set — skipping the upload (local verification run)\n")
```
## Questions for Data Providers
Follow-up questions for CCE-LTER (Michael Landry), ranked by importance.
Tracked in `metadata/cce-lter/picoplankton-bacteria/questions.csv`.
```{r}
#| label: provider-questions
# one validated read + render for every ingest: the vocabulary and the column
# order live in calcofi4db, not in 16 hand-written factor() calls
questions_datatable(
  here(cc$questions_file),
  caption = "Questions for the CCE-LTER picoplankton/bacteria data providers (ranked)")
```
## Cleanup
```{r}
#| label: cleanup
close_duckdb(con)
cat(glue("Parquet outputs written to: {dir_parquet}"), "\n")
```