---
title: "Ingest CalCOFI CTD Derived Hydrographic Products"
calcofi:
target_name: ingest_calcofi_ctd_derived
workflow_type: ingest
dependency:
- ingest_calcofi_ctd_cast
output: data/parquet/calcofi_ctd-derived/manifest.json
provider: calcofi
dataset: ctd-derived
workflow_url: https://calcofi.io/workflows/ingest_calcofi_ctd-derived.html
questions_file: metadata/calcofi/ctd-derived/questions.csv
# in the release: Ben (2026-09-23) decided to build with the current defaults and
# tweak them once Rasmus answers Q01-Q05, so nothing here is a blocker
in_release: true
dataset_meta:
dataset_name: CalCOFI CTD Derived Hydrographic Products
dataset_name_short: CTD Derived Products
category: Physical Oceanography
color: "#0f7a5a"
# publishes no `sample`: every row hangs off the calcofi_ctd-cast cast it was
# computed from, so the cast keeps ONE sample row (sample_key is globally unique
# across shards and a second copy would fail assemble_core())
tables_owned:
- {table: obs, shared: true, note: "per-bin spiciness0 + sigma_theta_ave at the depths calcofi_ctd-cast publishes in obs"}
- {table: sample_measurement, shared: true, note: "per-cast mixed-layer depth (3 criteria), chlorophyll-a maximum, integrated chlorophyll-a"}
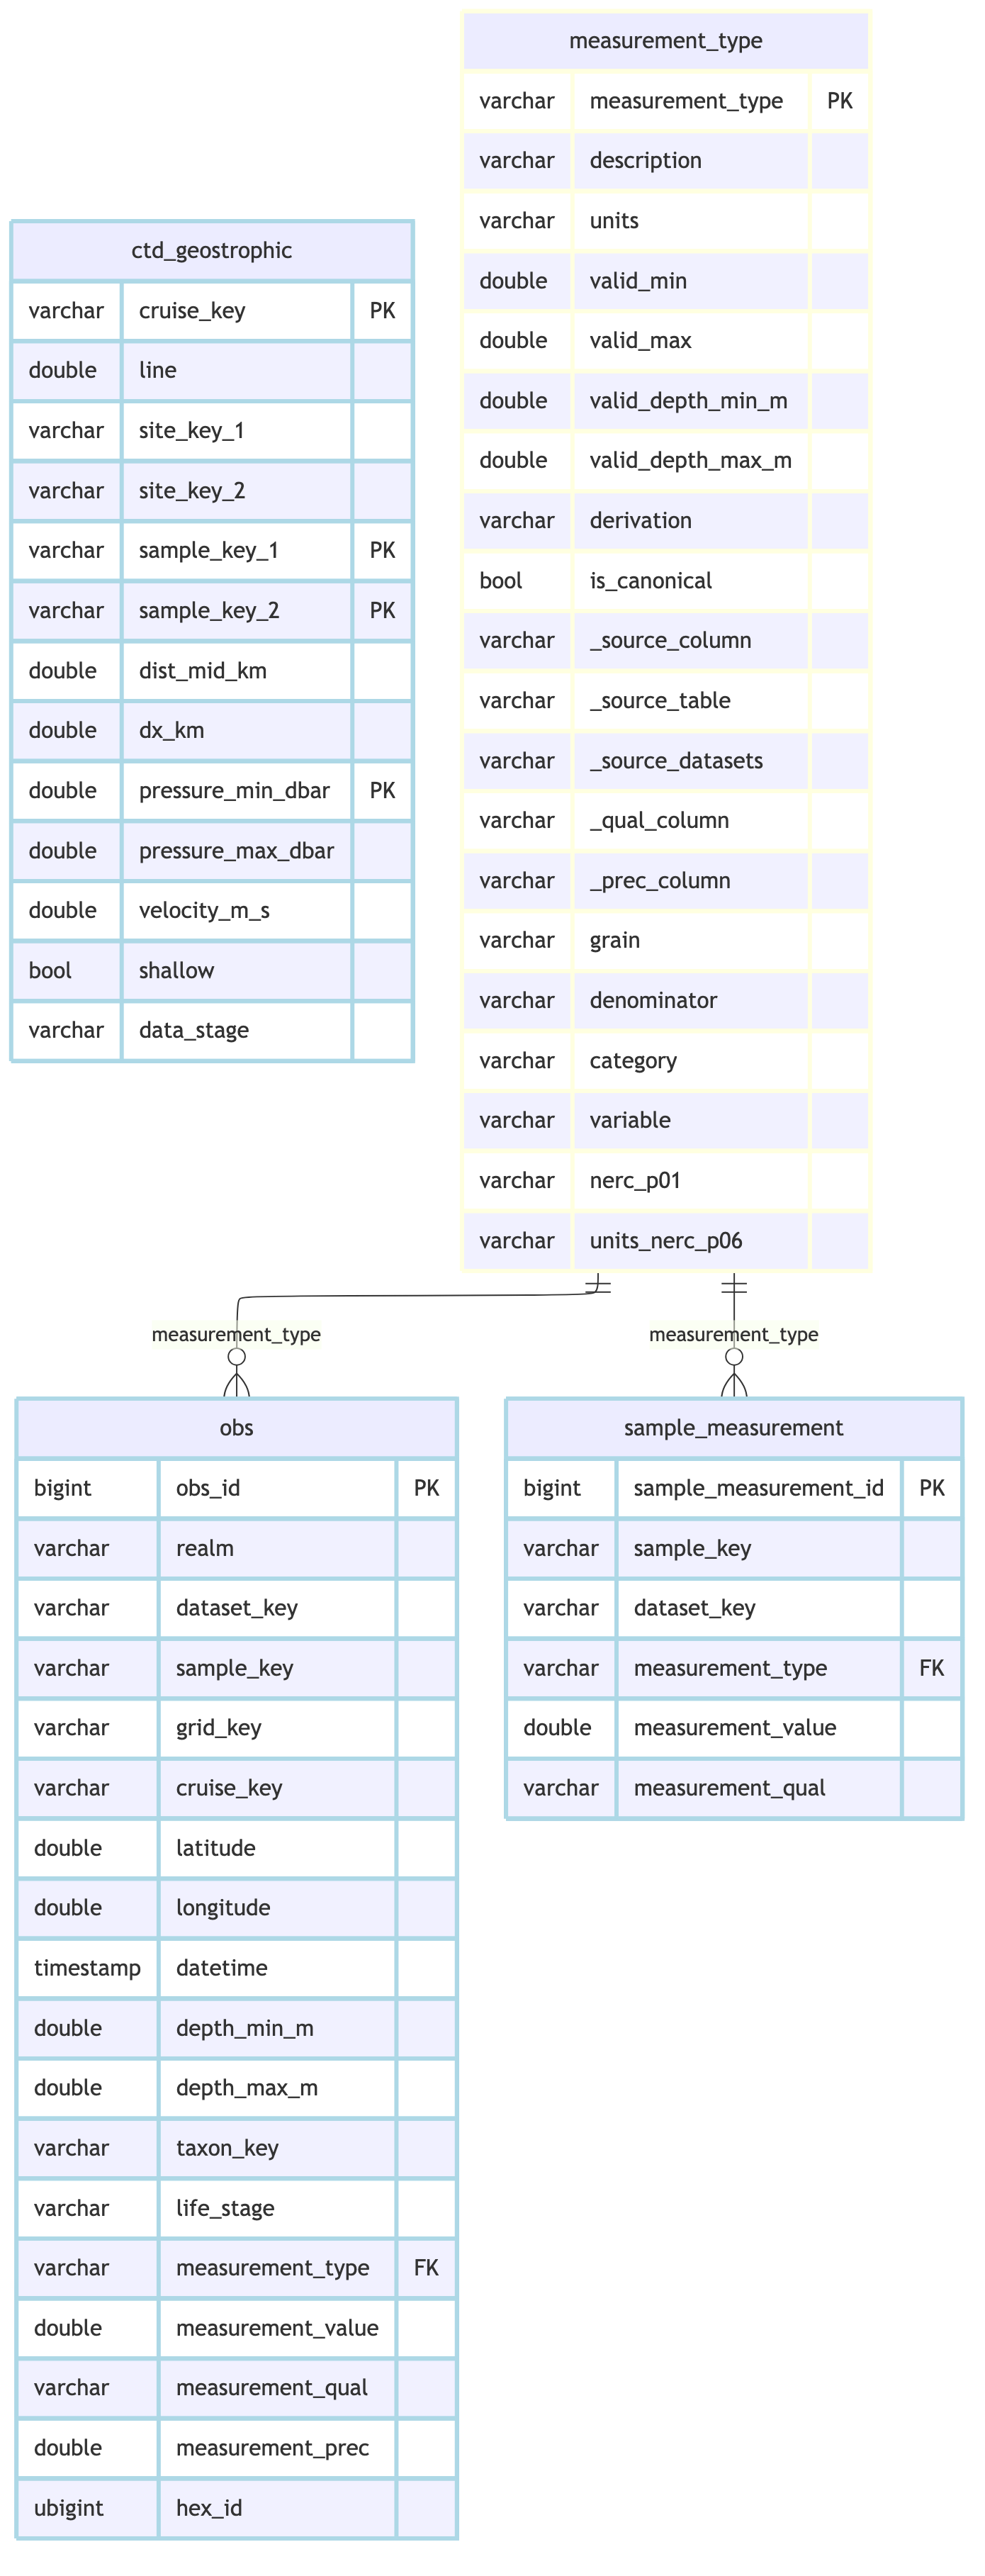
- {table: ctd_geostrophic, note: "relative geostrophic velocity between adjacent stations, per cruise and line, 10 dbar bins"}
- {table: measurement_type, shared: true, note: "shared registry across datasets"}
erd:
color: "#cfe8dc"
editor_options:
chunk_output_type: console
---
## Overview
Hydrographic products **derived** from the CalCOFI CTD cast profiles rather than
measured, asked for by Rasmus Swalethorp (CTD-on-EDI meeting 2026-09-16; email
2026-09-22) to show, cruise by cruise, "how much upwelling might be going on on our
grid at that specific time of the cruise, how much productivity might there be" and
the California Undercurrent an El Niño should strengthen. The plan is
[CalCOFI/workflows#98](https://github.com/CalCOFI/workflows/issues/98), one issue per
product (#99–#103); the prototype on one cruise was
`explore_calcofi_ctd-derived.qmd` (workflows#107).
- **Source**: the `calcofi_ctd-cast` ingest's full-resolution 1 m bins
(`obs_ctd_full`), read from its staged output when that is current, otherwise
from the release — see [Input](#input).
- **Every rule is a tested calcofi4db function** (≥ 4.16.0): `ctd_spice()`,
`ctd_sigma_theta_ave()`, `ctd_mld()`, `ctd_chl_max()`, `ctd_integrate()`,
`ctd_geostrophic()`. This notebook only applies them.
- **Defaults are provisional**: Ben (2026-09-23) decided to build with the current
defaults and tweak once Rasmus answers — the five open choices are
[Questions](#questions-for-data-providers) Q01–Q05.
```{mermaid}
graph LR
  A[calcofi_ctd-cast<br/>obs_ctd_full, 1 m bins] --> B[drop 8/9 flags<br/>tier rule]
  B --> C[per bin: spiciness0,<br/>sigma_theta_ave]
  B --> D[per cast: MLD x3,<br/>chl max, integrated chl]
  B --> E[per station pair:<br/>geostrophic velocity]
  C --> F[(obs, at the depths<br/>ctd-cast publishes)]
  D --> G[(sample_measurement<br/>on the ctd-cast cast)]
  E --> H[(ctd_geostrophic)]
```
**The tier rule.** `final` and `preliminary_with_bottle` casts get every product.
`preliminary_without_bottle` casts have no bottle-corrected salinity and no
chlorophyll estimate, so they get **only the temperature-criterion MLD** — nothing
salinity-based (Rasmus, 2026-09-09: uncorrected sensors are not shown).
## Setup
```{r}
#| label: setup
devtools::load_all(here::here("../calcofi4db"))
librarian::shelf(
  CalCOFI/calcofi4db, CalCOFI/calcofi4r,
  DBI, dplyr, DT, fs, glue, here, jsonlite, purrr, readr, tibble, tidyr,
  quiet = T)
options(readr.show_col_types = F)
options(DT.options = list(scrollX = TRUE))
stopifnot(
  "calcofi4db >= 4.16.0 carries the ctd_* derived-product rules" =
    exists("ctd_geostrophic", mode = "function"))

source(here("libs/ingest.R"))
cc <- read_calcofi_meta(here("ingest_calcofi_ctd-derived.qmd"))
provider     <- cc$provider
dataset      <- cc$dataset
dataset_name <- cc$dataset_meta$dataset_name
tables_owned <- cc$tables_owned
ds_key       <- glue("{provider}_{dataset}")
src_key      <- "calcofi_ctd-cast"
dir_label    <- ds_key
dir_meta     <- here(glue("metadata/{provider}/{dataset}"))
dir_parquet  <- here(glue("data/parquet/{dir_label}"))
dir_stage    <- cc_stage_path("parquet", dir_label, create = TRUE)
db_path      <- here(glue("data/wrangling/{dir_label}.duckdb"))
meas_type_csv <- here("metadata/measurement_type.csv")

# the defaults awaiting Rasmus (questions Q01-Q05), in one place
p <- list(
  mld_ref_m   = 10,       # Q01
  mld_sigma   = c(0.03, 0.125),
  mld_temp    = 0.2,
  chl_window  = 5,        # Q02
  chl_z_max   = 200,
  chl_top_max = 5,
  geo_p_ref   = 500,      # Q03
  geo_min_dx  = 10,       # Q04
  geo_bin     = 10)
tier_full <- c("final", "preliminary_with_bottle")

# a DuckDB memory ceiling sized to the machine (40 % of RAM, at most 8 GB) unless
# the environment sets one: this runs on a laptop beside everything else
ram_gb <- tryCatch({
  if (Sys.info()[["sysname"]] == "Darwin")
    as.numeric(system("sysctl -n hw.memsize", intern = TRUE)) / 2^30
  else as.numeric(sub("\\D+(\\d+).*", "\\1",
                      grep("^MemTotal", readLines("/proc/meminfo"), value = TRUE))) / 2^20
}, error = function(e) 8)
mem_limit <- Sys.getenv("CALCOFI_DUCKDB_MEMORY_LIMIT",
                        glue("{max(1, floor(min(8, 0.4 * ram_gb)))}GB"))
cat(glue("DuckDB memory_limit {mem_limit} (RAM {round(ram_gb)} GB)"), "\n")
if (overwrite) {
  for (f in c(db_path, paste0(db_path, ".wal"))) if (file_exists(f)) file_delete(f)
  if (dir_exists(paste0(db_path, ".tmp"))) dir_delete(paste0(db_path, ".tmp"))
}
dir_create(dirname(db_path))
con <- get_duckdb_con(db_path, config = list(memory_limit = mem_limit))
```
## Input {#input}
The derived products are computed from the **full-resolution** 1 m bins, never from
the thinned series in `obs`: an MLD or a chlorophyll maximum read off a 10 m grid is
biased toward the grid. The preferred input is the `calcofi_ctd-cast` ingest's own
staged output under `cc_stage_dir()` — the bytes the next release will be cut from —
used only if it is **current**: every partition's row count must equal what that
ingest's committed `manifest.json` recorded (its `data_hash` starts with the row
count). Otherwise the notebook reads the promoted release's `obs_ctd_full` through the
resolver helpers (`cc_catalog()` / `cc_release_sources()`), never a hand-built path.
```{r}
#| label: input
dir_src <- cc_stage_path("parquet", src_key)
mf_src  <- read_json(here(glue("data/parquet/{src_key}/manifest.json")))
rows_of <- function(h) as.numeric(sub(":.*$", "", h))

stage_current <- local({
  if (!dir_exists(dir_src)) return(FALSE)
  exp_full <- vapply(mf_src$data_hash$obs_ctd_full, rows_of, numeric(1))
  exp_obs  <- vapply(mf_src$data_hash$obs, rows_of, numeric(1))
  exp_smp  <- rows_of(mf_src$data_hash$sample)
  cnt <- function(sub, ck) {
    f <- dir_ls(path(dir_src, sub, glue("cruise_key={ck}")), glob = "*.parquet")
    if (!length(f)) return(NA_real_)
    dbGetQuery(con, glue("SELECT COUNT(*) AS n FROM read_parquet([{paste0(\"'\", f, \"'\", collapse = ',')}])"))$n
  }
  got_full <- vapply(names(exp_full), function(ck) cnt("obs_ctd_full", ck), numeric(1))
  got_obs  <- vapply(names(exp_obs),  function(ck) cnt("obs", ck), numeric(1))
  got_smp  <- dbGetQuery(con, glue("SELECT COUNT(*) AS n FROM read_parquet('{dir_src}/sample.parquet')"))$n
  ok <- identical(unname(got_full), unname(exp_full)) &&
        identical(unname(got_obs), unname(exp_obs)) && got_smp == exp_smp
  cat(glue(
    "stage {dir_src}: obs_ctd_full {sum(got_full, na.rm = TRUE)} / {sum(exp_full)} rows over ",
    "{length(exp_full)} partitions, obs {sum(got_obs, na.rm = TRUE)} / {sum(exp_obs)}, ",
    "sample {got_smp} / {exp_smp} -> {if (ok) 'CURRENT' else 'NOT current'}"), "\n")
  ok
})
if (stage_current) {
  input_used <- glue("staged calcofi_ctd-cast output ({dir_src}), current against its committed manifest.json")
  src_full_of <- function(ck) glue("read_parquet('{dir_src}/obs_ctd_full/cruise_key={ck}/*.parquet')")
  dbExecute(con, glue("CREATE OR REPLACE VIEW src_obs AS SELECT * FROM read_parquet('{dir_src}/obs/*/*.parquet', hive_partitioning = true)"))
  dbExecute(con, glue("CREATE OR REPLACE VIEW src_sample AS SELECT * FROM read_parquet('{dir_src}/sample.parquet')"))
} else {
  librarian::shelf(CalCOFI/calcofi4r, quiet = T)
  cat_ <- calcofi4r::cc_catalog("latest")
  input_used <- glue("release {cat_$version} obs_ctd_full via cc_release_sources() (the stage was absent or not current)")
  invisible(dbExecute(con, "INSTALL httpfs; LOAD httpfs"))
  src_f <- calcofi4r::cc_release_sources(cat_, "obs_ctd_full")
  src_full_of <- function(ck) {
    u <- grep(glue("cruise_key={ck}/"), src_f$urls, fixed = TRUE, value = TRUE)
    glue("read_parquet([{paste0(\"'\", u, \"'\", collapse = ',')}], hive_partitioning = true)")
  }
  # the thinned CTD headline lives in obs_env since v2026.09 (obs is a view)
  dbExecute(con, paste0("CREATE OR REPLACE VIEW src_obs AS SELECT * EXCLUDE (value), value AS measurement_value FROM ",
    calcofi4r::cc_read_parquet_sql(calcofi4r::cc_release_sources(cat_, "obs_env")),
    " WHERE dataset_key = 'calcofi_ctd-cast'"))
  dbExecute(con, paste0("CREATE OR REPLACE VIEW src_sample AS SELECT * FROM ",
    calcofi4r::cc_read_parquet_sql(calcofi4r::cc_release_sources(cat_, "sample"))))
}
cat(glue("input: {input_used}"), "\n")
```
## Casts
One cast per station occupation: exactly the casts `calcofi_ctd-cast` publishes in
`obs` (the down cast; the up cast only where no down cast exists — Q05), so a
derived value always sits on a cast a consumer can already see.
```{r}
#| label: casts
dbExecute(con, glue("
  CREATE OR REPLACE TABLE casts AS
  SELECT s.sample_key, s.cruise_key, s.site_key, s.grid_key, s.data_stage,
         s.datetime, s.latitude, s.longitude
  FROM src_sample s
  WHERE s.dataset_key = '{src_key}' AND s.sample_type = 'cast'
    AND s.sample_key IN (
      SELECT DISTINCT sample_key FROM src_obs WHERE measurement_type = 'temperature_ave')"))
d_casts <- dbGetQuery(con, "SELECT * FROM casts")
d_casts |>
  count(data_stage, dir = substr(sample_key, nchar(sample_key), nchar(sample_key)),
        name = "casts") |>
  datatable(caption = "Casts by data_stage and direction (d = down, u = up)", rownames = FALSE)
stopifnot(
  "a cast must have a data_stage" = !anyNA(d_casts$data_stage),
  "an unknown data_stage" = all(d_casts$data_stage %in% c(tier_full, "preliminary_without_bottle")))
```
## Compute the Products
Per cruise, the needed series are pivoted to one row per (cast, 1 m bin) with their
provider flags, then the calcofi4db rules run. A flag of 8 or 9 is dropped before
anything is computed — each function does it itself, from the flag passed beside
the value. The sensor-pair averages (`temperature_ave`, `salinity_ave_corr`) come
already rebuilt by the provider's flags in the ctd-cast ingest.
```{r}
#| label: compute
types <- c(
  "pressure", "temperature_ave", "salinity_ave_corr", "sigma_theta_1", "sigma_theta_2",
  "est_chlorophyll_a_sta_corr")
pivot_sql <- function(ck) {
  # a 1 m bin can hold two scans (the file repeats a depth); the value is their mean
  # and the flag is 8/9 if EITHER scan is flagged, else whatever code the scans carry
  # (a bare MAX() would let the string 'nan' outrank '9' and lose the flag)
  flg <- "regexp_replace(CAST(measurement_qual AS VARCHAR), '\\.0+$', '') IN ('8', '9')"
  cols <- unlist(lapply(types, function(tp) c(
    glue("AVG(measurement_value) FILTER (WHERE measurement_type = '{tp}') AS \"{tp}\""),
    glue("COALESCE(
            MAX(measurement_qual) FILTER (WHERE measurement_type = '{tp}' AND {flg}),
            MAX(measurement_qual) FILTER (WHERE measurement_type = '{tp}' AND measurement_qual NOT IN ('nan', '')))
          AS \"q_{tp}\""))))
  glue("
    SELECT f.sample_key, f.depth_min_m AS depth_m,
           ANY_VALUE(f.latitude) AS latitude, ANY_VALUE(f.longitude) AS longitude,
           {paste(cols, collapse = ',\n           ')}
    FROM {src_full_of(ck)} f
    WHERE f.sample_key IN (SELECT sample_key FROM casts WHERE cruise_key = '{ck}')
      AND f.measurement_type IN ({paste0(\"'\", types, \"'\", collapse = ', ')})
    GROUP BY f.sample_key, f.depth_min_m")
}

# the same flag normalization the rules use ("8.0" == "8")
is_flagged <- function(q) sub("\\.0+$", "", as.character(q)) %in% c("8", "9")

for (tb in c("bin_full", "cast_products", "geo_raw"))
  dbExecute(con, glue("DROP TABLE IF EXISTS {tb}"))
flag_audit <- list()
t0 <- Sys.time()
cruises <- sort(unique(d_casts$cruise_key))
# diagnostics only (purl + source): the first n cruises; a real render leaves it unset
if (nzchar(Sys.getenv("CTD_DERIVED_TEST_N"))) cruises <- head(cruises, as.integer(Sys.getenv("CTD_DERIVED_TEST_N")))

for (ck in cruises) {
  cst <- filter(d_casts, cruise_key == ck)
  d <- dbGetQuery(con, pivot_sql(ck)) |>
    left_join(select(cst, sample_key, data_stage, site_key), by = "sample_key") |>
    arrange(sample_key, depth_m)
  if (!nrow(d)) next
  full <- d$data_stage %in% tier_full
  # pressure where the file has it, else depth (< 1 % apart above 500 m)
  pr <- coalesce(d$pressure, d$depth_m)
  d$pr <- pr

  # per bin (full tier only) ----
  d$sigma_theta_ave <- ifelse(full, ctd_sigma_theta_ave(
    d$sigma_theta_1, d$sigma_theta_2, d$q_sigma_theta_1, d$q_sigma_theta_2), NA_real_)
  d$spiciness0 <- NA_real_
  if (any(full))
    d$spiciness0[full] <- ctd_spice(
      d$temperature_ave[full], d$salinity_ave_corr[full], pr[full],
      d$longitude[full], d$latitude[full],
      d$q_temperature_ave[full], d$q_salinity_ave_corr[full])
  flag_audit[[ck]] <- tibble(
    cruise_key = ck,
    bins = nrow(d),
    s1_flagged_s2_good = sum(full & is_flagged(d$q_sigma_theta_1) & !is_flagged(d$q_sigma_theta_2) &
                               !is.na(d$sigma_theta_2)),
    avg_equals_s2 = sum(full & is_flagged(d$q_sigma_theta_1) & !is_flagged(d$q_sigma_theta_2) &
                          !is.na(d$sigma_theta_2) & abs(d$sigma_theta_ave - d$sigma_theta_2) < 1e-12,
                        na.rm = TRUE),
    both_flagged_avg_present = sum(full & is_flagged(d$q_sigma_theta_1) & is_flagged(d$q_sigma_theta_2) &
                                     !is.na(d$sigma_theta_ave)),
    ts_flagged_spice_present = sum(full & (is_flagged(d$q_temperature_ave) | is_flagged(d$q_salinity_ave_corr)) &
                                     !is.na(d$spiciness0)))
  b <- d[full & (!is.na(d$sigma_theta_ave) | !is.na(d$spiciness0)),
         c("sample_key", "depth_m", "sigma_theta_ave", "spiciness0")]
  if (nrow(b)) dbWriteTable(con, "bin_full", as.data.frame(b), append = TRUE)

  # per cast ----
  pc <- d |>
    group_by(sample_key, data_stage) |>
    group_modify(function(x, k) {
      is_full <- k$data_stage %in% tier_full
      out <- list(
        ctd_mld(x$depth_m, x$temperature_ave, x$q_temperature_ave, criterion = "temperature",
                threshold = p$mld_temp, ref_depth = p$mld_ref_m) |>
          transmute(measurement_type = "mld_temperature_02", value = mld_m))
      if (is_full) {
        out <- c(out, list(
          ctd_mld(x$depth_m, x$sigma_theta_ave, criterion = "sigma_theta",
                  threshold = p$mld_sigma[1], ref_depth = p$mld_ref_m) |>
            transmute(measurement_type = "mld_sigma_theta_003", value = mld_m),
          ctd_mld(x$depth_m, x$sigma_theta_ave, criterion = "sigma_theta",
                  threshold = p$mld_sigma[2], ref_depth = p$mld_ref_m) |>
            transmute(measurement_type = "mld_sigma_theta_0125", value = mld_m)))
        if (any(!is.na(x$est_chlorophyll_a_sta_corr))) {
          cm <- ctd_chl_max(x$depth_m, x$est_chlorophyll_a_sta_corr,
                            x$q_est_chlorophyll_a_sta_corr, window_m = p$chl_window)
          ci <- ctd_integrate(x$depth_m, x$est_chlorophyll_a_sta_corr,
                              x$q_est_chlorophyll_a_sta_corr,
                              z_max = p$chl_z_max, z_top_max = p$chl_top_max)
          out <- c(out, list(tibble(
            measurement_type = c("chl_max_depth", "chl_max", "chl_integrated", "chl_integrated_depth"),
            value = c(cm$chl_max_depth_m, cm$chl_max_value, ci$integrated, ci$depth_reached_m))))
        }
      }
      bind_rows(out)
    }) |>
    ungroup() |>
    filter(!is.na(value))
  if (nrow(pc)) dbWriteTable(con, "cast_products", as.data.frame(pc), append = TRUE)

  # per station pair (full tier, on-grid stations) ----
  gcst <- cst |>
    filter(data_stage %in% tier_full,
           grepl("^\\d{3}\\.\\d \\d{3}\\.\\d$", site_key)) |>
    mutate(line = as.numeric(substr(site_key, 1, 5)), station = as.numeric(substr(site_key, 7, 11))) |>
    group_by(site_key) |> slice_min(datetime, n = 1, with_ties = FALSE) |> ungroup()
  for (ln in unique(gcst$line[duplicated(gcst$line)])) {
    lc <- filter(gcst, line == ln)
    gd <- d |>
      inner_join(select(lc, sample_key, station, lat_c = latitude, lon_c = longitude), by = "sample_key") |>
      transmute(station_order = station, station = site_key, latitude = lat_c, longitude = lon_c,
                pressure = pr, temperature = temperature_ave, salinity = salinity_ave_corr,
                q_temperature = q_temperature_ave, q_salinity = q_salinity_ave_corr)
    g <- ctd_geostrophic(gd, p_ref = p$geo_p_ref, min_dx_km = p$geo_min_dx)
    if (!nrow(g)) next
    g <- g |>
      mutate(pressure_min_dbar = floor((pressure - 1) / p$geo_bin) * p$geo_bin) |>
      group_by(station_1, station_2, dist_mid_km, dx_km, shallow, pressure_min_dbar) |>
      summarize(velocity_m_s = mean(velocity_m_s), .groups = "drop") |>
      mutate(cruise_key = ck, line = ln, pressure_max_dbar = pressure_min_dbar + p$geo_bin,
             sample_key_1 = lc$sample_key[match(station_1, lc$site_key)],
             sample_key_2 = lc$sample_key[match(station_2, lc$site_key)],
             data_stage = ifelse(
               lc$data_stage[match(station_1, lc$site_key)] == "final" &
                 lc$data_stage[match(station_2, lc$site_key)] == "final",
               "final", "preliminary_with_bottle"))
    dbWriteTable(con, "geo_raw", as.data.frame(g), append = TRUE)
  }
}
flag_audit <- bind_rows(flag_audit)
cat(glue("computed {length(cruises)} cruises in {format(round(Sys.time() - t0, 1))}"), "\n")
```
## Assert the Flag Rule
A value its provider flags 8/9 never enters a derived value. Where sensor 1's
sigma-theta is flagged and sensor 2's is good, the average must be sensor 2 alone;
where both are flagged there must be no average; where the temperature or salinity
average is flagged there must be no spice.
```{r}
#| label: flag-audit
fa <- summarize(flag_audit, across(-cruise_key, sum))
fa |> datatable(caption = "Flag audit over every bin computed", rownames = FALSE)
stopifnot(
  "sensor 1 flagged, sensor 2 good: the average must be sensor 2" =
    fa$s1_flagged_s2_good == fa$avg_equals_s2,
  "both sigma-theta sensors flagged: no average may exist" = fa$both_flagged_avg_present == 0,
  "a flagged temperature/salinity average must yield no spice" = fa$ts_flagged_spice_present == 0)
```
## Register Measurement Types
Nine types, registered with `register_measurement_types()` (append-only) and then
bounded with `declare_measurement_bounds()`. **No bound is invented or taken from the
data**: each is derived from a bound the registry already declares, or from a
constant the pipeline already enforces, and says which.
```{r}
#| label: register-types
d_mt0 <- read_measurement_type(meas_type_csv)
src_mt <- function(tp) filter(d_mt0, measurement_type == tp)
st1 <- src_mt("sigma_theta_1"); chl <- src_mt("est_chlorophyll_a_sta_corr")
t_ave <- src_mt("temperature_ave"); s_ave <- src_mt("salinity_ave_corr")
stopifnot(nrow(st1) == 1, nrow(chl) == 1, nrow(t_ave) == 1, nrow(s_ave) == 1)
p06 <- function(tp) src_mt(tp)$units_nerc_p06

new_types <- tribble(
  ~measurement_type,      ~description, ~units, ~grain, ~category, ~units_nerc_p06, ~`_source_column`, ~derivation,
  "spiciness0", "Spice (spiciness at 0 dbar, TEOS-10); positive spicy (warm, salty), negative minty", "kg/m3", "obs",
    "Physical Oceanography", p06("sigma_theta_1"), "temperature_ave; salinity_ave_corr; pressure",
    "calcofi4db::ctd_spice(): gsw_SA_from_SP, gsw_CT_from_t, gsw_spiciness0 (McDougall & Krzysik 2015) on the sensor-pair averaged corrected temperature and salinity; final and preliminary_with_bottle casts only",
  "sigma_theta_ave", "Potential density anomaly (sigma-theta), sensor-pair average by the provider's flags", "kg/m3", "obs",
    "Physical Oceanography", p06("sigma_theta_1"), "sigma_theta_1; sigma_theta_2",
    "calcofi4db::ctd_sigma_theta_ave() = combine_sensor_pair() on sigma_theta_1/2: an 8/9-flagged sensor dropped, 1/2 select a sensor, else the mean; final and preliminary_with_bottle casts only",
  "mld_sigma_theta_003", "Mixed-layer depth, sigma-theta increase of 0.03 kg/m3 from 10 m (de Boyer Montegut et al. 2004)", "m", "sample",
    "Physical Oceanography", p06("bottom_depth"), "sigma_theta_ave",
    "calcofi4db::ctd_mld(criterion = 'sigma_theta', threshold = 0.03, ref_depth = 10) on the 1 m bins; absent where the cast never crosses or does not reach 10 m (questions Q01)",
  "mld_sigma_theta_0125", "Mixed-layer depth, sigma-theta increase of 0.125 kg/m3 from 10 m (Levitus 1982)", "m", "sample",
    "Physical Oceanography", p06("bottom_depth"), "sigma_theta_ave",
    "calcofi4db::ctd_mld(criterion = 'sigma_theta', threshold = 0.125, ref_depth = 10) on the 1 m bins (questions Q01)",
  "mld_temperature_02", "Mixed-layer depth, temperature departure of 0.2 degC from 10 m (de Boyer Montegut et al. 2004)", "m", "sample",
    "Physical Oceanography", p06("bottom_depth"), "temperature_ave",
    "calcofi4db::ctd_mld(criterion = 'temperature', threshold = 0.2, ref_depth = 10) on the 1 m bins; the only MLD on preliminary_without_bottle casts (questions Q01)",
  "chl_max_depth", "Depth of the chlorophyll-a maximum (5 m running median)", "m", "sample",
    "Productivity & Pigments", p06("bottom_depth"), "est_chlorophyll_a_sta_corr",
    "calcofi4db::ctd_chl_max(window_m = 5) on est_chlorophyll_a_sta_corr (questions Q02)",
  "chl_max", "Chlorophyll-a at its maximum (5 m running median)", chl$units, "sample",
    "Productivity & Pigments", chl$units_nerc_p06, "est_chlorophyll_a_sta_corr",
    "calcofi4db::ctd_chl_max(window_m = 5): the smoothed value at chl_max_depth (questions Q02)",
  "chl_integrated", "Chlorophyll-a integrated from the surface to 200 m (or the cast bottom)", "mg/m2", "sample",
    "Productivity & Pigments", NA_character_, "est_chlorophyll_a_sta_corr",
    "calcofi4db::ctd_integrate(z_max = 200, z_top_max = 5): trapezoid of est_chlorophyll_a_sta_corr (ug/L = mg/m3) over depth; chl_integrated_depth says how deep it reached (questions Q02)",
  "chl_integrated_depth", "Depth reached by chl_integrated (200 m unless the cast is shallower)", "m", "sample",
    "Productivity & Pigments", p06("bottom_depth"), "est_chlorophyll_a_sta_corr",
    "calcofi4db::ctd_integrate(): min(200, deepest good bin) (questions Q02)") |>
  mutate(is_canonical = TRUE, `_source_table` = "obs_ctd_full", `_source_datasets` = src_key,
         `_qual_column` = NA_character_, `_prec_column` = NA_character_)
d_meas_type <- register_measurement_types(new_types, meas_type_csv)

# spiciness0 over the registered temperature x salinity bounds at 0 dbar, rounded
# outward: what the registry already calls physically possible (questions Q07)
tsg <- expand.grid(t = seq(t_ave$valid_min, t_ave$valid_max, 1),
                   s = seq(s_ave$valid_min, s_ave$valid_max, 1))
sa_g <- gsw::gsw_SA_from_SP(tsg$s, rep(0, nrow(tsg)), -120, 33)
sp_g <- gsw::gsw_spiciness0(sa_g, gsw::gsw_CT_from_t(sa_g, tsg$t, rep(0, nrow(tsg))))

bounds <- tribble(
  ~measurement_type,       ~valid_min,                   ~valid_max,                              ~why,
  "spiciness0",            floor(min(sp_g)),             ceiling(max(sp_g)),                      "gsw_spiciness0 over the registered temperature_ave x salinity_ave_corr bounds (Q07)",
  "sigma_theta_ave",       st1$valid_min,                st1$valid_max,                           "the bounds sigma_theta_1/2 declare",
  "mld_sigma_theta_003",   0,                            CC_DEPTH_MAX_M,                          "a depth: 0 to the pipeline's CC_DEPTH_MAX_M",
  "mld_sigma_theta_0125",  0,                            CC_DEPTH_MAX_M,                          "a depth: 0 to CC_DEPTH_MAX_M",
  "mld_temperature_02",    0,                            CC_DEPTH_MAX_M,                          "a depth: 0 to CC_DEPTH_MAX_M",
  "chl_max_depth",         chl$valid_depth_min_m,        chl$valid_depth_max_m,                   "est_chlorophyll_a_sta_corr is defined over this depth window only",
  "chl_max",               chl$valid_min,                chl$valid_max,                           "the bounds est_chlorophyll_a_sta_corr declares",
  "chl_integrated",        0,                            chl$valid_max * p$chl_z_max,             "the chl ceiling times the 200 m integration depth",
  "chl_integrated_depth",  0,                            p$chl_z_max,                             "the integration floor")
d_meas_type <- declare_measurement_bounds(select(bounds, -why), meas_type_csv)
bounds |> datatable(caption = "Declared bounds and where each comes from", rownames = FALSE)
dbWriteTable(con, "measurement_type", as.data.frame(d_meas_type), overwrite = TRUE)
```
## Load Dataset Metadata
```{r}
#| label: load-dataset-metadata
this_provider <- provider; this_dataset <- dataset
d_dataset <- ingest_yaml_to_dataset_df(read_ingest_yaml(here())) |>
  filter(provider == this_provider, dataset == this_dataset)
stopifnot(nrow(d_dataset) == 1)
dbWriteTable(con, "dataset", as.data.frame(d_dataset), overwrite = TRUE)
```
## Emit Core Tables
**Per bin → `obs`, at the depths `calcofi_ctd-cast` publishes in `obs`** (its thinned
series: a 10 m grid, the depths where each profile bends, and bottle depths), so a
derived value lines up with the temperature and salinity it came from and the
release `climatology` (10 m bins) covers it with no special case. Position, time,
grid and cruise come from that same ctd-cast row. The full 1 m derived series is
not published (it would repeat `obs_ctd_full`'s grain for two computed columns); it
is recomputable from `obs_ctd_full` with the same functions.
**Per cast → `sample_measurement`** on the ctd-cast cast `sample_key`.
**Per station pair → `ctd_geostrophic`**, its own table: its grain is between
stations, so it has no `sample`, no `obs` row and no anomaly.
This dataset emits **no `sample`**: the cast is `calcofi_ctd-cast`'s, and a second
row with the same key would break the global uniqueness `assemble_core()` asserts.
The cross-dataset keys are declared in `metadata/relationships_cross.csv`.
```{r}
#| label: emit-core
# ctd-cast's thinned series repeats ~10,200 (cast, depth) pairs as two scans at
# different times; one derived value per (cast, depth), on the earlier scan's row
dbExecute(con, "
  CREATE OR REPLACE TEMP TABLE thin_depth AS
  SELECT sample_key, grid_key, cruise_key, latitude, longitude, datetime, depth_min_m, depth_max_m
  FROM src_obs WHERE measurement_type = 'temperature_ave'
  QUALIFY ROW_NUMBER() OVER (PARTITION BY sample_key, depth_min_m ORDER BY datetime, latitude) = 1")
for (tp in c("sigma_theta_ave", "spiciness0"))
  append_obs(con, glue("
    SELECT 'env', '{ds_key}', o.sample_key, o.grid_key, o.cruise_key,
           o.latitude, o.longitude, o.datetime, o.depth_min_m, o.depth_max_m,
           NULL::VARCHAR, NULL::VARCHAR, '{tp}', b.{tp}, NULL::VARCHAR, NULL::DOUBLE
    FROM thin_depth o
    JOIN bin_full b ON b.sample_key = o.sample_key AND b.depth_m = o.depth_min_m
    WHERE b.{tp} IS NOT NULL"))

append_sample_measurement(con, glue("
  SELECT sample_key, '{ds_key}', measurement_type, value, NULL::VARCHAR
  FROM cast_products"))

dbExecute(con, "
  CREATE OR REPLACE TABLE ctd_geostrophic AS
  SELECT cruise_key, line, station_1 AS site_key_1, station_2 AS site_key_2,
         sample_key_1, sample_key_2, dist_mid_km, dx_km,
         pressure_min_dbar, pressure_max_dbar, velocity_m_s, shallow, data_stage
  FROM geo_raw
  ORDER BY cruise_key, line, dist_mid_km, pressure_min_dbar")
n <- list(
  obs = dbGetQuery(con, "SELECT COUNT(*) AS n FROM obs")$n,
  sample_measurement = dbGetQuery(con, "SELECT COUNT(*) AS n FROM sample_measurement")$n,
  ctd_geostrophic = dbGetQuery(con, "SELECT COUNT(*) AS n FROM ctd_geostrophic")$n)
cat(glue("core projection: obs {n$obs}, sample_measurement {n$sample_measurement}, ",
         "ctd_geostrophic {n$ctd_geostrophic}"), "\n")
# how many of ctd-cast's published depths found a full-resolution bin to carry
dbGetQuery(con, "
  SELECT c.data_stage, COUNT(*) AS thinned_depths,
         COUNT(b.sample_key) AS with_derived_bin,
         ROUND(100.0 * COUNT(b.sample_key) / COUNT(*), 2) AS pct
  FROM src_obs o JOIN casts c USING (sample_key)
  LEFT JOIN bin_full b ON b.sample_key = o.sample_key AND b.depth_m = o.depth_min_m
  WHERE o.measurement_type = 'temperature_ave'
  GROUP BY 1 ORDER BY 1") |>
  datatable(caption = "ctd-cast's published (thinned) depths that carry a derived bin, by tier", rownames = FALSE)
```
## Coverage by Tier
```{r}
#| label: coverage
d_cov <- dbGetQuery(con, "
  WITH per AS (
    SELECT sample_key, measurement_type FROM sample_measurement
    UNION ALL SELECT DISTINCT sample_key, measurement_type FROM obs)
  SELECT c.data_stage, p.measurement_type, COUNT(DISTINCT p.sample_key) AS casts
  FROM per p JOIN casts c USING (sample_key) GROUP BY ALL") |>
  pivot_wider(names_from = data_stage, values_from = casts, values_fill = 0) |>
  cross_join(count(d_casts, data_stage) |> pivot_wider(names_from = data_stage, values_from = n,
                                                      names_prefix = "of_")) |>
  arrange(measurement_type)
d_cov |> datatable(caption = "Casts carrying each product, by data_stage (of_* = casts in the tier)", rownames = FALSE)
# the tier rule, asserted: a preliminary_without_bottle cast carries ONLY the
# temperature-criterion MLD
n_bad_tier <- dbGetQuery(con, "
  SELECT COUNT(*) AS n FROM (
    SELECT sample_key, measurement_type FROM sample_measurement
    UNION ALL SELECT sample_key, measurement_type FROM obs) p
  JOIN casts c USING (sample_key)
  WHERE c.data_stage = 'preliminary_without_bottle' AND p.measurement_type <> 'mld_temperature_02'")$n
n_bad_geo <- dbGetQuery(con, "
  SELECT COUNT(*) AS n FROM ctd_geostrophic g
  JOIN casts c ON c.sample_key IN (g.sample_key_1, g.sample_key_2)
  WHERE c.data_stage = 'preliminary_without_bottle'")$n
stopifnot(
  "a preliminary_without_bottle cast may carry only mld_temperature_02" = n_bad_tier == 0,
  "no geostrophic pair may use a preliminary_without_bottle cast" = n_bad_geo == 0)
```
## Check Measurement Bounds
```{r}
#| label: bounds
b_obs <- check_measurement_bounds(con, "obs", mt = d_meas_type, dataset_key = ds_key)
b_sm  <- check_measurement_bounds(con, "sample_measurement", mt = d_meas_type, dataset_key = ds_key)
bounds_datatable(bind_rows(b_obs, b_sm))
stopifnot(
  "every derived type is bounded" = all(c(b_obs$status, b_sm$status) != "undeclared"),
  "no derived value breaks its bound" = all(c(b_obs$status, b_sm$status) != "out_of_range"))

d_geo_rng <- dbGetQuery(con, "
  SELECT shallow, COUNT(*) AS bins, COUNT(DISTINCT (cruise_key, sample_key_1, sample_key_2)) AS pairs,
         MIN(velocity_m_s) AS v_min, MAX(velocity_m_s) AS v_max,
         SUM(CASE WHEN NOT isfinite(velocity_m_s) THEN 1 ELSE 0 END) AS n_nonfinite,
         MIN(dx_km) AS dx_min_km
  FROM ctd_geostrophic GROUP BY shallow ORDER BY shallow")
d_geo_rng |> datatable(caption = "ctd_geostrophic: velocity range by shallow flag (m/s)", rownames = FALSE)
stopifnot(
  "geostrophic velocity must be finite" = sum(d_geo_rng$n_nonfinite) == 0,
  "no pair closer than min_dx_km" = min(d_geo_rng$dx_min_km) >= p$geo_min_dx)
```
## Findings for the Provider
Values inside the generous bounds that no ocean water can have are **not deleted**:
a bound catches the impossible, and these are unflagged in the source, so they are
the CTD team's to flag in the ledger (`flag_accepted.parquet`), after which the next
render drops them. Spice below −3 kg m⁻³ means a practical salinity near 20, which is
a salinity fault the flags missed (the same class as the corrected sensor reading
19 PSU the measurement-bounds skill records); a geostrophic velocity above
0.5 m s⁻¹ between two casts that both reach 500 dbar is almost always one bad
profile. Both are question Q08.
```{r}
#| label: findings
d_spice_odd <- dbGetQuery(con, "
  SELECT o.cruise_key, c.site_key, o.sample_key, COUNT(*) AS n_bins,
         ROUND(MIN(o.measurement_value), 2) AS spice_min,
         MIN(o.depth_min_m) AS depth_min_m, MAX(o.depth_min_m) AS depth_max_m
  FROM obs o JOIN casts c USING (sample_key)
  WHERE o.measurement_type = 'spiciness0' AND o.measurement_value < -3
  GROUP BY ALL ORDER BY n_bins DESC")
d_spice_odd |> datatable(caption = glue(
  "Spice below -3 kg/m3: {sum(d_spice_odd$n_bins)} bins on {nrow(d_spice_odd)} casts (question Q08)"),
  rownames = FALSE)
d_geo_odd <- dbGetQuery(con, "
  SELECT cruise_key, line, site_key_1, site_key_2, ROUND(MAX(ABS(velocity_m_s)), 2) AS v_abs_max
  FROM ctd_geostrophic WHERE NOT shallow AND ABS(velocity_m_s) > 0.5
  GROUP BY ALL ORDER BY v_abs_max DESC")
d_geo_odd |> datatable(caption = glue(
  "Geostrophic |v| above 0.5 m/s on pairs reaching 500 dbar: {nrow(d_geo_odd)} pairs (question Q08)"),
  rownames = FALSE)
```
## Relationships
```{r}
#| label: relationships
dbExecute(con, "DROP VIEW IF EXISTS src_obs"); dbExecute(con, "DROP VIEW IF EXISTS src_sample")
cast_keys <- dbGetQuery(con, "SELECT sample_key FROM casts")$sample_key
stopifnot(
  "every obs.sample_key is a calcofi_ctd-cast cast" =
    dbGetQuery(con, "SELECT COUNT(*) AS n FROM obs WHERE sample_key NOT IN (SELECT sample_key FROM casts)")$n == 0,
  "every sample_measurement.sample_key is a calcofi_ctd-cast cast" =
    dbGetQuery(con, "SELECT COUNT(*) AS n FROM sample_measurement WHERE sample_key NOT IN (SELECT sample_key FROM casts)")$n == 0,
  "every geostrophic cast is a calcofi_ctd-cast cast" =
    dbGetQuery(con, "SELECT COUNT(*) AS n FROM ctd_geostrophic
                     WHERE sample_key_1 NOT IN (SELECT sample_key FROM casts)
                        OR sample_key_2 NOT IN (SELECT sample_key FROM casts)")$n == 0,
  "every measurement_type is registered" =
    dbGetQuery(con, "SELECT COUNT(*) AS n FROM (SELECT measurement_type FROM obs UNION
                     SELECT measurement_type FROM sample_measurement)
                     WHERE measurement_type NOT IN (SELECT measurement_type FROM measurement_type)")$n == 0,
  "ctd_geostrophic key is unique" =
    dbGetQuery(con, "SELECT COUNT(*) AS n FROM (SELECT cruise_key, sample_key_1, sample_key_2, pressure_min_dbar
                     FROM ctd_geostrophic GROUP BY ALL HAVING COUNT(*) > 1)")$n == 0,
  "one obs row per cast, depth and type" =
    dbGetQuery(con, "SELECT COUNT(*) AS n FROM (SELECT sample_key, depth_min_m, measurement_type FROM obs
                     GROUP BY ALL HAVING COUNT(*) > 1)")$n == 0,
  "one sample_measurement row per cast and type" =
    dbGetQuery(con, "SELECT COUNT(*) AS n FROM (SELECT sample_key, measurement_type FROM sample_measurement
                     GROUP BY ALL HAVING COUNT(*) > 1)")$n == 0)

tbls_out <- core_output_tables(con, extra = c("ctd_geostrophic", "measurement_type", "dataset"))
rels <- core_relationships(tbls_out)
rels$primary_keys$ctd_geostrophic <- c("cruise_key", "sample_key_1", "sample_key_2", "pressure_min_dbar")
cc_erd(con, tables = c("obs", "sample_measurement", "ctd_geostrophic", "measurement_type"),
       rels = rels,
       colors = list(lightblue = c("obs", "sample_measurement", "ctd_geostrophic"),
                     lightyellow = "measurement_type"))
```
| source (calcofi_ctd-cast `obs_ctd_full`) | core | transform |
|---|---|---|
| `temperature_ave`, `salinity_ave_corr`, `pressure` (1 m) | `obs.measurement_type = spiciness0` | `ctd_spice()`; emitted at ctd-cast's thinned depths |
| `sigma_theta_1`, `sigma_theta_2` + flags (1 m) | `obs.measurement_type = sigma_theta_ave` | `ctd_sigma_theta_ave()`; thinned depths |
| `sigma_theta_ave` (1 m) | `sample_measurement`: `mld_sigma_theta_003`, `mld_sigma_theta_0125` | `ctd_mld()` |
| `temperature_ave` (1 m) | `sample_measurement`: `mld_temperature_02` | `ctd_mld(criterion = "temperature")` |
| `est_chlorophyll_a_sta_corr` (1 m) | `sample_measurement`: `chl_max_depth`, `chl_max`, `chl_integrated`, `chl_integrated_depth` | `ctd_chl_max()`, `ctd_integrate()` |
| `temperature_ave`, `salinity_ave_corr`, `pressure` per station | `ctd_geostrophic` | `ctd_geostrophic()`, 10 dbar bin means |
| **not published** | the full 1 m derived per-bin series; the up cast where a down cast exists; per-cast statuses (`mixed_to_bottom`, `no_reference`) — an absent row | |
: Source → core mapping {#tbl-mapping}
## Data Preview
```{r}
#| label: preview-obs
dbGetQuery(con, "SELECT * FROM obs ORDER BY sample_key, depth_min_m, measurement_type LIMIT 200") |>
  datatable(caption = "obs — first 200 rows", rownames = FALSE, filter = "top")
```
```{r}
#| label: preview-sample-measurement
dbGetQuery(con, "
  SELECT c.cruise_key, c.site_key, c.data_stage, m.*
  FROM sample_measurement m JOIN casts c USING (sample_key)
  ORDER BY c.cruise_key DESC, c.site_key, m.measurement_type LIMIT 300") |>
  datatable(caption = "sample_measurement — the most recent casts", rownames = FALSE, filter = "top")
```
```{r}
#| label: preview-summary
dbGetQuery(con, "
  SELECT measurement_type, COUNT(*) AS casts,
         ROUND(MEDIAN(measurement_value), 2) AS median,
         ROUND(MIN(measurement_value), 2) AS min, ROUND(MAX(measurement_value), 2) AS max
  FROM sample_measurement GROUP BY 1 ORDER BY 1") |>
  datatable(caption = "Per-cast products over every cruise", rownames = FALSE)
```
```{r}
#| label: preview-geostrophic
dbGetQuery(con, "SELECT * FROM ctd_geostrophic ORDER BY cruise_key DESC, line, dist_mid_km, pressure_min_dbar LIMIT 300") |>
  datatable(caption = "ctd_geostrophic — the most recent cruise", rownames = FALSE, filter = "top")
```
## Validate
`validate_for_release()` treats every `_key` column as required. The NULLs below are
declared with their reason and count; anything undeclared, or a count that moved,
fails the render.
```{r}
#| label: validate
# the expected NULL counts, derived independently of the table being checked
n_obs_rows  <- dbGetQuery(con, "SELECT COUNT(*) AS n FROM obs")$n
# the wrangling tables are not outputs; drop them so the validator sees what ships
for (tb in c("bin_full", "cast_products", "geo_raw", "casts"))
  dbExecute(con, glue("DROP TABLE IF EXISTS {tb}"))
results <- validate_for_release(con, checks = "all", strict = FALSE)
nullable <- tribble(
  ~table, ~column, ~n, ~reason,
  "obs", "taxon_key", n_obs_rows, "env realm: a derived physical quantity names no organism")
found <- tibble(msg = results$errors) |>
  mutate(table  = sub("^Table '([^']+)'.*$", "\\1", msg),
         column = sub("^.*required column '([^']+)'.*$", "\\1", msg),
         n      = suppressWarnings(as.integer(sub("^Table '[^']+' has (\\d+) NULL.*$", "\\1", msg))))
unexplained <- anti_join(found, nullable, by = c("table", "column"))
moved <- inner_join(found, nullable, by = c("table", "column"), suffix = c("", "_decl")) |>
  filter(!is.na(n_decl), n != n_decl)
nullable |> left_join(select(found, table, column, n_found = n), by = c("table", "column")) |>
  datatable(caption = "Declared NULLs vs what validate_for_release() found", rownames = FALSE)
if (nrow(unexplained)) print(unexplained$msg)
stopifnot(
  "a NULL appeared with no declared reason" = nrow(unexplained) == 0,
  "a declared NULL count has changed"       = nrow(moved) == 0)
```
## Enforce Column Types
```{r}
#| label: enforce-types
d_tbls_rd <- read_csv(glue("{dir_meta}/tbls_redefine.csv"))
d_flds_rd <- read_csv(glue("{dir_meta}/flds_redefine.csv"))
enforce_column_types(con, d_flds_rd = d_flds_rd, tables = "ctd_geostrophic")
```
## Write Parquet Outputs
```{r}
#| label: write-parquet
dir_create(dir_parquet)
tbls_out <- core_output_tables(con, extra = c("ctd_geostrophic", "measurement_type", "dataset"))
parquet_stats <- write_parquet_outputs(
  con = con, output_dir = dir_parquet, tables = tbls_out,
  sort_by = list(obs = c("grid_key", "measurement_type", "depth_min_m"),
                 ctd_geostrophic = c("cruise_key", "line", "dist_mid_km", "pressure_min_dbar")),
  strip_provenance = FALSE)
build_relationships_json(rels = rels, output_dir = dir_parquet, provider = provider, dataset = dataset)
parquet_stats |> mutate(file = basename(path)) |> select(-path) |>
  datatable(caption = "Parquet export statistics")
```
## Write Metadata
```{r}
#| label: write-metadata
metadata_path <- build_metadata_json(
  con = con, d_tbls_rd = d_tbls_rd, d_flds_rd = d_flds_rd,
  metadata_derived_csv = c(here("metadata/core_dictionary.csv"),
                           glue("{dir_meta}/metadata_derived.csv")),
  output_dir = dir_parquet, tables = tbls_out,
  set_comments = TRUE, provider = provider, dataset = dataset,
  workflow_url = cc$workflow_url, tables_owned = tables_owned)
```
## Upload to GCS
```{r}
#| label: upload-gcs
if (Sys.getenv("CALCOFI_SKIP_GCS") == "") {
  sync_to_gcs(local_dir = dir_stage, sidecar_dir = dir_parquet,
              gcs_prefix = glue("ingest/{dir_label}"), bucket = "calcofi-db")
} else cat("CALCOFI_SKIP_GCS set — skipping the upload (local verification run)\n")
```
## Questions for Data Providers
The five choices awaiting Rasmus Swalethorp (Q01–Q05), each carrying the default
this build uses as its proposed answer, plus the inherited licence/PI gap (Q06), the
derived spice bound (Q07) and the implausible values for the CTD team to flag (Q08).
```{r}
#| label: provider-questions
questions_datatable(
  here(cc$questions_file),
  caption = "Questions for the CTD derived products (ranked)")
```
## Cleanup
```{r}
#| label: cleanup
close_duckdb(con)
cat(glue("input used: {input_used}"), "\n")
cat(glue("Parquet outputs written to: {dir_stage}; sidecars in {dir_parquet}"), "\n")
```