graph LR
  A[occurrence.txt + dnaderiveddata.txt + extendedmeasurementorfact.txt] --> B[DuckDB Wrangling]
  B --> C[Validate & Clean]
  C --> D[Parquet Export]
  D --> E[GCS Archive]
  E --> F[Release Database]
Ingest CalCOFI October 2022 Vertebrate eDNA
Overview
Source: GBIF/OBIS Darwin Core Archive, DOI 10.15468/n52j6r (“CalCOFI October 2022 Vertebrate eDNA”). Linked to Patin et al. 2026 (Methods in Ecology and Evolution, https://doi.org/10.1111/2041-210x.70370). Water filters collected 2022-10-13 to 2022-10-18 at CalCOFI/GEMCAP stations on the Reuben Lasker, each run through one or both of two molecular assays: mitochondrial D-loop (cetaceans – Delphinus, Megaptera novaeangliae) and 12S rRNA “MiFish” (fish). Source datasetID is CalCOFI_Intercal – an intercalibration exercise, published as a CalCOFI program product (provider calcofi, not sio: see provider.csv – this dataset is branded and identified as CalCOFI’s own, unlike e.g. sio_mesopelagic-fish, which is an SIO lab collection CalCOFI merely sampled for).
What a read count is, and is not. organismQuantity is a number of DNA sequence reads – PCR-amplified, primer- and library-depth-dependent. It is a semi-quantitative signal, not abundance, and reads from the two assays are not comparable. So the headline obs row is edna_presence (1 = detected; the same type sio_cetacean-edna uses), and the reads are published per assay (edna_reads_dloop, edna_reads_12s) beside the per-assay filtered-read totals in sample_measurement (edna_reads_filtered_*), which turn them into a relative read abundance within an assay. The archive carries positive detections only: a filter, or an assay run, with no detection is absent, so a 0 is never emitted and absence cannot be inferred (provider question).
Not a wide CSV. This ingest reads the DwC-A’s three tables directly (occurrence.txt, dnaderiveddata.txt, extendedmeasurementorfact.txt, tab-delimited) instead of read_csv_files(), the same way ingest_calcofi_ctd-cast.qmd bypasses it for its own non-CSV source. The source zip (dwca-calcofi_*.zip, GBIF’s DwC-A download) lives at dir_data/{provider}/{dataset}/ – data-public/calcofi/2022-edna/ – the same convention as every other dataset’s folder (bottle/, ctd-cast/, dic/, mets/), not a special genomics/ location. A second zip in that folder (GBIF’s raw occurrence-download export) is not used here – the DwC-A is the complete, canonical source; the other is a redundant representation kept for reference.
Sample grain is parentEventID (sample_type filter), not eventID. Every eventID under a given parentEventID shares identical decimalLatitude/decimalLongitude/minimumDepthInMeters/eventDate (asserted below) – an eventID is one sequencing library: an assay (_DL D-loop, _MiFish 12S) and, for D-loop, a PCR replicate (-1, -2, -3). Treating eventID as the sample would duplicate every filter’s coordinates once per library. An occurrenceID is one ASV (a distinct sequence) in one library, so the same taxon appears many times per filter (dozens of D. delphis ASVs in one library); obs sums them to one row per filter x taxon x assay.
Data Flow
Setup
devtools::load_all(here::here("../calcofi4db"))
devtools::load_all(here::here("../calcofi4r"))
librarian::shelf(
  CalCOFI/calcofi4db, CalCOFI/calcofi4r,
  DBI, dplyr, DT, fs, glue, here, janitor, jsonlite, knitr, lubridate, purrr,
  readr, sf, stringr, tibble, tidyr, units, quiet = T)
options(readr.show_col_types = F)
options(DT.options = list(scrollX = TRUE))

source(here("libs/ingest.R"))

cc           <- read_calcofi_meta(here("ingest_calcofi_2022-edna.qmd"))
provider     <- cc$provider    # "calcofi"
dataset      <- cc$dataset     # "2022-edna"
ds_key       <- as.character(glue("{provider}_{dataset}"))
tables_owned <- cc$tables_owned
dir_label    <- ds_key
dir_parquet  <- here(glue("data/parquet/{dir_label}"))
dir_stage    <- cc_stage_path("parquet", dir_label, create = TRUE)
dir_ext      <- cc_stage_path("2022-edna", "unzip", create = TRUE)
dir_meta     <- here(glue("metadata/{provider}/{dataset}"))
db_path      <- here(glue("data/wrangling/{dir_label}.duckdb"))

if (overwrite) {
  if (file_exists(db_path))                 file_delete(db_path)
  if (file_exists(paste0(db_path, ".wal"))) file_delete(paste0(db_path, ".wal"))
  if (dir_exists(paste0(db_path, ".tmp")))  dir_delete(paste0(db_path, ".tmp"))
}
dir_create(dirname(db_path))
con <- get_duckdb_con(db_path)
load_duckdb_extension(con, "spatial")

meas_type_csv <- here("metadata/measurement_type.csv")
d_meas_type   <- read_measurement_type(meas_type_csv)

# required by build_metadata_json() even when read_csv_files() is bypassed for
# the main data read -- same requirement confirmed in ingest_calcofi_ctd-cast.qmd
d_flds_rd <- read_csv(glue("{dir_meta}/flds_redefine.csv"), show_col_types = FALSE)
d_tbls_rd <- read_csv(glue("{dir_meta}/tbls_redefine.csv"), show_col_types = FALSE)
Read Source Data
Reads the three DwC-A tables directly as tab-delimited text – read_csv_files() assumes one wide CSV per dataset, which this source does not fit (Occurrence core + 2 extensions). Source is a zip (GBIF’s DwC-A download); the raw zip is archived to GCS as received (sync_to_gcs(), the same non-CSV-source pattern ingest_calcofi_ctd-cast.qmd uses), and unzipped into the wrangling scratch dir for reading – the extracted .txt files never go to GCS themselves.
dir_source <- path(dir_data, provider, dataset)
dwca_zips  <- dir_ls(dir_source, glob = "*dwca*.zip")
stopifnot("expected exactly one dwca-*.zip in the dataset folder" = length(dwca_zips) == 1)
dwca_zip <- dwca_zips[[1]]
cat(glue("using source zip: {path_file(dwca_zip)}"), "\n")
using source zip: dwca-calcofi_october2022_edna-v1.2.zip sync_to_gcs(
local_dir = dir_source,
gcs_prefix = glue("archive/{provider}/{dataset}"),
bucket = "calcofi-files-public",
exclude = c(".DS_Store"))rsync ~/My Drive/projects/calcofi/data-public/calcofi/2022-edna -> gs://calcofi-files-public/archive/calcofi/2022-ednaSync complete: 0 copied, 0 removed (rsync)# A tibble: 0 × 4
# ℹ 4 variables: file <chr>, action <chr>, size <dbl>, reason <chr>dir_dwca <- path(dir_ext, "dwca")
dir_create(dir_dwca)
unzip(dwca_zip, exdir = dir_dwca, overwrite = TRUE)
read_dwca_txt <- function(name) {
read_tsv(path(dir_dwca, name), col_types = cols(.default = "c"),
na = character())
}
d_occ <- read_dwca_txt("occurrence.txt")
d_dna <- read_dwca_txt("dnaderiveddata.txt")
d_emof <- read_dwca_txt("extendedmeasurementorfact.txt")
cat(glue(
"read {nrow(d_occ)} occurrence rows, {nrow(d_dna)} dnaderiveddata rows, ",
"{nrow(d_emof)} extendedmeasurementorfact rows"), "\n")read 201 occurrence rows, 201 dnaderiveddata rows, 12631 extendedmeasurementorfact rows Check Data Integrity
No read_csv_files() result to hand check_data_integrity(), so integrity is checked directly against the shape this ingest actually depends on: every occurrenceID unique, every occurrence joins 1:1 to dnaderiveddata (the assay source), every parentEventID group internally agrees on position/time/depth (the sample-grain decision above), every read count is a positive integer of one quantity type, and no occurrenceStatus other than present (no absence records to filter).
n_dup_occid <- d_occ |> count(occurrenceID) |> filter(n > 1) |> nrow()
stopifnot("occurrenceID must be unique in occurrence.txt" = n_dup_occid == 0)

n_unjoined <- d_occ |> anti_join(d_dna, by = "occurrenceID") |> nrow()
stopifnot("every occurrence must join to dnaderiveddata by occurrenceID" = n_unjoined == 0)

occ_status <- unique(d_occ$occurrenceStatus)
stopifnot("only 'present' occurrenceStatus expected -- an 'absent' record needs its own handling" =
            setequal(occ_status, "present"))

grain_check <- d_occ |>
  distinct(parentEventID, decimalLatitude, decimalLongitude,
           minimumDepthInMeters, maximumDepthInMeters, eventDate) |>
  count(parentEventID) |>
  filter(n > 1)
stopifnot("every parentEventID must share one position/depth/date across its eventIDs" =
            nrow(grain_check) == 0)

stopifnot("dnaderiveddata must hold one row per occurrenceID" =
            !anyDuplicated(d_dna$occurrenceID))

# every organismQuantity is a positive whole number of sequence reads -- the
# aggregation below SUMs them, so a non-numeric or a different quantity type
# would be silently mixed in
stopifnot(
  "organismQuantityType must be 'DNA sequence reads' on every occurrence" =
    setequal(unique(d_occ$organismQuantityType), "DNA sequence reads"),
  "organismQuantity must be a positive integer on every occurrence" =
    all(grepl("^[0-9]+$", d_occ$organismQuantity)) &&
    all(as.numeric(d_occ$organismQuantity) > 0))

n_parent <- n_distinct(d_occ$parentEventID)
cat(glue(
  "integrity OK: {nrow(d_occ)} occurrences (ASV x library) / {n_parent} parentEventID ",
  "filters / {n_distinct(d_occ$eventID)} eventIDs (sequencing libraries: assay x PCR ",
  "replicate); 0 duplicate occurrenceIDs; 0 unjoined to dnaderiveddata; 0 grain conflicts"), "\n")
integrity OK: 201 occurrences (ASV x library) / 47 parentEventID filters / 76 eventIDs (sequencing libraries: assay x PCR replicate); 0 duplicate occurrenceIDs; 0 unjoined to dnaderiveddata; 0 grain conflicts Build Sample (Filter) Table
d_sample <- d_occ |>
  distinct(parentEventID, decimalLatitude, decimalLongitude,
           minimumDepthInMeters, maximumDepthInMeters, eventDate,
           locationID, locality) |>
  transmute(
    parent_event_id = parentEventID,
    latitude   = as.numeric(decimalLatitude),
    longitude  = as.numeric(decimalLongitude),
    depth_min_m = as.numeric(minimumDepthInMeters),
    depth_max_m = as.numeric(maximumDepthInMeters),
    datetime_start_utc = readr::parse_datetime(eventDate, format = "%Y-%m-%dT%H:%M%z"),
    location_id = locationID,
    locality = locality,
    # Q01: every filter is from the Reuben Lasker (ship_key 'RL', NODC 33UD).
    # Set here, before add_point_geom(): never UPDATE a table holding a geom.
    ship_key = "RL")

# regression guard (commit 9b1a0d9): as_datetime() once turned every eventDate
# (an offset timestamp without seconds) into NA while the render stayed green,
# leaving datetime and cruise_key NULL for every filter
stopifnot(
  "every eventDate must parse to a UTC datetime" = !anyNA(d_sample$datetime_start_utc),
  "one edna_sample row per parentEventID" =
    nrow(d_sample) == n_parent && !anyDuplicated(d_sample$parent_event_id))

dbWriteTable(con, "edna_sample", as.data.frame(d_sample), overwrite = TRUE)
cat(glue("edna_sample: {nrow(d_sample)} filters"), "\n")
edna_sample: 47 filters Standardize Taxonomy
Every occurrence’s scientificNameID is already a resolved WoRMS AphiaID (urn:lsid:marinespecies.org:taxname:<id>) – there is no name-matching to do, unlike ingest_farallon_bird-mammal.qmd’s ERDDAP-code crosswalk. The declaration step below extracts that id directly rather than looking it up.
mt_taxon <- read_csv(here("metadata/measurement_taxon.csv"),
                     col_types = cols(worms_id = "i", itis_id = "i",
                                      bin_value = "d", .default = "c")) |>
  filter(dataset_key == ds_key)
tx_over  <- read_csv(here("metadata/taxon_override.csv"), show_col_types = FALSE)

dbWriteTable(con, "edna_occurrence", as.data.frame(d_occ), overwrite = TRUE)

d_vocab <- dbGetQuery(con, "
  SELECT DISTINCT scientificNameID                                AS ds_taxa_code,
         scientificName                                            AS ds_scientific_name,
         CAST(regexp_extract(scientificNameID, '([0-9]+)$', 1) AS INTEGER) AS worms_id
  FROM edna_occurrence
  ORDER BY 1")
stopifnot("every occurrence must carry a WoRMS scientificNameID" =
            all(!is.na(d_vocab$worms_id)))

n_staged <- append_dataset_taxon(con, ds_key, d_vocab)

ensure_taxon_xref(con, mt_taxon, tx_over,
                  cache_csv = here("metadata/taxon_xref.csv"))
taxon xref: 0 TSN + 19 AphiaID + 0 name requested; 0 to fetch, 19 cached_taxon_xref: 19 cross-reference rows (19 with worms_id, 19 with itis_id, 0 re-keyed)ensure_taxon_lineage(con, mt_taxon, tx_over,
cache_csv = here("metadata/taxon_lineage.csv"))taxon lineage: 19 WoRMS + 0 ITIS requested; 0 to fetch, 19 cachedtaxon lineage: 0 Aves taxa keyed on ITIS, 19 taxa on WoRMStaxon xref: 0 TSN + 79 AphiaID + 0 name requested; 0 to fetch, 79 cachedtaxon: 79 lineage rows for 19 taxa (0 unresolved)n_taxon <- build_taxon_reference(con, mt_taxon, tx_over)
n_ds_taxon <- resolve_dataset_taxon(con, mt_taxon, tx_over)
obs_codes <- dbGetQuery(con, "SELECT DISTINCT scientificNameID FROM edna_occurrence")[[1]]
chk_taxon <- check_dataset_taxon(con, ds_key, codes = obs_codes, allow = character())check_dataset_taxon('calcofi_2022-edna'): 19 taxa, 19 keyed by an authority, 0 local (0 allowed); 0 finding(s)cat(glue("taxonomy: {n_staged} taxa staged (all WoRMS-resolved), ",
"taxon {n_taxon}, dataset_taxon {n_ds_taxon}"), "\n")taxonomy: 19 taxa staged (all WoRMS-resolved), taxon 79, dataset_taxon 19 Assay and Detection Grain
The molecular assay is a property of the sequencing library (eventID), not of the filter: one filter can carry D-loop and MiFish libraries. It comes from dnaderiveddata.target_gene, joined by occurrenceID, and is checked against the library id’s own _DL / _MiFish suffix. The assay goes into the measurement_type (edna_reads_dloop, edna_reads_12s) rather than an obs_attribute row: an attribute row has no key back to its obs row, so a filter detecting one taxon by both assays could not say which read count was which (decision B4, 2026-10-01).
Detections are then aggregated to one row per filter x taxon x assay: reads summed over the taxon’s ASVs and over the filter’s PCR replicate libraries for that assay. The per-assay filtered-read totals in sample_measurement are summed over the same libraries, so edna_reads_* / edna_reads_filtered_* is the taxon’s share of the reads the assay produced for that filter.
dbWriteTable(con, "edna_dna", as.data.frame(d_dna), overwrite = TRUE)

# assay code -> the suffix of the measurement types it emits
assay_map <- tribble(
  ~target_gene,                    ~assay,  ~library_suffix,
  "D-loop",                        "dloop", "_DL",
  "12S rRNA (SSU mitochondria)",   "12s",   "_MiFish")
dbWriteTable(con, "edna_assay_map", assay_map, overwrite = TRUE)

stopifnot("every dnaderiveddata.target_gene must be a known assay" =
            all(unique(d_dna$target_gene) %in% assay_map$target_gene))

d_assay <- dbGetQuery(con, "
  SELECT o.occurrenceID, o.parentEventID, o.eventID, o.scientificNameID,
         CAST(o.organismQuantity AS BIGINT) AS reads,
         m.assay, m.library_suffix
  FROM edna_occurrence o
  JOIN edna_dna        d USING (occurrenceID)
  JOIN edna_assay_map  m ON m.target_gene = d.target_gene")
stopifnot(
  "every occurrence must resolve an assay" = nrow(d_assay) == nrow(d_occ),
  "a library's assay must match its eventID suffix (_DL = D-loop, _MiFish = 12S)" =
    all(str_detect(d_assay$eventID, fixed(d_assay$library_suffix))))
dbWriteTable(con, "edna_assay", d_assay, overwrite = TRUE)

# filter x taxon x assay: SUM reads over ASVs and PCR replicate libraries
dbExecute(con, "
  CREATE OR REPLACE TABLE edna_detection AS
  SELECT parentEventID, scientificNameID, assay,
         SUM(reads)               AS reads,
         COUNT(*)                 AS n_occurrence,
         COUNT(DISTINCT eventID)  AS n_library
  FROM edna_assay
  GROUP BY parentEventID, scientificNameID, assay")
[1] 74d_det <- dbGetQuery(con, "SELECT * FROM edna_detection")
stopifnot(
"edna_detection must be unique per filter x taxon x assay" =
!anyDuplicated(d_det[, c("parentEventID", "scientificNameID", "assay")]),
"the aggregation must conserve every read" =
sum(d_det$reads) == sum(d_assay$reads),
"every aggregated detection must have reads > 0" = all(d_det$reads > 0))
d_assay |>
group_by(assay) |>
summarize(
occurrences = n(), libraries = n_distinct(eventID),
filters = n_distinct(parentEventID), taxa = n_distinct(scientificNameID),
reads = sum(reads), .groups = "drop") |>
left_join(
d_det |> count(assay, name = "filter_x_taxon_rows"), by = "assay") |>
datatable(caption = "Occurrences (ASV x library) aggregated to filter x taxon x assay",
rownames = FALSE)Add Spatial
No enforce_column_types() step in this notebook (unlike ingest_calcofi_ctd-cast.qmd/ ingest_calcofi_mets.qmd/ingest_cdfw_dungeness-crab.qmd, which all call it): once add_point_geom() below adds a GEOMETRY column to edna_sample, DuckDB >= 1.5.1 cannot rewrite that table’s column types (dungeness-crab’s Data Preparation section states this explicitly, ordering its own enforce_column_types() call before add_point_geom() for the same reason). ingest_farallon_bird-mammal.qmd, ingest_sio_mesopelagic-fish.qmd, ingest_calcofi_phyllosoma.qmd, and ingest_cce-lter_euphausiids.qmd – every other ingest using add_point_geom() on its own staging table, the pattern this notebook follows – omit enforce_column_types() entirely rather than reordering around it.
load_prior_tables(
  con,
  parquet_dir = cc_stage_path("parquet", "swfsc_ichthyo"),
  tables      = c("ship", "cruise", "grid"),
  geom_tables = c("grid"),
  as_view     = TRUE)
Loaded cruise: 691 rows (VIEW)Loaded grid: 218 rows (VIEW) (GEOMETRY)Loaded ship: 48 rows (VIEW)# A tibble: 3 × 3
table rows has_geom
<chr> <dbl> <lgl>
1 cruise 691 FALSE
2 grid 218 TRUE
3 ship 48 FALSE # Q01 RESOLVED 2026-09-26: the source carries no ship/cruise id, but the
# provider metadata (GBIF/IPT page + eml.xml acknowledgements) names the
# vessel as NOAA Ship Reuben Lasker: ship_key 'RL' (ship_nodc '33UD'), set in
# build-sample. Keyed by the shared helper's span containment (cruise-key
# skill), before add_point_geom() so no UPDATE touches the geom table.
resolve_cruise_key(con, "edna_sample", datetime_col = "datetime_start_utc",
require_in_cruise = TRUE) |>
datatable(caption = "cruise_key resolution method")cruise_key on edna_sample: span 47add_point_geom(con, "edna_sample", lon_col = "longitude", lat_col = "latitude")Added geom column to edna_sample tableassign_grid_key(con, "edna_sample") |> datatable(caption = "Grid assignment")Assigned grid_key to edna_sample: in_grid = 47n_sk <- dbGetQuery(con, "SELECT COUNT(*) FROM edna_sample WHERE grid_key IS NOT NULL")[[1]]
n_ck <- dbGetQuery(con, "SELECT COUNT(*) FROM edna_sample WHERE cruise_key IS NOT NULL")[[1]]
n_all <- dbGetQuery(con, "SELECT COUNT(*) FROM edna_sample")[[1]]
stopifnot(
"every filter must resolve a cruise_key (one Reuben Lasker cruise, Q01)" = n_ck == n_all,
"every filter must resolve a grid_key" = n_sk == n_all)
cat(glue("grid_key resolved: {n_sk}/{n_all}; cruise_key resolved: {n_ck}/{n_all}"), "\n")grid_key resolved: 47/47; cruise_key resolved: 47/47 Water Chemistry + Genomics QC (sample_measurement)
extendedmeasurementorfact.txt repeats every value on every occurrence. Most of its distinct measurementType values are FAIRe-checklist protocol text (kit names, SOP links, extraction dates) with no place in a value/unit table. What is kept, at two grains (both asserted below, not assumed):
- per filter – the co-collected nutrients,
chl_fluor, dissolved oxygen and the extracted-DNA concentration: one value perparentEventID. Five reuse canonical types with the same unit (ammonia,nitrate,nitrite,phosphate,silicate) andchl_fluor; oxygen is reported in mg/L, which no existing oxygen type uses, so it isoxygen_mg_lrather than a converted value (Q03). - per library – the raw and the filtered read totals: one value per
eventID. Summed over the filter’s libraries of each assay intoedna_reads_raw_<assay>andedna_reads_filtered_<assay>; the filtered total is the denominator ofedna_reads_<assay>.
One library-level value is not published, pending the provider (Q04): the “Total number of OTUs or ASVs assigned to taxa”, which is not an OTU count – it equals the library’s summed organismQuantity (a read count) in nearly every library. The evidence is computed below.
dbWriteTable(con, "edna_emof", as.data.frame(d_emof), overwrite = TRUE)

src_raw  <- "The total number of raw sequence reads for each sample. Unit = reads"
src_filt <- paste(
  "The number of filtered sequence reads for each sample, that made it through",
  "bioinformatic filtering and used for final/subsequent analyses. Unit = reads")
src_otu  <- paste(
  "Total number of OTUs or ASVs assigned to taxa based on the study-specific",
  "thresholds for each sample")

# source_unit is asserted against measurementUnit, so a mapped type cannot
# silently change unit under us; level is the grain the value repeats at
emof_type_map <- tribble(
  ~source_type,                                  ~source_unit,               ~measurement_type,     ~level,
  "Concentration of ammonia in the sample",      "umol/L",                   "ammonia",             "filter",
  "Concentration of nitrate in the sample",      "umol/L",                   "nitrate",             "filter",
  "Concentration of nitrite in the sample",      "umol/L",                   "nitrite",             "filter",
  "Concentration of phosphate in the sample",    "umol/L",                   "phosphate",           "filter",
  "Concentration of silicate in the sample",     "umol/L",                   "silicate",            "filter",
  "Chlorophyll fluorescence",                    "micrograms per litre",     "chl_fluor",           "filter",
  "Concentration of dissolved oxygen",           "mg/L",                     "oxygen_mg_l",         "filter",
  "Concentration of total DNA after extraction", "nanograms per microlitre", "dna_concentration",   "filter",
  src_raw,                                       "reads",                    "edna_reads_raw",      "library",
  src_filt,                                      "reads",                    "edna_reads_filtered", "library")
dbWriteTable(con, "emof_type_map", emof_type_map, overwrite = TRUE)

d_emof_m <- dbGetQuery(con, "
  SELECT a.parentEventID, a.eventID, a.assay,
         m.measurement_type, m.level, m.source_unit,
         e.measurementUnit                       AS unit,
         e.measurementValue                      AS value_raw,
         TRY_CAST(e.measurementValue AS DOUBLE)  AS value
  FROM edna_emof e
  JOIN edna_assay    a USING (occurrenceID)
  JOIN emof_type_map m ON m.source_type = e.measurementType")

# the FAIRe checklist's own missing-value terms are the only non-numbers allowed;
# they are absences of a value, so they emit no row (S1)
faire_missing <- c("missing", "missing: not provided")
d_nonnum <- d_emof_m |> filter(is.na(value)) |> distinct(measurement_type, parentEventID, value_raw)
stopifnot(
  "every mapped eMoF measurementType must be present in the source" =
    setequal(unique(d_emof_m$measurement_type), emof_type_map$measurement_type),
  "every mapped eMoF value must carry its expected measurementUnit" =
    all(d_emof_m$unit == d_emof_m$source_unit),
  "a non-numeric eMoF value must be a FAIRe missing-value term" =
    all(d_nonnum$value_raw %in% faire_missing))

# the grain each value repeats at is asserted, never assumed: a filter value is
# identical on every occurrence of its parentEventID, a library value on every
# occurrence of its eventID. This replaces a MIN() that hid any disagreement.
n_filter_conflict <- d_emof_m |> filter(level == "filter") |>
  group_by(parentEventID, measurement_type) |>
  summarize(n = n_distinct(value_raw), .groups = "drop") |> filter(n > 1) |> nrow()
n_library_conflict <- d_emof_m |> filter(level == "library") |>
  group_by(eventID, measurement_type) |>
  summarize(n = n_distinct(value_raw), .groups = "drop") |> filter(n > 1) |> nrow()
stopifnot(
  "a per-filter eMoF value must be identical across the filter's occurrences" =
    n_filter_conflict == 0,
  "a per-library eMoF value must be identical across the library's occurrences" =
    n_library_conflict == 0)

d_ctx_filter <- d_emof_m |>
  filter(level == "filter", !is.na(value)) |>
  distinct(parentEventID, measurement_type, measurement_value = value)

# per assay: SUM over the filter's libraries of that assay, the same libraries
# the obs read counts are summed over
d_ctx_library <- d_emof_m |>
  filter(level == "library", !is.na(value)) |>
  distinct(parentEventID, eventID, assay, measurement_type, value) |>
  group_by(parentEventID, measurement_type = paste0(measurement_type, "_", assay)) |>
  summarize(measurement_value = sum(value), .groups = "drop")

d_context <- bind_rows(d_ctx_filter, d_ctx_library)
stopifnot("edna_context must be unique per filter x measurement_type" =
            !anyDuplicated(d_context[, c("parentEventID", "measurement_type")]))
dbWriteTable(con, "edna_context", as.data.frame(d_context), overwrite = TRUE)

n_dropped_types <- dbGetQuery(con, "
  SELECT COUNT(DISTINCT measurementType) FROM edna_emof
  WHERE measurementType NOT IN (SELECT source_type FROM emof_type_map)")[[1]]
cat(glue(
  "sample_measurement staged: {nrow(d_context)} rows across ",
  "{n_distinct(d_context$measurement_type)} types and ",
  "{n_distinct(d_context$parentEventID)} filters; ",
  "{nrow(d_nonnum)} FAIRe 'missing' values emit no row ",
  "({paste(unique(d_nonnum$measurement_type), collapse = ', ')}); ",
  "{n_dropped_types} other measurementTypes not published"), "\n")
sample_measurement staged: 482 rows across 12 types and 47 filters; 2 FAIRe 'missing' values emit no row (chl_fluor, dna_concentration); 53 other measurementTypes not published # raw >= filtered in every library, and the evidence for the value held back (Q04)
d_lib_qc <- dbGetQuery(con, glue("
SELECT a.eventID, a.assay,
MAX(CASE WHEN e.measurementType = '{src_raw}' THEN TRY_CAST(e.measurementValue AS BIGINT) END) AS raw,
MAX(CASE WHEN e.measurementType = '{src_filt}' THEN TRY_CAST(e.measurementValue AS BIGINT) END) AS filtered,
MAX(CASE WHEN e.measurementType = '{src_otu}' THEN TRY_CAST(e.measurementValue AS BIGINT) END) AS otu_or_asv
FROM edna_emof e JOIN edna_assay a USING (occurrenceID)
GROUP BY a.eventID, a.assay")) |>
left_join(
d_assay |> group_by(eventID) |> summarize(reads_published = sum(reads)),
by = "eventID")
n_lib <- nrow(d_lib_qc)
n_otu_eq_reads <- sum(d_lib_qc$otu_or_asv == d_lib_qc$reads_published)
n_otu_ge_reads <- sum(d_lib_qc$otu_or_asv >= d_lib_qc$reads_published)
stopifnot(
"every library must carry a raw and a filtered read total" =
!anyNA(d_lib_qc$raw) && !anyNA(d_lib_qc$filtered),
"filtered reads can never exceed raw reads" = all(d_lib_qc$filtered <= d_lib_qc$raw),
"published reads can never exceed the library's filtered reads" =
all(d_lib_qc$reads_published <= d_lib_qc$filtered))
cat(glue(
"raw >= filtered >= published reads in all {n_lib} libraries"), "\n")raw >= filtered >= published reads in all 76 libraries cat(glue(
"'OTUs or ASVs assigned to taxa' equals the library's summed organismQuantity in ",
"{n_otu_eq_reads} of {n_lib} libraries (>= it in {n_otu_ge_reads}); range ",
"{min(d_lib_qc$otu_or_asv)}-{max(d_lib_qc$otu_or_asv)} -- a read count, not ",
"richness; not published (Q04)"), "\n")'OTUs or ASVs assigned to taxa' equals the library's summed organismQuantity in 72 of 76 libraries (>= it in 76); range 2-3227195 -- a read count, not richness; not published (Q04) d_lib_qc |>
arrange(assay, eventID) |>
datatable(caption = "Per-library read totals (otu_or_asv held back, Q04)",
rownames = FALSE)Declare and Enforce Physical Bounds
Every ingest that emits measurements checks them against metadata/measurement_type.csv’s declared bounds (measurement-bounds skill): here on edna_context before it becomes sample_measurement, and again on the emitted obs after Emit Core Tables. Every type this dataset emits declares at least valid_min = 0, so an undeclared finding is a hard stop rather than a note; an out_of_range one is enforced by drop_out_of_bounds() and reported.
d_bounds <- check_measurement_bounds(con, "edna_context", mt = d_meas_type)
bounds_datatable(d_bounds)stopifnot("every sample_measurement type must declare a bound" =
!any(d_bounds$status == "undeclared"))oob_tally <- drop_out_of_bounds(con, "edna_context", mt = d_meas_type)edna_context: no values outside declared boundscat(glue("out-of-bounds rows dropped from edna_context: {sum(oob_tally$n_bad)}"), "\n")out-of-bounds rows dropped from edna_context: 0 Schema Documentation
Color scheme: lightblue = new dataset tables, lightgreen = taxon staging, lightyellow = amended reference tables, white = shared metadata.
edna_rels <- list(
  primary_keys = list(
    edna_sample    = "parent_event_id",
    edna_assay     = "occurrenceID",
    edna_detection = c("parentEventID", "scientificNameID", "assay"),
    edna_context   = c("parentEventID", "measurement_type"),
    measurement_type = "measurement_type"),
  foreign_keys = list(
    list(table = "edna_assay", column = "parentEventID",
         ref_table = "edna_sample", ref_column = "parent_event_id"),
    list(table = "edna_detection", column = "parentEventID",
         ref_table = "edna_sample", ref_column = "parent_event_id"),
    list(table = "edna_context", column = "parentEventID",
         ref_table = "edna_sample", ref_column = "parent_event_id"),
    list(table = "edna_context", column = "measurement_type",
         ref_table = "measurement_type", ref_column = "measurement_type")))

cc_erd(
  con,
  tables = c("edna_sample", "edna_assay", "edna_detection", "edna_context",
             "measurement_type", "dataset"),
  rels   = edna_rels,
  colors = list(
    lightblue   = c("edna_sample", "edna_assay", "edna_detection", "edna_context"),
    lightyellow = "measurement_type",
    white       = "dataset"))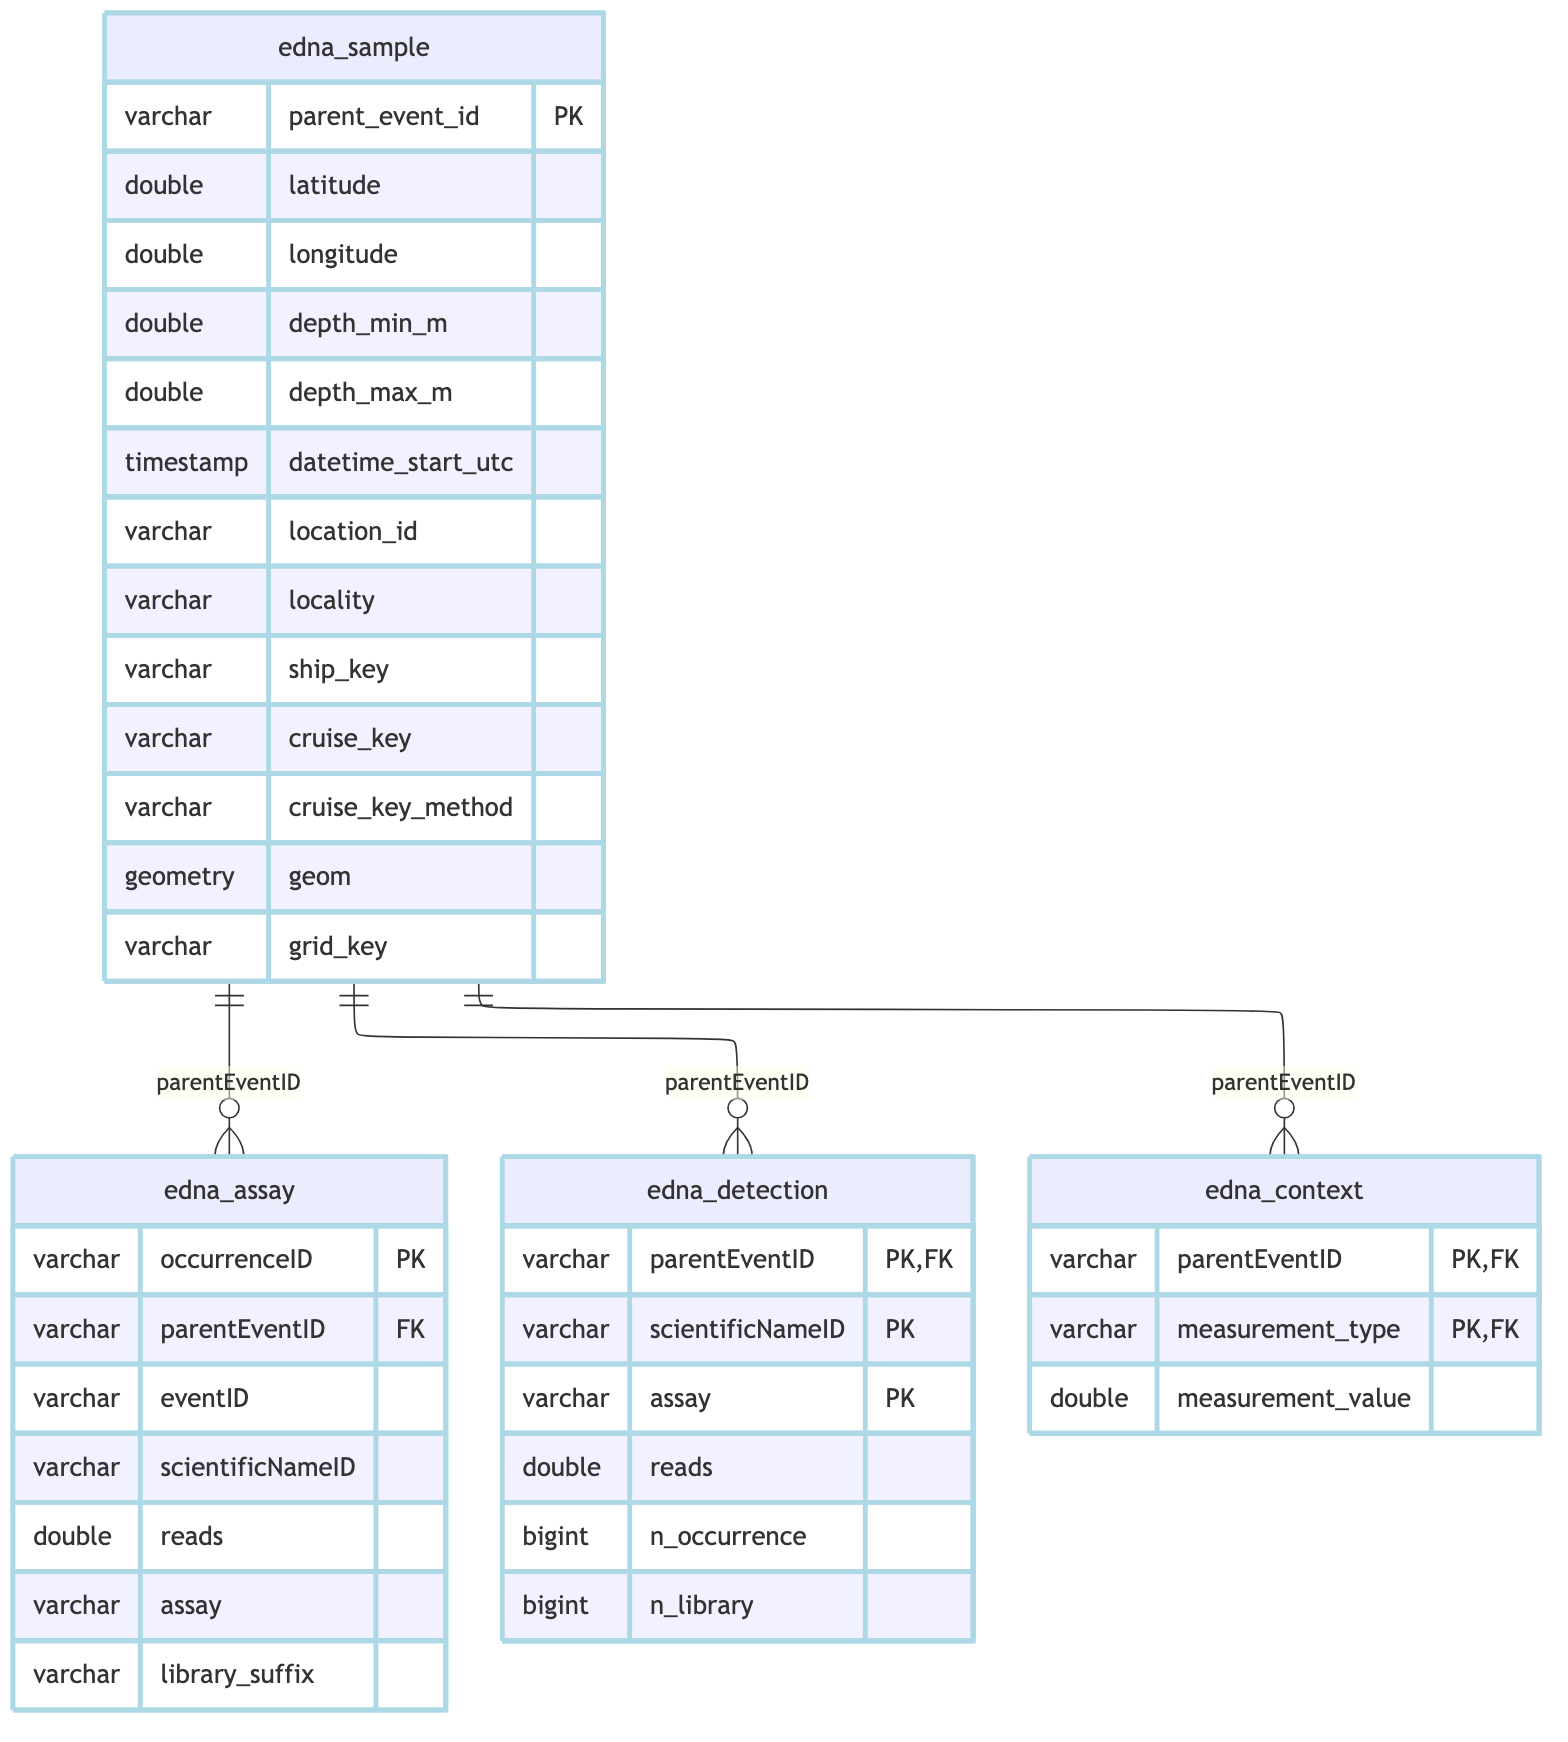
Emit Core Tables
Projection lives here, in the notebook, per the no-switch(dataset_key, ...) rule – no calcofi4db change needed for this dataset. sample_key is calcofi_2022-edna:filter:<parentEventID> (dataset_key:sample_type:id). There is no obs_attribute: the assay lives in the measurement type.
# 1. sample -- one row per physical water filter (parentEventID grain)
append_sample(con, glue("
  SELECT {ns_key(ds_key, 'filter', 'parent_event_id')} AS sample_key,
         'filter' AS sample_type, NULL::VARCHAR AS parent_sample_key,
         {ns_key(ds_key, 'filter', 'parent_event_id')} AS root_sample_key,
         '{ds_key}' AS dataset_key, grid_key, NULL::VARCHAR AS site_key, cruise_key,
         NULL::INTEGER AS order_occ,
         latitude, longitude, datetime_start_utc AS datetime,
         depth_min_m, depth_max_m, NULL::VARCHAR AS tow_type
  FROM edna_sample"))
Loaded extension: spatial# 2. obs -- bound positionally: realm, dataset_key, sample_key, grid_key,
# cruise_key, latitude, longitude, datetime, depth_min_m, depth_max_m, taxon_key,
# life_stage, measurement_type, measurement_value, measurement_qual,
# measurement_prec. life_stage is NULL: a water-filter detection has none.
# (a) edna_presence -- the cross-dataset headline, the same type and meaning as
# sio_cetacean-edna: 1 = the taxon's DNA was detected (reads > 0 after the
# provider's own filtering) by any assay in this filter. Positive
# detections only, so never 0 here.
# (b) edna_reads_<assay> -- reads summed over ASVs and PCR replicate libraries
# (edna_detection), one row per filter x taxon x assay.
obs_cols <- glue("
'{ds_key}', {ns_key(ds_key, 'filter', 'd.parentEventID')},
s.grid_key, s.cruise_key, s.latitude, s.longitude, s.datetime_start_utc,
s.depth_min_m, s.depth_max_m, dt.taxon_key, NULL::VARCHAR")
obs_from <- glue("
JOIN edna_sample s ON s.parent_event_id = d.parentEventID
LEFT JOIN dataset_taxon dt ON dt.dataset_key = '{ds_key}'
AND dt.ds_taxa_code = d.scientificNameID")
append_obs(con, glue("
SELECT 'bio', {obs_cols},
'edna_presence', 1::DOUBLE, NULL::VARCHAR, NULL::DOUBLE
FROM (SELECT DISTINCT parentEventID, scientificNameID
FROM edna_detection WHERE reads > 0) d
{obs_from}"))Loaded extension: h3append_obs(con, glue("
SELECT 'bio', {obs_cols},
'edna_reads_' || d.assay, CAST(d.reads AS DOUBLE), NULL::VARCHAR, NULL::DOUBLE
FROM edna_detection d
{obs_from}"))Loaded extension: h3# 3. sample_measurement -- co-collected water chemistry, DNA concentration and
# the per-assay filtered-read totals; a FAIRe 'missing' emitted no row upstream
append_sample_measurement(con, glue("
SELECT {ns_key(ds_key, 'filter', 'parentEventID')}, '{ds_key}',
measurement_type, measurement_value, NULL::VARCHAR
FROM edna_context
WHERE measurement_value IS NOT NULL"))
core <- list(
sample = dbGetQuery(con, glue("SELECT COUNT(*) FROM sample WHERE dataset_key = '{ds_key}'"))[[1]],
obs = dbGetQuery(con, glue("SELECT COUNT(*) FROM obs WHERE dataset_key = '{ds_key}'"))[[1]],
sample_measurement = dbGetQuery(con, glue("SELECT COUNT(*) FROM sample_measurement WHERE dataset_key = '{ds_key}'"))[[1]])
# the grain contract, asserted -------------------------------------------------
d_obs_chk <- dbGetQuery(con, glue("
SELECT sample_key, taxon_key, measurement_type, measurement_value
FROM obs WHERE dataset_key = '{ds_key}'"))
n_presence <- sum(d_obs_chk$measurement_type == "edna_presence")
stopifnot(
"one sample row per filter" = core$sample == n_parent,
"every sample_key must be dataset_key:filter:id" =
dbGetQuery(con, glue("
SELECT COUNT(*) FROM sample
WHERE dataset_key = '{ds_key}'
AND (sample_type <> 'filter' OR sample_key NOT LIKE '{ds_key}:filter:%')"))[[1]] == 0,
"every eDNA observation must resolve a taxon_key" = !anyNA(d_obs_chk$taxon_key),
"obs must be unique per (sample_key, taxon_key, measurement_type)" =
!anyDuplicated(d_obs_chk[, c("sample_key", "taxon_key", "measurement_type")]),
"one edna_presence row per filter x taxon detected" =
n_presence == nrow(distinct(d_det, parentEventID, scientificNameID)),
"edna_presence is 1 on every row (positive detections only)" =
all(d_obs_chk$measurement_value[d_obs_chk$measurement_type == "edna_presence"] == 1),
"one edna_reads_* row per filter x taxon x assay" =
sum(startsWith(d_obs_chk$measurement_type, "edna_reads_")) == nrow(d_det),
"obs must carry every published read" =
sum(d_obs_chk$measurement_value[startsWith(d_obs_chk$measurement_type, "edna_reads_")]) ==
sum(d_assay$reads),
"no NULL measurement_value in obs" = !anyNA(d_obs_chk$measurement_value),
"no NULL measurement_value in sample_measurement" =
dbGetQuery(con, glue("
SELECT COUNT(*) FROM sample_measurement
WHERE dataset_key = '{ds_key}' AND measurement_value IS NULL"))[[1]] == 0)
d_core_types <- dbGetQuery(con, glue("
SELECT 'obs' AS tbl, measurement_type, COUNT(*) AS n
FROM obs WHERE dataset_key = '{ds_key}' GROUP BY ALL
UNION ALL
SELECT 'sample_measurement', measurement_type, COUNT(*)
FROM sample_measurement WHERE dataset_key = '{ds_key}' GROUP BY ALL
ORDER BY 1, 2"))
d_core_types |> datatable(caption = "Rows per measurement_type emitted", rownames = FALSE)cat(glue(
"core projection -- sample={core$sample} obs={core$obs} ",
"({n_presence} edna_presence + {core$obs - n_presence} edna_reads_*) ",
"sample_measurement={core$sample_measurement}; no obs_attribute"), "\n")core projection -- sample=47 obs=148 (74 edna_presence + 74 edna_reads_*) sample_measurement=482; no obs_attribute # S5: bounds on what is actually published, not only on the staging table
d_bounds_obs <- check_measurement_bounds(con, "obs", mt = d_meas_type, dataset_key = ds_key)
bounds_datatable(d_bounds_obs)stopifnot(
"every obs type must declare a bound" = !any(d_bounds_obs$status == "undeclared"),
"no obs value may lie outside its declared bound" =
!any(d_bounds_obs$status == "out_of_range"))Measurement Type Registry
The new types were added to metadata/measurement_type.csv once, with register_measurement_types(), not by this notebook: rewriting the shared registry on every render is a side effect on a file other ingests edit. The notebook asserts the contract in both directions – every type it emits is registered, and every registered type that names this dataset in _source_datasets has at least one row.
dbWriteTable(con, "measurement_type", as.data.frame(d_meas_type), overwrite = TRUE)

emitted    <- unique(d_core_types$measurement_type)
registered <- d_meas_type |>
  filter(map_lgl(str_split(coalesce(`_source_datasets`, ""), ";\\s*"), ~ ds_key %in% .x)) |>
  pull(measurement_type)

unregistered <- setdiff(emitted, d_meas_type$measurement_type)
unclaimed    <- setdiff(emitted, registered)
empty        <- setdiff(registered, emitted)
stopifnot(
  "every emitted measurement_type must be in metadata/measurement_type.csv" =
    length(unregistered) == 0,
  "every emitted measurement_type must list this dataset in _source_datasets" =
    length(unclaimed) == 0,
  "every registered type naming this dataset must have >= 1 row (an empty type would ship)" =
    length(empty) == 0)
cat(glue("measurement types: {length(emitted)} emitted, all registered and claimed; ",
         "0 registered-but-empty"), "\n")
measurement types: 15 emitted, all registered and claimed; 0 registered-but-empty Load Dataset Metadata
this_provider <- provider; this_dataset <- dataset
d_dataset <- ingest_yaml_to_dataset_df(read_ingest_yaml(here())) |>
  filter(provider == this_provider, dataset == this_dataset)
stopifnot("this dataset must appear in the ingest YAML registry" = nrow(d_dataset) == 1)
dbWriteTable(con, "dataset", as.data.frame(d_dataset), overwrite = TRUE)
Questions for Data Providers
questions_datatable(
  here(cc$questions_file),
  caption = "Questions for the calcofi 2022-edna data providers (ranked)")
Validate
results <- validate_for_release(con, checks = "all", strict = FALSE)

# validate_for_release()'s null check treats every *_id/_key column as required,
# a heuristic rather than this dataset's contract. Every nullable case is
# declared here with its count and reason (the cdfw_dungeness-crab idiom);
# anything not on the list, or whose count moved, is a hard failure.
nullable <- tribble(
  ~table,   ~column,             ~n,  ~reason,
  "sample", "parent_sample_key", 47L, "a filter is a root event: no link yet to the bottle/cast it came from (provider question Q05)",
  "sample", "site_key",          47L, "no station match yet; locationID names the CalCOFI station but is not parsed (Q05)",
  "taxon",  "itis_id",           12L, "WoRMS links no ITIS TSN for these lineage nodes",
  "taxon",  "gbif_id",           79L, "nothing asks GBIF -- no GBIF crosswalk in the xref",
  "taxon",  "ncbi_id",           79L, "never populated by ANY dataset",
  "taxon",  "inat_id",           79L, "never populated by ANY dataset",
  "taxon",  "parent_taxon_key",  1L,  "the root of the lineage (Biota) has no parent")

nulls <- results$checks |>
  filter(check == "nulls", status == "error") |>
  mutate(column = str_match(message, "column '([^']+)'")[, 2],
         n      = as.integer(str_match(message, "has (\\d+) NULL")[, 2])) |>
  select(table, column, n)

reconciled  <- full_join(nulls, nullable |> select(table, column, n_expected = n),
                         by = c("table", "column"))
unexplained <- reconciled |> filter(is.na(n_expected))
moved       <- reconciled |> filter(!is.na(n_expected), !is.na(n), n != n_expected)
resolved    <- reconciled |> filter(!is.na(n_expected), is.na(n))
other_fail  <- results$checks |> filter(check != "nulls", status == "error")
if (nrow(unexplained)) print(unexplained)
if (nrow(moved))       print(moved)
if (nrow(other_fail))  print(other_fail)
stopifnot(
  "a NULL appeared in a column with no declared reason" = nrow(unexplained) == 0,
  "a declared NULL count has changed -- the data moved, re-derive the reason" = nrow(moved) == 0,
  "a validate_for_release() check other than nulls failed" = nrow(other_fail) == 0)
if (nrow(resolved))
  cat(glue("{nrow(resolved)} declared nullable case(s) no longer occur -- prune them: ",
           "{paste(resolved$table, resolved$column, sep = '.', collapse = ', ')}"), "\n")
if (length(results$warnings) > 0)
  cat("Warnings:\n", paste("-", results$warnings, collapse = "\n"), "\n")

cat(glue("validate_for_release: {ifelse(results$passed, 'PASSED', 'FAILED')} on its null ",
         "heuristic; {nrow(nulls)} null case(s) reconciled against {nrow(nullable)} declared, ",
         "0 unexplained, 0 other failures"), "\n")
validate_for_release: FAILED on its null heuristic; 7 null case(s) reconciled against 7 declared, 0 unexplained, 0 other failures Data Preview
dbGetQuery(con, "SELECT * FROM sample WHERE dataset_key = 'calcofi_2022-edna'") |>
datatable(caption = "sample", rownames = FALSE)dbGetQuery(con, "SELECT * FROM obs WHERE dataset_key = 'calcofi_2022-edna' LIMIT 50") |>
datatable(caption = "obs (first 50)", rownames = FALSE)dbGetQuery(con, "SELECT * FROM sample_measurement WHERE dataset_key = 'calcofi_2022-edna'") |>
datatable(caption = "sample_measurement", rownames = FALSE)Write Parquet Outputs
tbls_out <- core_output_tables(con, extra = c("measurement_type", "dataset"))
write_parquet_outputs(con, dir_parquet, tables = tbls_out)
Exported sample: 47 rows, 0 MBExported obs: 148 rows, 0.01 MBExported sample_measurement: 482 rows, 0 MBExported taxon: 79 rows, 0.01 MBExported dataset_taxon: 19 rows, 0 MBExported measurement_type: 229 rows, 0.02 MBExported dataset: 1 rows, 0.01 MBWrote manifest to /Users/bbest/Github/CalCOFI/.worktrees/workflows-pr118/data/parquet/calcofi_2022-edna/manifest.json# A tibble: 7 × 5
table rows file_size path partitioned
<chr> <dbl> <dbl> <chr> <lgl>
1 sample 47 5042 sample.parquet FALSE
2 obs 148 5840 obs.parquet FALSE
3 sample_measurement 482 4659 sample_measurement.parquet FALSE
4 taxon 79 6238 taxon.parquet FALSE
5 dataset_taxon 19 2393 dataset_taxon.parquet FALSE
6 measurement_type 229 17904 measurement_type.parquet FALSE
7 dataset 1 8051 dataset.parquet FALSE Write Metadata
metadata_path <- build_metadata_json(
  con                  = con,
  d_tbls_rd            = d_tbls_rd,
  d_flds_rd            = d_flds_rd,
  metadata_derived_csv = c(here("metadata/core_dictionary.csv"),
                           glue("{dir_meta}/metadata_derived.csv")),
  output_dir           = dir_parquet,
  tables               = tbls_out,
  provider             = provider,
  dataset              = dataset,
  workflow_url         = cc$workflow_url,
  tables_owned         = tables_owned)
Set DuckDB COMMENT ON for tables and columnsWrote metadata.json: 7 tables, 109 columnsmetadata.json documentation gaps (7 tables, 109 columns) — these render blank in cc_describe_table() / cc_db_catalog():
tables with no description_md: 2 measurement_type, dataset
columns with no description_md: 43 dataset.provider, dataset.dataset, dataset.dataset_name, dataset.dataset_name_short, dataset.category, dataset.color, dataset.description, dataset.citation_main, dataset.citation_others, dataset.link_calcofi_org, dataset.link_data_source, dataset.link_others (+31 more)
measurement columns with no units: 34 dataset.dataset_name_short, dataset.category, dataset.color, dataset.citation_main, dataset.citation_others, dataset.link_calcofi_org, dataset.link_data_source, dataset.link_others, dataset.tables, dataset.coverage_temporal, dataset.coverage_spatial, dataset.license (+22 more)
backfill via metadata/{provider}/{dataset}/flds_redefine.csv, then re-runbuild_relationships_json(
rels = core_relationships(tbls_out),
output_dir = dir_parquet,
provider = provider,
dataset = dataset)Wrote relationships.json: 7 PKs, 9 FKs[1] "/Users/bbest/Github/CalCOFI/.worktrees/workflows-pr118/data/parquet/calcofi_2022-edna/relationships.json"Upload to GCS
# local_dir/sidecar_dir split matches ingest_sio_mesopelagic-fish.qmd and
# ingest_calcofi_ctd-cast.qmd exactly -- both pass dir_stage as local_dir and
# dir_parquet as sidecar_dir here, even though every write above (parquet
# tables, metadata.json, relationships.json) targets dir_parquet.
# delete_stale: the 2026-10-01 grain change dropped obs_attribute from this
# shard, and a stale obs_attribute.parquet must not linger under the prefix
# (sidecars are protected from the delete by sync_to_gcs() itself)
sync_to_gcs(
  local_dir    = dir_stage,
  sidecar_dir  = dir_parquet,
  gcs_prefix   = glue("ingest/{dir_label}"),
  bucket       = "calcofi-db",
  delete_stale = TRUE)
rsync /Users/bbest/_big/calcofi/parquet/calcofi_2022-edna -> gs://calcofi-db/ingest/calcofi_2022-ednaCopied 3 sidecar(s) from /Users/bbest/Github/CalCOFI/.worktrees/workflows-pr118/data/parquet/calcofi_2022-ednaSync complete: 10 copied, 2 removed (rsync)# A tibble: 12 × 4
file action size reason
<chr> <chr> <dbl> <chr>
1 <rsync> uploaded NA parallel rsync
2 <rsync> uploaded NA parallel rsync
3 <rsync> uploaded NA parallel rsync
4 <rsync> uploaded NA parallel rsync
5 <rsync> uploaded NA parallel rsync
6 <rsync> uploaded NA parallel rsync
7 <rsync> uploaded NA parallel rsync
8 <rsync> uploaded NA parallel rsync
9 <rsync> uploaded NA parallel rsync
10 <rsync> uploaded NA parallel rsync
11 <rsync> deleted NA parallel rsync
12 <rsync> deleted NA parallel rsyncCleanup
close_duckdb(con)
cat(glue("parquet outputs written to: {dir_parquet}"), "\n")
parquet outputs written to: /Users/bbest/Github/CalCOFI/.worktrees/workflows-pr118/data/parquet/calcofi_2022-edna