---
title: "Ingest Underway CUFES Fish Eggs"
calcofi:
target_name: ingest_swfsc_cufes
workflow_type: ingest
dependency:
- ingest_swfsc_ichthyo
output: data/parquet/swfsc_cufes/manifest.json
provider: swfsc
dataset: cufes
workflow_url: https://calcofi.io/workflows/ingest_swfsc_cufes.html
questions_file: metadata/swfsc/cufes/questions.csv
dataset_meta:
dataset_name: CalCOFI Underway CUFES Fish Eggs
# display trio, read by the release `dataset` table and the
# consumer apps (calcofi4db >= 3.15.0) — see NEWS for why these
# left the apps' own hardcoded maps
dataset_name_short: CUFES Fish Eggs
category: "Fish Eggs & Larvae"
color: "#af8a11"
# publishes the consolidated core: the underway sample/measurement source shape
# is wrangled in the notebook and projected into sample / obs + the taxa refs.
tables_owned:
- {table: sample, shared: true, note: "core event dimension (underway grain)"}
- {table: obs, shared: true, note: "core occurrence headline (bio, egg counts and eggs/m3 by species)"}
- {table: taxon, shared: true, note: "shared taxa reference"}
- {table: dataset_taxon, shared: true, note: "egg-type -> taxon_key crosswalk"}
- {table: measurement_type, shared: true}
erd:
color: "#f0e8bb"
editor_options:
chunk_output_type: console
---
## Overview
**Source**: SWFSC's CSV export of its CalCOFI database — `Cufes.csv` in the
provider folder `swfsc/ichthyo/` (Ed Weber, NOAA SWFSC, 2026-09-26: "I also added
it to the csv repo. Cufes is also now linked with CruiseId"). One row per
Continuous Underway Fish Egg Sampler (CUFES) sample: start and stop time and
position, underway temperature, salinity, wind and pump speed, and the egg counts
of sardine, anchovy, jack mackerel, hake, squid and other fish. Provider `swfsc`.
**Until 2026-10-04 this ingest read NOAA CoastWatch ERDDAP `erdCalCOFIcufes`.**
Compared record by record (WS-1004Z), the CSV holds 47,989 of ERDDAP's 49,572
samples, with the same time span (1996-03-15 to 2022-04-27), identical egg counts
and start/stop times, and positions and environment equal to within float
rounding (≤ 1.5e-5). The 1,583 ERDDAP-only samples are the ones Ed removed at
source (questions Q04): 1,563 with no position at either end — three whole
cruises among them, 199809NH, 199908NH and 200001NH — and 20 with a stop position
only (Q09). So the CSV supersedes ERDDAP; nothing it lacks is a sample anyone can
place, and ERDDAP is no longer read.
What the export adds: the provider's own `CufesId` (released as
`sample.source_uuid`, and the id in `sample_key`), the `CruiseId` link to the
cruise reference (so every sample keys its cruise by the provider's own link
rather than by date), and Ed's answers on units and standardization (Q01, Q02,
Q05), applied below as the `egg_concentration` measurement type (eggs per m³
pumped).
## Setup
```{r}
#| label: setup
#| message: false
devtools::load_all(here::here("../calcofi4db"))
devtools::load_all(here::here("../calcofi4r"))
librarian::shelf(
  CalCOFI/calcofi4db, CalCOFI/calcofi4r,
  DBI, dplyr, DT, fs, glue, here, jsonlite, knitr, lubridate, purrr,
  readr, sf, stringr, tibble, tidyr, units, quiet = T)
options(readr.show_col_types = F); options(DT.options = list(scrollX = TRUE))
source(here("libs/ingest.R"))

cc <- read_calcofi_meta(here("ingest_swfsc_cufes.qmd"))
provider <- cc$provider; dataset <- cc$dataset; tables_owned <- cc$tables_owned
dir_label <- glue("{provider}_{dataset}")
dir_parquet <- here(glue("data/parquet/{dir_label}"))
dir_stage <- cc_stage_path("parquet", dir_label, create = TRUE)
db_path <- here(glue("data/wrangling/{dir_label}.duckdb"))
if (overwrite && file_exists(db_path)) file_delete(db_path)
dir_create(dirname(db_path)); con <- get_duckdb_con(db_path); load_duckdb_extension(con, "spatial")
meas_type_csv <- here("metadata/measurement_type.csv"); d_meas_type <- read_measurement_type(meas_type_csv)
ds_key <- "swfsc_cufes"

# a local verification run sets CALCOFI_SKIP_GCS so nothing reaches a bucket
publish_to_gcs <- Sys.getenv("CALCOFI_SKIP_GCS") == ""
```
## Read Source Data
`libs/download_cufes.R` copies `Cufes.csv` byte for byte from the provider folder
to the stage (nothing is written in Drive), asserts its 27-column header, and the
staged copy is archived to `gs://calcofi-files-public/archive/swfsc/cufes/`. The
columns are renamed and typed by `metadata/swfsc/cufes/flds_redefine.csv` (lower
snake_case; authored by `libs/build_cufes_metadata.R`), which must name every
source column exactly.
```{r}
#| label: read-source
source(here("libs/download_cufes.R"))
src <- stage_cufes_source(
  dir_src = path_expand(glue("{dir_data}/swfsc/ichthyo")),
  out_dir = cc_stage_path("source", dir_label, create = TRUE),
  overwrite = overwrite_all)
cat(glue("Cufes.csv: {format(src$bytes, big.mark = ',')} bytes, md5 {src$md5}, ",
         "modified {format(src$modified, '%Y-%m-%d %H:%M')}"), "\n")
if (publish_to_gcs) {
  sync_to_gcs(
    local_dir  = path_dir(src$csv),
    gcs_prefix = glue("archive/{provider}/{dataset}"),
    bucket     = "calcofi-files-public",
    exclude    = c(".DS_Store", "*.tmp"))
} else cat("CALCOFI_SKIP_GCS set — source not archived (local verification run)\n")
d_flds_rd <- read_csv(here("metadata/swfsc/cufes/flds_redefine.csv"))
d_tbls_rd <- read_csv(here("metadata/swfsc/cufes/tbls_redefine.csv"))
d_raw     <- read_csv(src$csv, col_types = cols(.default = "c"), na = c("", "NA"))

# the redefinition must cover the source exactly: a new column is a decision,
# not something to drop silently, and a vanished one is a re-shaped export
stopifnot(
  "flds_redefine.csv must name every Cufes.csv column, and only those" =
    setequal(names(d_raw), d_flds_rd$fld_old[d_flds_rd$tbl_new == "cufes"]))

fr <- d_flds_rd |> filter(tbl_new == "cufes")
cast <- list(
  VARCHAR   = as.character,
  UUID      = \(x) tolower(x),
  INTEGER   = \(x) as.integer(x),
  DOUBLE    = \(x) as.numeric(x),
  TIMESTAMP = \(x) ymd_hms(x, tz = "UTC"))
d <- d_raw |> select(all_of(fr$fld_old))
for (i in seq_len(nrow(fr))) {
  x <- d[[fr$fld_old[i]]]
  y <- suppressWarnings(cast[[fr$type_new[i]]](x))
  # a value present in the source must survive its cast
  n_lost <- sum(!is.na(x) & is.na(y))
  if (n_lost > 0)
    stop(glue("{fr$fld_old[i]} -> {fr$type_new[i]}: {n_lost} value(s) fail to parse"))
  d[[fr$fld_old[i]]] <- y
}
names(d) <- fr$fld_new

stopifnot(
  "cufes_uuid must be unique and present" =
    !anyNA(d$cufes_uuid) && !anyDuplicated(d$cufes_uuid),
  "every sample must name its cruise (CruiseId)" = !anyNA(d$cruise_uuid),
  "(cruise_uuid, sample_number) must be unique" =
    !anyDuplicated(d[c("cruise_uuid", "sample_number")]))

cat(glue(
  "{format(nrow(d), big.mark = ',')} CUFES samples, ",
  "{n_distinct(d$cruise_uuid)} cruises, ",
  "{format(min(d$datetime_start_utc), '%Y-%m-%d')} to {format(max(d$datetime_start_utc), '%Y-%m-%d')}"), "\n")
```
## Build Sample + Measurement Tables
```{r}
#| label: build
# A CUFES sample is a SEGMENT, not a point: the pump runs while the ship steams,
# and the source records where the sample started and where it stopped. Those
# ends are a median 8.71 km apart, so the start position alone — from which
# `grid_key` and `hex_id` are derived — would report a point ~4.4 km from the
# sample's centre. The position is the MIDPOINT of the segment; the ends stay as
# `start_latitude`/`start_longitude` and `stop_latitude`/`stop_longitude`.
#
# A position is a PAIR: choose the SOURCE first — midpoint, else start, else stop
# — and require both components of that source to be real (NaN passes IS NOT
# NULL, so it is tested explicitly). Since SWFSC removed the records with no start
# position at source (questions Q04), every sample of this export has a start;
# 37 have no stop and take the start.
#
# Effort, per Ed Weber (SWFSC, 2026-09-25, questions Q01/Q02/Q05): minutes sampled
# = stop - start; pump speed is m3/min and the sample's is the mean of its two
# ends; the standardization is defined only where the minutes and both pump
# speeds are positive (anything else gets no concentration, counted below).
# Both rules live in libs/cufes.R, asserted by tests/testthat/test-cufes.R.
source(here("libs/cufes.R"))
ok <- function(x) !is.na(x) & !is.nan(x) & is.finite(x)
d <- bind_cols(
  d,
  cufes_position(d$start_latitude, d$start_longitude, d$stop_latitude, d$stop_longitude),
  cufes_effort(d$datetime_start_utc, d$datetime_end_utc, d$start_pump_speed, d$stop_pump_speed))

stopifnot(
  "latitude and longitude must be present together or not at all" =
    sum(ok(d$latitude) != ok(d$longitude)) == 0)
d |> count(position_source) |>
  datatable(caption = "Which ends of the segment give each sample's position")
egg_cols <- c("sardine_eggs", "anchovy_eggs", "jack_mackerel_eggs",
              "hake_eggs", "squid_eggs", "other_fish_eggs")
d_cufes <- d |> select(-all_of(egg_cols), -conc_ok)
dbWriteTable(con, "cufes", d_cufes, overwrite = TRUE)
invisible(dbExecute(con, "ALTER TABLE cufes ALTER cufes_uuid TYPE UUID"))
invisible(dbExecute(con, "ALTER TABLE cufes ALTER cruise_uuid TYPE UUID"))

# raw egg counts, long; an empty cell is "not counted", so it is no row
d_cnt <- d |>
  select(cufes_uuid, all_of(egg_cols)) |>
  pivot_longer(all_of(egg_cols), names_to = "measurement_type", values_to = "measurement_value") |>
  filter(!is.na(measurement_value)) |>
  mutate(measurement_value = as.double(measurement_value))

# eggs/m3 = (count / minutes sampled) / mean pump speed (Ed Weber, Q01), one row
# per count whose sample has positive minutes and pump speeds
d_conc <- d_cnt |>
  inner_join(d |> filter(conc_ok) |> select(cufes_uuid, duration_min, pump_speed_mean),
             by = "cufes_uuid") |>
  mutate(
    measurement_type  = paste0(measurement_type, "_per_m3"),
    measurement_value = cufes_egg_concentration(
      measurement_value, duration_min, pump_speed_mean, conc_ok = TRUE)) |>
  select(cufes_uuid, measurement_type, measurement_value)

d_meas <- bind_rows(d_cnt, d_conc) |>
  mutate(measurement_qual = NA_character_) |>
  mutate(cufes_measurement_id = row_number(), .before = 1)
dbWriteTable(con, "cufes_measurement", d_meas, overwrite = TRUE)
invisible(dbExecute(con, "ALTER TABLE cufes_measurement ALTER cufes_uuid TYPE UUID"))

n_no_conc <- sum(!d$conc_ok)
cat(glue(
  "cufes {format(nrow(d_cufes), big.mark = ',')} samples; ",
  "{format(nrow(d_cnt), big.mark = ',')} egg counts; ",
  "{format(nrow(d_conc), big.mark = ',')} egg concentrations over ",
  "{format(sum(d$conc_ok), big.mark = ',')} samples; ",
  "{n_no_conc} sample(s) with no positive minutes / pump speeds get none"), "\n")
stopifnot(
  "every count of a sample with positive effort must get its concentration" =
    nrow(d_conc) == sum(d_cnt$cufes_uuid %in% d$cufes_uuid[d$conc_ok]))

# effort inputs worth a provider's look: a pump speed that changes more than
# two-fold within one sample (questions Q10) and samples under a minute
d |>
  filter(stop_pump_speed / start_pump_speed > 2 | stop_pump_speed / start_pump_speed < 0.5 |
           duration_min < 1) |>
  select(cruise, ship_key, sample_number, datetime_start_utc, datetime_end_utc,
         duration_min, start_pump_speed, stop_pump_speed, volume_pumped_m3) |>
  datatable(caption = "Effort inputs to check: pump speed changing > 2x within a sample (Q10), or under a minute sampled")
```
## Resolve Keys + Spatial
`cruise_key` comes from the cruise reference through the provider's own link,
`CruiseId` → `cruise.cruise_uuid` (method `cruise_uuid`). The reference is the
`cruise` shard `ingest_swfsc_ichthyo.qmd` stages from the same export's
`Cruise.csv`, so it knows every `CruiseId` this file names. The date-span rule
(`resolve_cruise_key()`: span, then the source's own `Cruise` designation, then the
month) is run beside it as a check, and is what keys any sample whose `CruiseId`
the reference lacks.
```{r}
#| label: keys-spatial
load_prior_tables(con, parquet_dir = cc_stage_path("parquet", "swfsc_ichthyo"),
                  tables = c("ship", "cruise", "grid"), geom_tables = c("grid"), as_view = TRUE)
# ship: the source's code is the reference's ship_key
n_ship_miss <- dbGetQuery(con, "
  SELECT COUNT(*) FROM cufes WHERE ship_key NOT IN (SELECT ship_key FROM ship)")[[1]]
stopifnot("every CUFES ship code must be in the ship reference" = n_ship_miss == 0)

# 1. the provider's link
invisible(dbExecute(con, "ALTER TABLE cufes ADD COLUMN IF NOT EXISTS cruise_key VARCHAR"))
invisible(dbExecute(con, "ALTER TABLE cufes ADD COLUMN IF NOT EXISTS cruise_key_method VARCHAR"))
n_by_uuid <- dbExecute(con, "
  UPDATE cufes SET cruise_key = c.cruise_key, cruise_key_method = 'cruise_uuid'
  FROM cruise c WHERE lower(CAST(c.cruise_uuid AS VARCHAR)) = lower(CAST(cufes.cruise_uuid AS VARCHAR))")
cat(glue("cruise_key by CruiseId: {format(n_by_uuid, big.mark = ',')}/{format(nrow(d_cufes), big.mark = ',')} samples"), "\n")
# the cruise CruiseId names must be of the sample's own ship
n_ship_disagree <- dbGetQuery(con, "
  SELECT COUNT(*) FROM cufes u JOIN cruise c USING (cruise_key)
  WHERE c.ship_key <> u.ship_key")[[1]]
stopifnot("CruiseId must name a cruise of the sample's own ship" = n_ship_disagree == 0)

# 2. the date-span rule, beside it: the check, and the fallback for any CruiseId
#    the reference does not know
invisible(dbExecute(con, "CREATE OR REPLACE TEMP TABLE zk AS
  SELECT cufes_uuid, ship_key, cruise, datetime_start_utc AS datetime FROM cufes"))
resolve_cruise_key(con, "zk", datetime_col = "datetime", cruise_ym_col = "cruise",
                   require_in_cruise = TRUE) |>
  datatable(caption = "resolve_cruise_key() on the same samples (span, then the source's Cruise, then the month)")
d_ck <- dbGetQuery(con, "
  SELECT CASE WHEN u.cruise_key IS NULL AND z.cruise_key IS NULL THEN 'neither'
              WHEN u.cruise_key IS NULL THEN 'cruise_uuid unmatched'
              WHEN z.cruise_key IS NULL THEN 'span/source found none'
              WHEN u.cruise_key = z.cruise_key THEN 'agree'
              ELSE 'disagree' END AS comparison,
         z.cruise_key_method AS span_method, COUNT(*) AS n_samples,
         COUNT(DISTINCT u.cruise_uuid) AS n_cruises
  FROM cufes u JOIN zk z USING (cufes_uuid) GROUP BY ALL ORDER BY ALL")
d_ck |> datatable(caption = "cruise_key by CruiseId versus by date span")
n_by_span <- dbExecute(con, "
  UPDATE cufes SET cruise_key = z.cruise_key, cruise_key_method = z.cruise_key_method
  FROM zk z WHERE cufes.cufes_uuid = z.cufes_uuid AND cufes.cruise_key IS NULL")
n_disagree <- sum(d_ck$n_samples[d_ck$comparison == "disagree"])
cat(glue(
  "cruise_key by span/source for CruiseIds the reference lacks: {n_by_span}; ",
  "CruiseId and date span disagree on {n_disagree} sample(s) (the CruiseId key is kept: ",
  "the reference wins)"), "\n")
invisible(dbExecute(con, "DROP TABLE zk"))

# the sample's date inside its cruise's observed span (the release gate's
# tolerance is 31 days; report against the 3-day span-match tolerance)
d_span <- dbGetQuery(con, "
  SELECT COUNT(*) FILTER (WHERE c.date_min IS NULL) AS n_cruise_no_span,
         COUNT(*) FILTER (WHERE CAST(u.datetime_start_utc AS DATE) NOT BETWEEN
                                c.date_min - 3 AND c.date_max + 3)  AS n_outside_3d,
         COUNT(*) FILTER (WHERE CAST(u.datetime_start_utc AS DATE) NOT BETWEEN
                                c.date_min - 31 AND c.date_max + 31) AS n_outside_31d
  FROM cufes u JOIN cruise c USING (cruise_key)")
n_ck_null <- dbGetQuery(con, "SELECT COUNT(*) FROM cufes WHERE cruise_key IS NULL")[[1]]
cat(glue(
  "cruise_key: {format(nrow(d_cufes) - n_ck_null, big.mark = ',')}/{format(nrow(d_cufes), big.mark = ',')} samples; ",
  "{n_ck_null} NULL; samples outside their cruise's tow span: ",
  "{d_span$n_outside_3d} beyond 3 days, {d_span$n_outside_31d} beyond 31 days ",
  "({d_span$n_cruise_no_span} on a cruise with no tow span)"), "\n")
add_point_geom(con, "cufes", lon_col = "longitude", lat_col = "latitude")
assign_grid_key(con, "cufes") |> datatable(caption = "Grid assignment")
```
## Add Measurement Types
The six raw counts publish as `abundance` (units `count`), as before. The
concentration is its own type, `egg_concentration`, in eggs per m³ of water
pumped. Its bound is one-sided (`valid_min = 0`, a concentration is never
negative); there is no ceiling to declare without inventing one.
```{r}
#| label: meas-types
d_meas_type <- register_measurement_types(
  tibble(
    measurement_type = "egg_concentration",
    description      = paste(
      "Fish or squid eggs per cubic metre of water pumped by the Continuous Underway",
      "Fish Egg Sampler (CUFES): the sample's egg count standardized by its minutes",
      "sampled and its mean pump speed"),
    units            = "count/m3",
    valid_min        = 0,
    derivation       = paste0(
      "Ed Weber (SWFSC), 2026-09-25, swfsc_cufes questions Q01: \"The standardization is ",
      "usually: eggs / m^3 = (count / minutes sampled) / mean pump speed, i.e., eggs / m^3 = ",
      "(count / (stop time - start time) / ((start pump speed + stop pump speed) / 2)\". ",
      "Computed in ingest_swfsc_cufes.qmd from Cufes.csv: Stop - Start in minutes, the mean of ",
      "StartPumpSpeed and StopPumpSpeed (m3/min, Q02); only where the minutes and both pump ",
      "speeds are present and positive."),
    is_canonical     = TRUE,
    `_source_column` = paste(paste0(egg_cols, "_per_m3"), collapse = "; "),
    `_source_table`  = "cufes_measurement",
    `_source_datasets` = ds_key,
    grain            = "obs",
    denominator      = "volume",
    category         = "Fish Eggs & Larvae",
    units_nerc_p06   = "http://vocab.nerc.ac.uk/collection/P06/current/UPMM/"),
  meas_type_csv)
dbWriteTable(con, "measurement_type", as.data.frame(d_meas_type), overwrite = TRUE)
```
## Emit Core Tables
Project this dataset into the shared consolidated core model
(`design_env-bio-consolidation.md`). These core tables **are** this ingest's
output: `release_database.qmd` concatenates the per-dataset shards rather than
re-deriving the core, so there is exactly one projection to keep correct.
CUFES bakes the taxon into the measurement name (`sardine_eggs`,
`sardine_eggs_per_m3`, …). `metadata/measurement_taxon.csv` decomposes each raw
name into a real `taxon_key`, the canonical `measurement_type` (`abundance` or
`egg_concentration`) and `life_stage` (`egg`), so both land in `obs` as ordinary
taxon-resolved occurrences. The taxa are the export's own: each crosswalk row's
`worms_id`/`itis_id` is asserted equal to the `AphiaId`/`Tsn` that SWFSC's
`Species.csv` gives the same scientific name.
```{r}
#| label: emit_core
# filter the crosswalk to THIS dataset -- an unfiltered read leaks other datasets'
# taxa into this shard
mt_taxon <- read_csv(here("metadata/measurement_taxon.csv"),
                     col_types = cols(worms_id = "i", itis_id = "i",
                                      bin_value = "d", .default = "c")) |>
  filter(dataset_key == ds_key)
tx_over  <- read_csv(here("metadata/taxon_override.csv"), show_col_types = FALSE)

# the source's own ids: Species.csv of the same export (read-only)
d_species <- read_csv(path_expand(glue("{dir_data}/swfsc/ichthyo/Species.csv")),
                      col_types = cols(.default = "c")) |>
  transmute(taxon_scientific_name = Taxon,
            aphia_src = as.integer(AphiaId), tsn_src = as.integer(Tsn))
d_tx_chk <- mt_taxon |> distinct(taxon_scientific_name, worms_id, itis_id) |>
  left_join(d_species, by = "taxon_scientific_name")
d_tx_chk |> datatable(caption = "CUFES taxa: crosswalk ids versus SWFSC Species.csv")
stopifnot(
  "every CUFES taxon must be in SWFSC's Species.csv with the crosswalk's AphiaID and TSN" =
    all(d_tx_chk$worms_id == d_tx_chk$aphia_src & d_tx_chk$itis_id == d_tx_chk$tsn_src,
        na.rm = FALSE))

# cross-reference, lineage, then the references -- the order the taxon-reference
# skill sets (the composite-measurement path: no dataset_taxon staging)
ensure_taxon_xref(con, mt_taxon, tx_over,
                  cache_csv = here("metadata/taxon_xref.csv"))
ensure_taxon_lineage(con, mt_taxon, tx_over,
                     cache_csv = here("metadata/taxon_lineage.csv"))
n_taxon    <- build_taxon_reference(con, mt_taxon, tx_over)
n_ds_taxon <- resolve_dataset_taxon(con, mt_taxon, tx_over)
# stage the crosswalk WITH its derived taxon_key (never a 'worms:' || id string)
ensure_measurement_taxon(con, mt_taxon, dataset_key = ds_key)

# sample: one underway row per CUFES sample, keyed on SWFSC's CufesId, which also
# ships as source_uuid. site_key stays NULL: CUFES samples are "not constrained to
# have any relation with CalCOFI stations" (Ed Weber, Q04).
append_sample(con, glue("
  SELECT {ns_key(ds_key, 'underway', 'u.cufes_uuid')} AS sample_key, 'underway' AS sample_type,
         NULL::VARCHAR AS parent_sample_key,
         {ns_key(ds_key, 'underway', 'u.cufes_uuid')} AS root_sample_key,
         '{ds_key}' AS dataset_key,
         u.grid_key, NULL::VARCHAR AS site_key, u.cruise_key, NULL::INTEGER AS order_occ,
         u.latitude, u.longitude, CAST(u.datetime_start_utc AS TIMESTAMP) AS datetime,
         0::DOUBLE AS depth_min_m, 0::DOUBLE AS depth_max_m,
         NULL::VARCHAR AS tow_type,
         NULL::VARCHAR AS data_stage,
         u.cufes_uuid AS source_uuid
  FROM cufes u"))

append_obs(con, glue("
  SELECT 'bio', '{ds_key}', {ns_key(ds_key, 'underway', 'u.cufes_uuid')},
         u.grid_key, u.cruise_key, u.latitude, u.longitude,
         CAST(u.datetime_start_utc AS TIMESTAMP), 0::DOUBLE, 0::DOUBLE,
         mx.taxon_key, mx.life_stage, mx.measurement_type, m.measurement_value,
         m.measurement_qual, NULL::DOUBLE
  FROM cufes_measurement m JOIN cufes u USING (cufes_uuid)
  JOIN _measurement_taxon mx ON mx.dataset_key = '{ds_key}'
                            AND mx.raw_measurement_type = m.measurement_type
                            AND mx.target = 'obs'"))

core <- list(
  sample        = dbGetQuery(con, "SELECT COUNT(*) FROM sample")[[1]],
  obs           = dbGetQuery(con, "SELECT COUNT(*) FROM obs")[[1]],
  taxon         = n_taxon,
  dataset_taxon = n_ds_taxon)
cat(glue(
  "core projection — sample={core$sample %||% 0} obs={core$obs %||% 0} ",
  "taxon={core$taxon %||% 0} dataset_taxon={core$dataset_taxon %||% 0}\n"))
# every measurement whose raw type is registered must reach obs with a real
# taxon_key -- an unregistered raw type is dropped by the INNER join, so assert
# the registry covers the vocabulary in the data
n_obs <- dbGetQuery(con, "SELECT COUNT(*) FROM obs")[[1]]
n_unreg <- dbGetQuery(con, "
  SELECT COUNT(DISTINCT m.measurement_type) FROM cufes_measurement m
  WHERE m.measurement_type NOT IN (
    SELECT raw_measurement_type FROM _measurement_taxon WHERE target = 'obs')")[[1]]
stopifnot(
  "obs must be one row per measurement" = n_obs == nrow(d_meas),
  "every cufes measurement_type must be in measurement_taxon.csv" = n_unreg == 0,
  "cufes obs must all carry a taxon_key" =
    dbGetQuery(con, "SELECT COUNT(*) FROM obs WHERE taxon_key IS NULL")[[1]] == 0,
  "sample_key must be unique" =
    dbGetQuery(con, "SELECT COUNT(*) - COUNT(DISTINCT sample_key) FROM sample")[[1]] == 0,
  "every obs.sample_key must resolve in sample" =
    dbGetQuery(con, "SELECT COUNT(*) FROM obs o LEFT JOIN sample s USING (sample_key)
                     WHERE s.sample_key IS NULL")[[1]] == 0)
dbGetQuery(con, "
  SELECT measurement_type, COUNT(*) AS n_rows, COUNT(DISTINCT taxon_key) AS n_taxa,
         MIN(measurement_value) AS v_min, MAX(measurement_value) AS v_max
  FROM obs GROUP BY 1 ORDER BY 1") |>
  datatable(caption = "obs by measurement_type")
cat(glue("obs parity: {format(n_obs, big.mark = ',')} rows, all taxon-resolved"), "\n")
```
## Check Declared Bounds
Every emitted type must be declared: `abundance` and `egg_concentration` both carry
`valid_min = 0` (Q03 for the count, the registration above for the
concentration). A finding here stops the render.
```{r}
#| label: bounds-check
bounds <- check_measurement_bounds(con, "obs", mt = d_meas_type, dataset_key = ds_key)
bounds_datatable(bounds)
stopifnot(
  "every swfsc_cufes measurement type must be declared and in bounds" =
    all(bounds$status == "ok"))
```
```{r}
#| label: compat-view
# serve the source-shaped table name as a VIEW over the core, so in-notebook
# consumers and ad-hoc queries keep working against it
invisible(dbExecute(con, "DROP TABLE IF EXISTS cufes_measurement_src"))
invisible(dbExecute(con, "ALTER TABLE cufes_measurement RENAME TO cufes_measurement_src"))
invisible(dbExecute(con, glue(
  "CREATE OR REPLACE VIEW cufes_measurement AS
   {compat_measurement_sql(ds_key, 'underway', 'cufes_uuid', 'cufes_measurement_id')}")))
cat(glue("compat view cufes_measurement over obs: ",
         "{dbGetQuery(con, 'SELECT COUNT(*) FROM cufes_measurement')[[1]]} rows"), "\n")
```
## Validate, Write Outputs
```{r}
#| label: finalize
d_dataset <- ingest_yaml_to_dataset_df(read_ingest_yaml(here()))
dbWriteTable(con, "dataset", d_dataset, overwrite = TRUE)

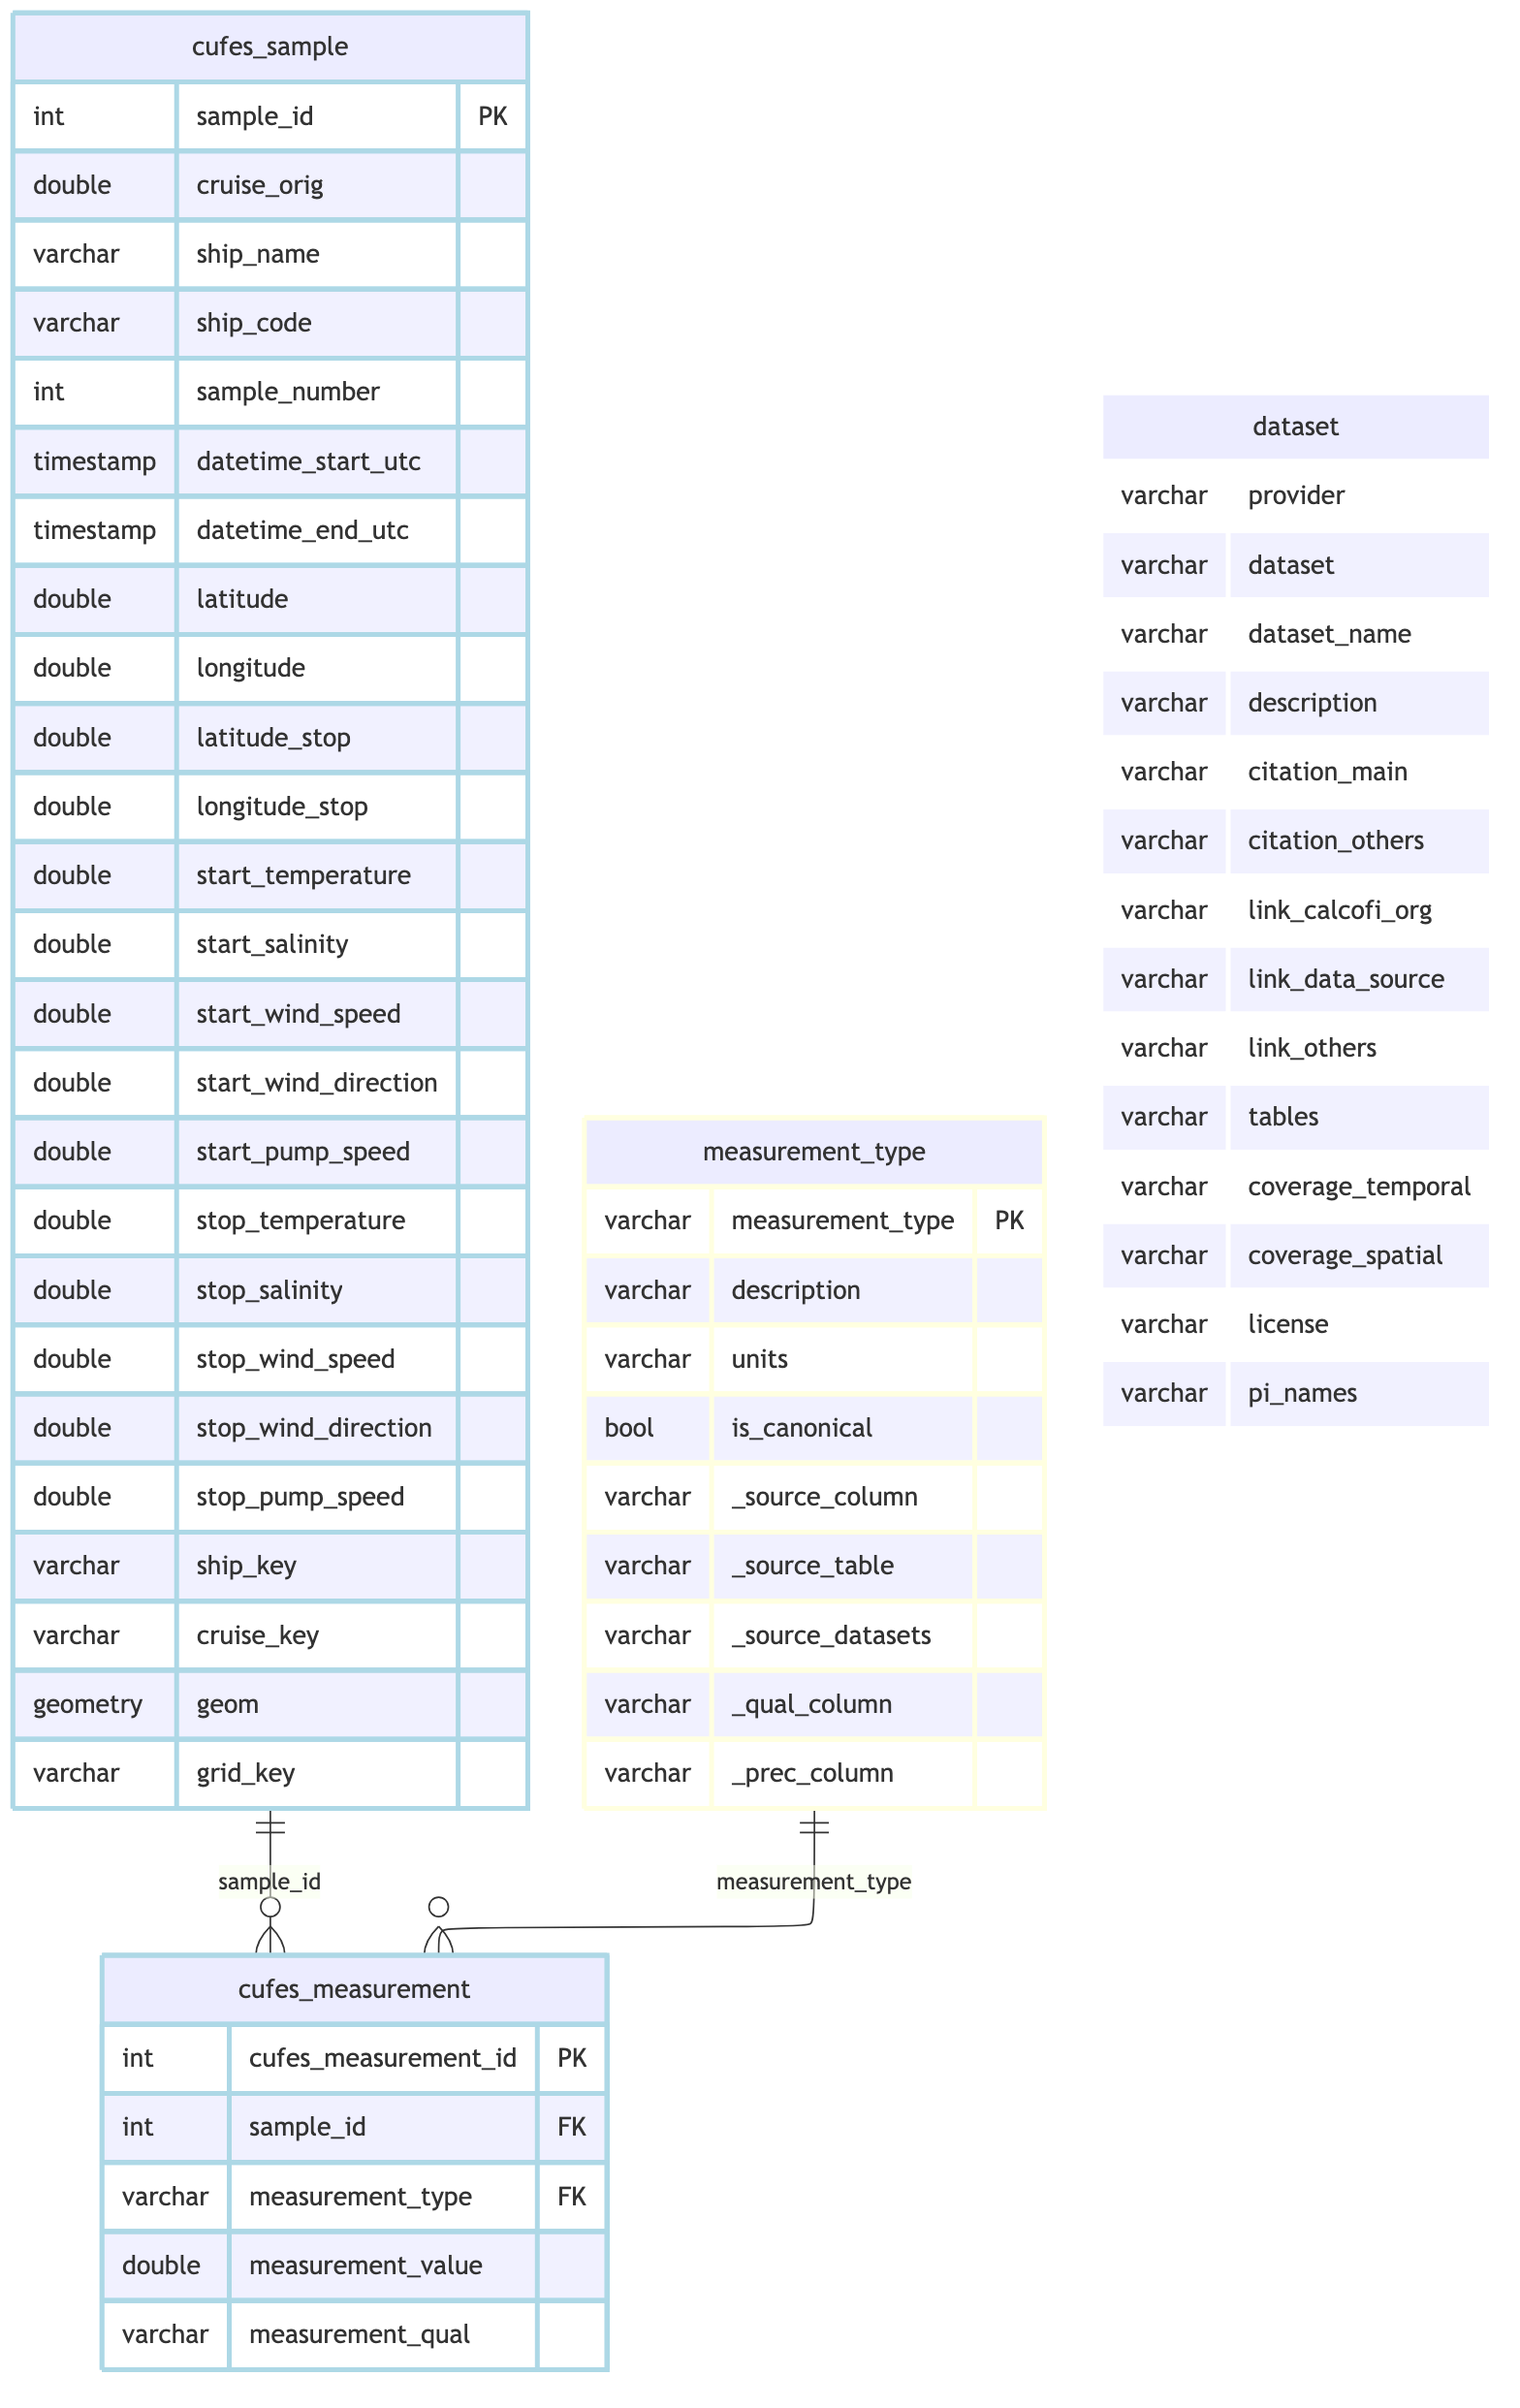
cufes_rels <- list(
  primary_keys = list(cufes = "cufes_uuid", cufes_measurement_src = "cufes_measurement_id",
                      measurement_type = "measurement_type"),
  foreign_keys = list(
    list(table = "cufes_measurement_src", column = "cufes_uuid", ref_table = "cufes", ref_column = "cufes_uuid"),
    list(table = "cufes_measurement_src", column = "measurement_type", ref_table = "measurement_type", ref_column = "measurement_type")))
# the SOURCE shape, documenting the wrangling above; the published tables are
# the consolidated core, so relationships.json comes from core_relationships()
cc_erd(con, tables = c("cufes", "cufes_measurement_src", "measurement_type", "dataset"), rels = cufes_rels,
       colors = list(lightblue = c("cufes", "cufes_measurement_src"), lightyellow = "measurement_type", white = "dataset"))
results <- validate_for_release(con, checks = "all", strict = FALSE)
cat("Validation:", ifelse(results$passed, "PASSED", "FAILED"), "\n")
# non-strict: NULLs that are expected here (site_key and parent_sample_key on an
# underway root sample, grid_key off the grid, taxon ids no source supplies)
if (length(results$errors) > 0)
  cat("Errors:\n", paste("-", results$errors, collapse = "\n"), "\n")
dir_create(dir_parquet)
mismatches <- list(cruise_keys = collect_cruise_key_mismatches(con, "cufes"))
tbls_out <- core_output_tables(con, extra = c("measurement_type", "dataset"))
write_parquet_outputs(con = con, output_dir = dir_parquet,
  tables = tbls_out,
  sort_by = list(obs = c("grid_key", "measurement_type")), strip_provenance = FALSE,
  mismatches = mismatches)
build_relationships_json(rels = core_relationships(tbls_out), output_dir = dir_parquet,
  provider = provider, dataset = dataset)
build_metadata_json(con = con, d_tbls_rd = d_tbls_rd, d_flds_rd = d_flds_rd,
  metadata_derived_csv = c(here("metadata/core_dictionary.csv"),
                           here("metadata/swfsc/cufes/metadata_derived.csv")),
  output_dir = dir_parquet, tables = tbls_out,
  set_comments = TRUE, provider = provider, dataset = dataset,
  workflow_url = cc$workflow_url, tables_owned = tables_owned)
if (publish_to_gcs) {
  sync_to_gcs(local_dir = dir_stage, sidecar_dir = dir_parquet, gcs_prefix = glue("ingest/{dir_label}"), bucket = "calcofi-db")
} else cat("CALCOFI_SKIP_GCS set — skipping the upload (local verification run)\n")
```
## Questions for Data Providers
```{r}
#| label: provider-questions
# one validated read + render for every ingest: the vocabulary and the column
# order live in calcofi4db, not in 16 hand-written factor() calls
questions_datatable(
  here(cc$questions_file),
  caption = "Questions for the SWFSC CUFES data providers (ranked)")
```
```{r}
#| label: cleanup
close_duckdb(con); cat(glue("Parquet outputs written to: {dir_parquet}"), "\n")
```