---
title: "Ingest DIC"
calcofi:
target_name: ingest_calcofi_dic
workflow_type: ingest
dependency:
- ingest_calcofi_bottle
output: data/parquet/calcofi_dic/manifest.json
provider: calcofi
dataset: dic
workflow_url: https://calcofi.io/workflows/ingest_calcofi_dic.html
questions_file: metadata/calcofi/dic/questions.csv
dataset_meta:
dataset_name: CalCOFI DIC
# display trio, read by the release `dataset` table and the
# consumer apps (calcofi4db >= 3.15.0) — see NEWS for why these
# left the apps' own hardcoded maps
dataset_name_short: Carbonate Chemistry / DIC
category: Carbonate System
color: "#cf2407"
# publishes the consolidated core. DIC rows that share a physical Niskin with
# calcofi_bottle reuse that bottle's sample_key, so the two do not double-count.
tables_owned:
- {table: sample, shared: true, note: "core event dimension (bottle grain; non-shared Niskins only)"}
- {table: obs, shared: true, note: "core observations (env, DIC + alkalinity)"}
- {table: measurement_type, shared: true, note: "shared registry across bottle/ctd/dic"}
erd:
color: "#ffd2bb"
editor_options:
chunk_output_type: console
---
## Overview
**Source**: [DIC | CalCOFI.org](https://calcofi.org/data/oceanographic-data/dic/)
Dissolved Inorganic Carbon (DIC) and Total Alkalinity (TA) from CalCOFI
Niskin bottle samples, archived at NCEI accession
[0301029](https://www.ncei.noaa.gov/access/metadata/landing-page/bin/iso?id=gov.noaa.nodc:0301029).
- **Provider**: `calcofi` (CalCOFI program; PI: Todd Martz, Scripps)
- **File**: `CALCOFI_DIC_20250122.csv` (~500KB, 4,391 rows)
- **Coverage**: 1983–2021, 71 stations, 131 cruises
- **Measurements**: DIC (umol/kg), TA (umol/kg), CTD temperature (degC),
salinity (PSS-78)
- **Quality flags**: WOCE convention (2=good, 3=questionable, 4=bad, 9=missing)
- **Citation**: Keeling, C.D. et al. (2025). Discrete profile dissolved
inorganic carbon, total alkalinity, water temperature and salinity
measurements ... for the CalCOFI program in the North East Pacific
Ocean Coastal area from 1983-03-19 to 2021-07-20 (NCEI Accession
0301029). NOAA NCEI. <https://doi.org/10.25921/3w9f-jd72>
**Strategy**: Load source CSV, pivot ALL four measurement columns
(DIC, TA, CTD temperature, salinity) into tidy long-format
`dic_measurement`, then summarize replicates into
`dic_summary`. The base `dic_sample` table retains only
position/time/FK columns — no measurement values.
**Published scope.** A DIC value on a Niskin the bottle database also carries is published
once, on that bottle. A value on a sample that matches **no** bottle cast is published on
the sample's own key wherever the source gives a depth (the source's `Depth` is metres,
`-999` is its missing sentinel); these values are **not linked to a bottle cast**. The one
unmatched sample with no depth stays a `sample` row with no observations. See
[Scope of the published values](#scope-of-the-published-values) and questions
`calcofi_dic_01` / `calcofi_dic_07`.
### Data Flow
```{mermaid}
graph LR
  A[NCEI CSV] --> B[DuckDB Wrangling]
  B --> C[Parse Station + Date]
  C --> D[Match to Casts]
  D --> E[Pivot ALL → long]
  E --> F[Summarize Replicates]
  F --> G[Parquet Export]
  G --> H[GCS Archive]
```
### Measurement Types
Four measurement types from this dataset — all **new** types, distinct
from bottle/CTD equivalents because these come from a separate
instrument chain with WOCE QC:
| measurement_type | description | units | source column | status |
|-----------------|-------------|-------|---------------|--------|
| `dic` | Dissolved inorganic carbon | umol/kg | DIC | **NEW** |
| `alkalinity` | Total alkalinity | umol/kg | TA | **NEW** |
| `ctdtemp_its90` | CTD temperature (ITS-90) | degC | CTDTEMP_ITS90 | **NEW** |
| `salinity_pss78` | Practical salinity (PSS-78) | PSS-78 | Salinity_PSS78 | **NEW** |
These are kept separate from the calcofi_bottle `temperature`/`salinity`
types because the DIC dataset values come from a different QC pipeline
(WOCE flags vs calcofi.org quality codes).
## Setup
```{r}
#| label: setup
# devtools::install_local(here::here("../calcofi4db"), force = T)
devtools::load_all(here::here("../calcofi4db"))
devtools::load_all(here::here("../calcofi4r"))

librarian::shelf(
  CalCOFI / calcofi4db,
  CalCOFI / calcofi4r,
  DBI,
  dplyr,
  DT,
  fs,
  glue,
  googledrive,
  here,
  htmltools,
  janitor,
  jsonlite,
  knitr,
  lubridate,
  purrr,
  readr,
  sf,
  stringr,
  tibble,
  tidyr,
  units,
  quiet = T
)
options(readr.show_col_types = F)
options(DT.options = list(scrollX = TRUE))

# common ingest settings (overwrite, dir_data)
source(here("libs/ingest.R"))

# define paths
# provider/dataset/metadata read from this file's authoritative YAML block
cc           <- read_calcofi_meta(here("ingest_calcofi_dic.qmd"))
provider     <- cc$provider
dataset      <- cc$dataset
dataset_name <- cc$dataset_meta$dataset_name
tables_owned <- cc$tables_owned
dir_label    <- glue("{provider}_{dataset}")

dir_parquet <- here(glue("data/parquet/{dir_label}"))
dir_stage <- cc_stage_path("parquet", dir_label, create = TRUE)
db_path     <- here(glue("data/wrangling/{dir_label}.duckdb"))

# clean slate if overwrite (keep dir_parquet for content-hash dedup)
if (overwrite) {
  if (file_exists(db_path))    file_delete(db_path)
  # clear stale WAL/tmp from an interrupted run
  if (file_exists(paste0(db_path, ".wal"))) file_delete(paste0(db_path, ".wal"))
  if (dir_exists(paste0(db_path, ".tmp")))  dir_delete(paste0(db_path, ".tmp"))
}

dir_create(dirname(db_path))
con <- get_duckdb_con(db_path)
load_duckdb_extension(con, "spatial")

# archive source files to GCS
dir_src <- path_expand(glue("{dir_data}/{provider}/{dataset}"))
sync_to_gcs(
  local_dir  = dir_src,
  gcs_prefix = glue("archive/{provider}/{dataset}"),
  bucket     = "calcofi-files-public",
  exclude    = c(".DS_Store", "*.tmp"))
# load unified measurement_type reference
meas_type_csv <- here("metadata/measurement_type.csv")
d_meas_type   <- read_measurement_type(meas_type_csv)
```
## Read Source Data
The NCEI CSV has a units row (row 2) that must be skipped, and uses
`-999` as the missing value sentinel.
```{r}
#| label: read-source
dic_csv <- glue(
  "{dir_data}/calcofi/dic/0301029/1.1/data/0-data/",
  "CALCOFI_DIC_20250122.csv"
)
stopifnot("DIC CSV not found" = file_exists(dic_csv))

# read, skipping the units row (row 2)
d_raw <- read_csv(dic_csv, skip = 2, col_names = FALSE)

# get header from row 1
hdr <- read_csv(dic_csv, n_max = 0) |> names()
names(d_raw) <- hdr

cat(glue("Read {nrow(d_raw)} rows, {ncol(d_raw)} columns from {basename(dic_csv)}"), "\n")
```
## Clean and Type-Cast
Replace `-999` with NA, convert character columns to proper types, and
build a datetime column.
```{r}
#| label: clean-data
d_clean <- d_raw |>
  mutate(
    # convert numeric columns stored as character (due to units row)
    Latitude      = as.numeric(Latitude),
    Longitude     = as.numeric(Longitude),
    Depth         = as.numeric(Depth),
    CTDTEMP_ITS90 = as.numeric(CTDTEMP_ITS90),
    DIC           = as.numeric(DIC),
    TA            = as.numeric(TA),

    # replace -999 sentinels with NA across all numeric columns
    across(
      where(is.numeric),
      ~ if_else(.x == -999, NA_real_, .x)),

    # build datetime from components
    datetime_start_utc = make_datetime(
      Year_UTC, Month_UTC, Day_UTC,
      tz = "UTC"),

    # site_key matching calcofi convention: "090.0 062.0"
    site_key = Station_ID
  )

# summary of NA replacement
na_counts <- d_clean |>
  summarise(across(where(is.numeric), ~ sum(is.na(.x)))) |>
  pivot_longer(everything(), names_to = "column", values_to = "n_na") |>
  filter(n_na > 0)
na_counts |> datatable(caption = "NULL counts after -999 replacement")
```
## Load into Database
Load `dic_sample` as a **tidy position table** — only station, time,
depth, and FK columns. Measurement values (DIC, TA, temp, salinity) are
pivoted into `dic_measurement` in the next step.
```{r}
#| label: load-to-db
# tidy: dic_sample has position/time only, no measurement values
d_dic <- d_clean |>
  transmute(
    expocode     = EXPOCODE,
    ship_name    = Ship_Name,
    datetime_start_utc = datetime_start_utc,
    site_key      = site_key,
    latitude     = Latitude,
    longitude    = Longitude,
    depth_m      = Depth
  )

dbWriteTable(con, "dic_sample", d_dic, overwrite = TRUE)
cat(glue("dic_sample: {nrow(d_dic)} rows, {ncol(d_dic)} columns loaded"), "\n")
# also load the wide-format data temporarily for pivoting
d_wide <- d_clean |>
  transmute(
    expocode     = EXPOCODE,
    site_key      = Station_ID,
    datetime_start_utc = datetime_start_utc,
    depth_m      = Depth,
    latitude     = Latitude,
    longitude    = Longitude,
    ctdtemp_its90     = CTDTEMP_ITS90,
    ctdtemp_its90_flag = as.integer(CTDTEMP_flag),
    salinity_pss78     = Salinity_PSS78,
    salinity_pss78_flag = as.integer(Salinity_flag),
    dic           = DIC,
    dic_flag      = as.integer(DIC_flag),
    alkalinity    = TA,
    alkalinity_flag = as.integer(TA_flag)
  )
dbWriteTable(con, "dic_wide", d_wide, overwrite = TRUE)
```
## Match to Existing Casts
Load existing casts from bottle workflow parquet and match DIC samples
to casts using `site_key` + `datetime_start_utc` (±3 day window).
```{r}
#| label: load-casts
# `calcofi_bottle` publishes the consolidated core now, not `casts`/`bottle`, so
# load its `sample` shard and rebuild the two event tables as VIEWs over it. The
# shard is loaded under a distinct name: dic builds its OWN `sample` in the
# "Emit Core Tables" section below, and these views must keep resolving after
# that happens — hence `_bottle_sample`, not `sample`.
load_prior_tables(
  con         = con,
  tables      = c("sample"),
  parquet_dir = cc_stage_path("parquet", "calcofi_bottle"),
  geom_tables = c("sample"),
  as_view     = TRUE
)
dbExecute(con, "ALTER VIEW sample RENAME TO _bottle_sample")
# rebuild `casts` + `bottle` from bottle's core shard: the source id comes back
# out of the namespaced sample_key ('<dataset_key>:<sample_type>:<id>' -> field 3)
# and the cast FK out of parent_sample_key. Matching below joins on these, so
# they must come back from the core rather than from a retired parquet table.
dbExecute(con, "
  CREATE OR REPLACE VIEW casts AS
  SELECT CAST(split_part(s.sample_key, ':', 3) AS BIGINT) AS cast_id,
         s.site_key, s.grid_key, s.cruise_key, s.order_occ,
         s.latitude, s.longitude, s.datetime AS datetime_start_utc, s.geom
  FROM _bottle_sample s
  WHERE s.dataset_key = 'calcofi_bottle' AND s.sample_type = 'cast'")
dbExecute(con, "
  CREATE OR REPLACE VIEW bottle AS
  SELECT CAST(split_part(s.sample_key, ':', 3) AS BIGINT) AS bottle_id,
         CAST(split_part(s.parent_sample_key, ':', 3) AS BIGINT) AS cast_id,
         s.site_key, s.depth_min_m AS depth_m
  FROM _bottle_sample s
  WHERE s.dataset_key = 'calcofi_bottle' AND s.sample_type = 'bottle'")
n_casts  <- dbGetQuery(con, "SELECT COUNT(*) FROM casts")[[1]]
n_bottle <- dbGetQuery(con, "SELECT COUNT(*) FROM bottle")[[1]]
stopifnot(
  "bottle's core shard must yield cast rows"   = n_casts  > 0,
  "bottle's core shard must yield bottle rows" = n_bottle > 0)
cat(glue("bottle event tables rebuilt from core: casts ",
         "{format(n_casts, big.mark = ',')}, bottle {format(n_bottle, big.mark = ',')}"), "\n")
# station matching
n_dic_sta <- dbGetQuery(
  con, "SELECT COUNT(DISTINCT site_key) FROM dic_sample")[[1]]
n_matched_sta <- dbGetQuery(
  con,
  "SELECT COUNT(DISTINCT d.site_key)
   FROM dic_sample d
   INNER JOIN casts c ON d.site_key = c.site_key")[[1]]
cat(glue(
  "Station matching: {n_matched_sta}/{n_dic_sta} DIC stations found in casts"), "\n")
```
```{r}
#| label: match-casts
# match DIC samples to casts by site_key + datetime (±3 day window) via the
# shared calcofi4db helper (resolves issue #47). many dates are offset by 1 day
# between NCEI and calcofi.org, hence the window.
m_cast <- match_by_site_datetime(
  con, data_tbl = "dic_sample", ref_tbl = "casts",
  fk_col = "cast_id", ref_pk = "cast_id",
  key_col = "site_key", datetime_col = "datetime_start_utc", window_days = 3)

cat(glue(
  "Cast matching: {m_cast$matched}/{m_cast$total} DIC samples matched ",
  "({m_cast$pct}%)"), "\n")
# show unmatched samples
if (nrow(m_cast$unmatched) > 0)
  m_cast$unmatched |> datatable(caption = "Unmatched DIC samples (no matching cast)")
```
## Match to Bottles
For matched casts, find the nearest bottle at the same depth.
```{r}
#| label: match-bottles
# for cast-matched samples, find the nearest bottle by depth via the shared
# calcofi4db helper (scoped to the already-matched cast_id).
m_btl <- match_nearest_by_depth(
  con, data_tbl = "dic_sample", ref_tbl = "bottle",
  fk_col = "bottle_id", ref_pk = "bottle_id",
  parent_fk = "cast_id", axis_col = "depth_m", tolerance = 1.0)

cat(glue(
  "Bottle matching: {m_btl$matched}/{m_btl$eligible} cast-matched samples ",
  "({m_btl$pct}%)"), "\n")
# propagate FKs to dic_wide for pivoting
dbExecute(con, "ALTER TABLE dic_wide ADD COLUMN IF NOT EXISTS cast_id INTEGER")
dbExecute(con, "ALTER TABLE dic_wide ADD COLUMN IF NOT EXISTS bottle_id INTEGER")
dbExecute(
  con,
  "UPDATE dic_wide w SET
     cast_id   = s.cast_id,
     bottle_id = s.bottle_id
   FROM dic_sample s
   WHERE w.expocode     = s.expocode
     AND w.site_key      = s.site_key
     AND w.datetime_start_utc = s.datetime_start_utc
     AND w.depth_m IS NOT DISTINCT FROM s.depth_m"
)
```
## Pivot ALL Measurements to Long Format
Pivot all four measurement columns (DIC, TA, CTD temperature, salinity)
into tidy long-format `dic_measurement`. Each row = one measurement at
one position. This follows tidy data principles — no mixing of different
measured quantities on the same row.
```{r}
#| label: pivot-measurements
# pivot all 4 measurement types from wide to long
meas_map <- list(
  list(type = "dic",             col = "dic",             flag = "dic_flag"),
  list(type = "alkalinity",      col = "alkalinity",      flag = "alkalinity_flag"),
  list(type = "ctdtemp_its90",   col = "ctdtemp_its90",   flag = "ctdtemp_its90_flag"),
  list(type = "salinity_pss78",  col = "salinity_pss78",  flag = "salinity_pss78_flag")
)

sql_parts <- map_chr(meas_map, \(m) glue(
  "SELECT expocode, site_key, datetime_start_utc, depth_m,
          latitude, longitude, cast_id, bottle_id,
          '{m$type}' AS measurement_type,
          CAST({m$col} AS DOUBLE) AS measurement_value,
          CAST({m$flag} AS VARCHAR) AS measurement_qual
   FROM dic_wide
   WHERE {m$col} IS NOT NULL
     AND NOT isnan(CAST({m$col} AS DOUBLE))
     AND isfinite(CAST({m$col} AS DOUBLE))"
))

dbExecute(con, glue(
  "CREATE OR REPLACE TABLE dic_measurement AS
   SELECT ROW_NUMBER() OVER (
     ORDER BY site_key, datetime_start_utc, depth_m, measurement_type
   ) AS dic_measurement_id, *
   FROM ({paste(sql_parts, collapse = '\nUNION ALL\n')}) sub"
))
# drop the temporary wide table
dbExecute(con, "DROP TABLE dic_wide")
n_meas <- dbGetQuery(con, "SELECT COUNT(*) FROM dic_measurement")[[1]]
cat(glue("dic_measurement: {format(n_meas, big.mark = ',')} rows"), "\n")
# summary by type
dbGetQuery(
  con,
  "SELECT measurement_type, COUNT(*) AS n,
          ROUND(AVG(measurement_value), 1) AS mean_val,
          ROUND(MIN(measurement_value), 1) AS min_val,
          ROUND(MAX(measurement_value), 1) AS max_val
   FROM dic_measurement
   GROUP BY measurement_type
   ORDER BY measurement_type"
) |> datatable(caption = "Measurement summary by type")
```
## Summarize Replicate Measurements
Aggregate replicate measurements at each unique position in time
and space (station + date + depth) into mean and standard deviation,
following `ctd_summary` in `ingest_calcofi_ctd-cast.qmd`. Filters out
`NaN`, `-Inf`, `Inf` values.
```{r}
#| label: dic-measurement-summary
dbExecute(
  con,
  "CREATE OR REPLACE TABLE dic_summary AS
   SELECT
     site_key,
     datetime_start_utc,
     depth_m,
     latitude,
     longitude,
     measurement_type,
     AVG(measurement_value)    AS avg,
     CASE
       WHEN COUNT(*) = 1 THEN 0
       ELSE COALESCE(STDDEV_SAMP(measurement_value), 0)
     END                       AS stddev,
     COUNT(*)                  AS n_obs,
     MAX(cast_id)              AS cast_id,
     MAX(bottle_id)            AS bottle_id
   FROM dic_measurement
   WHERE NOT isnan(measurement_value)
     AND isfinite(measurement_value)
   GROUP BY site_key, datetime_start_utc, depth_m,
            latitude, longitude, measurement_type"
)
n_summ <- dbGetQuery(con, "SELECT COUNT(*) FROM dic_summary")[[1]]
cat(glue(
  "dic_summary: {format(n_summ, big.mark = ',')} rows ",
  "(from {format(n_meas, big.mark = ',')} measurements)"), "\n")
dbGetQuery(
  con,
  "SELECT measurement_type,
          COUNT(*) AS n_positions,
          SUM(n_obs) AS n_raw_obs,
          ROUND(AVG(n_obs), 1) AS avg_replicates,
          SUM(CASE WHEN n_obs > 1 THEN 1 ELSE 0 END) AS n_with_replicates,
          ROUND(AVG(stddev), 3) AS avg_stddev
   FROM dic_summary
   GROUP BY measurement_type
   ORDER BY measurement_type"
) |> datatable(caption = "Replicate statistics by type")
```
## Load Dataset Metadata
```{r}
#| label: load-dataset-metadata
# dataset registry built from authoritative ingest_*.qmd YAML (was dataset.csv)
d_dataset <- ingest_yaml_to_dataset_df(read_ingest_yaml(here()))
dbWriteTable(con, "dataset", d_dataset, overwrite = TRUE)
cat(glue("dataset: {nrow(d_dataset)} datasets registered"), "\n")
```
## Add Measurement Types
Register the 4 measurement types from this dataset. All are **new** —
distinct from bottle/CTD types due to different QC pipelines.
```{r}
#| label: add-measurement-types
dic_types <- tibble(
  measurement_type   = c("dic",        "alkalinity",  "ctdtemp_its90",           "salinity_pss78"),
  description        = c("Dissolved inorganic carbon",
                          "Total alkalinity",
                          "CTD temperature (ITS-90 scale)",
                          "Practical salinity (PSS-78)"),
  units              = c("umol/kg",    "umol/kg",     "degC",                    "PSS-78"),
  `_source_column`   = c("DIC",        "TA",          "CTDTEMP_ITS90",           "Salinity_PSS78"),
  `_source_table`    = c("dic_measurement", "dic_measurement", "dic_measurement", "dic_measurement"),
  `_source_datasets` = c("calcofi_dic", "calcofi_dic", "calcofi_dic",            "calcofi_dic"),
  `_qual_column`     = c("dic_flag",   "ta_flag",     "ctdtemp_its90_flag",      "salinity_pss78_flag"),
  `_prec_column`     = c(NA_character_, NA_character_, NA_character_,             NA_character_)
)

existing <- d_meas_type |>
  filter(measurement_type %in% dic_types$measurement_type) |>
  pull(measurement_type)
new_types <- dic_types |> filter(!measurement_type %in% existing)

if (nrow(new_types) > 0) {
  cat(glue("Adding {nrow(new_types)} new measurement types: ",
           "{paste(new_types$measurement_type, collapse = ', ')}"), "\n")
  d_meas_type <- bind_rows(d_meas_type, new_types)
  write_csv(d_meas_type, meas_type_csv, na = "")
} else {
  cat("All measurement types already registered\n")
}
dbWriteTable(con, "measurement_type", d_meas_type, overwrite = TRUE)
```
## Verify Primary Keys
```{r}
#| label: verify-pks
# dic_sample composite key
n_dup_sample <- dbGetQuery(
  con,
  "SELECT COUNT(*) FROM (
     SELECT expocode, site_key, depth_m, datetime_start_utc, COUNT(*) AS n
     FROM dic_sample
     GROUP BY expocode, site_key, depth_m, datetime_start_utc
     HAVING COUNT(*) > 1)")[[1]]
cat(glue("dic_sample composite key duplicates: {n_dup_sample}"), "\n")
# dic_summary composite key
n_dup_summ <- dbGetQuery(
  con,
  "SELECT COUNT(*) FROM (
     SELECT site_key, datetime_start_utc, depth_m, measurement_type, COUNT(*) AS n
     FROM dic_summary
     GROUP BY site_key, datetime_start_utc, depth_m, measurement_type
     HAVING COUNT(*) > 1)")[[1]]
cat(glue("dic_summary composite key duplicates: {n_dup_summ}"), "\n")
```
## Schema Documentation
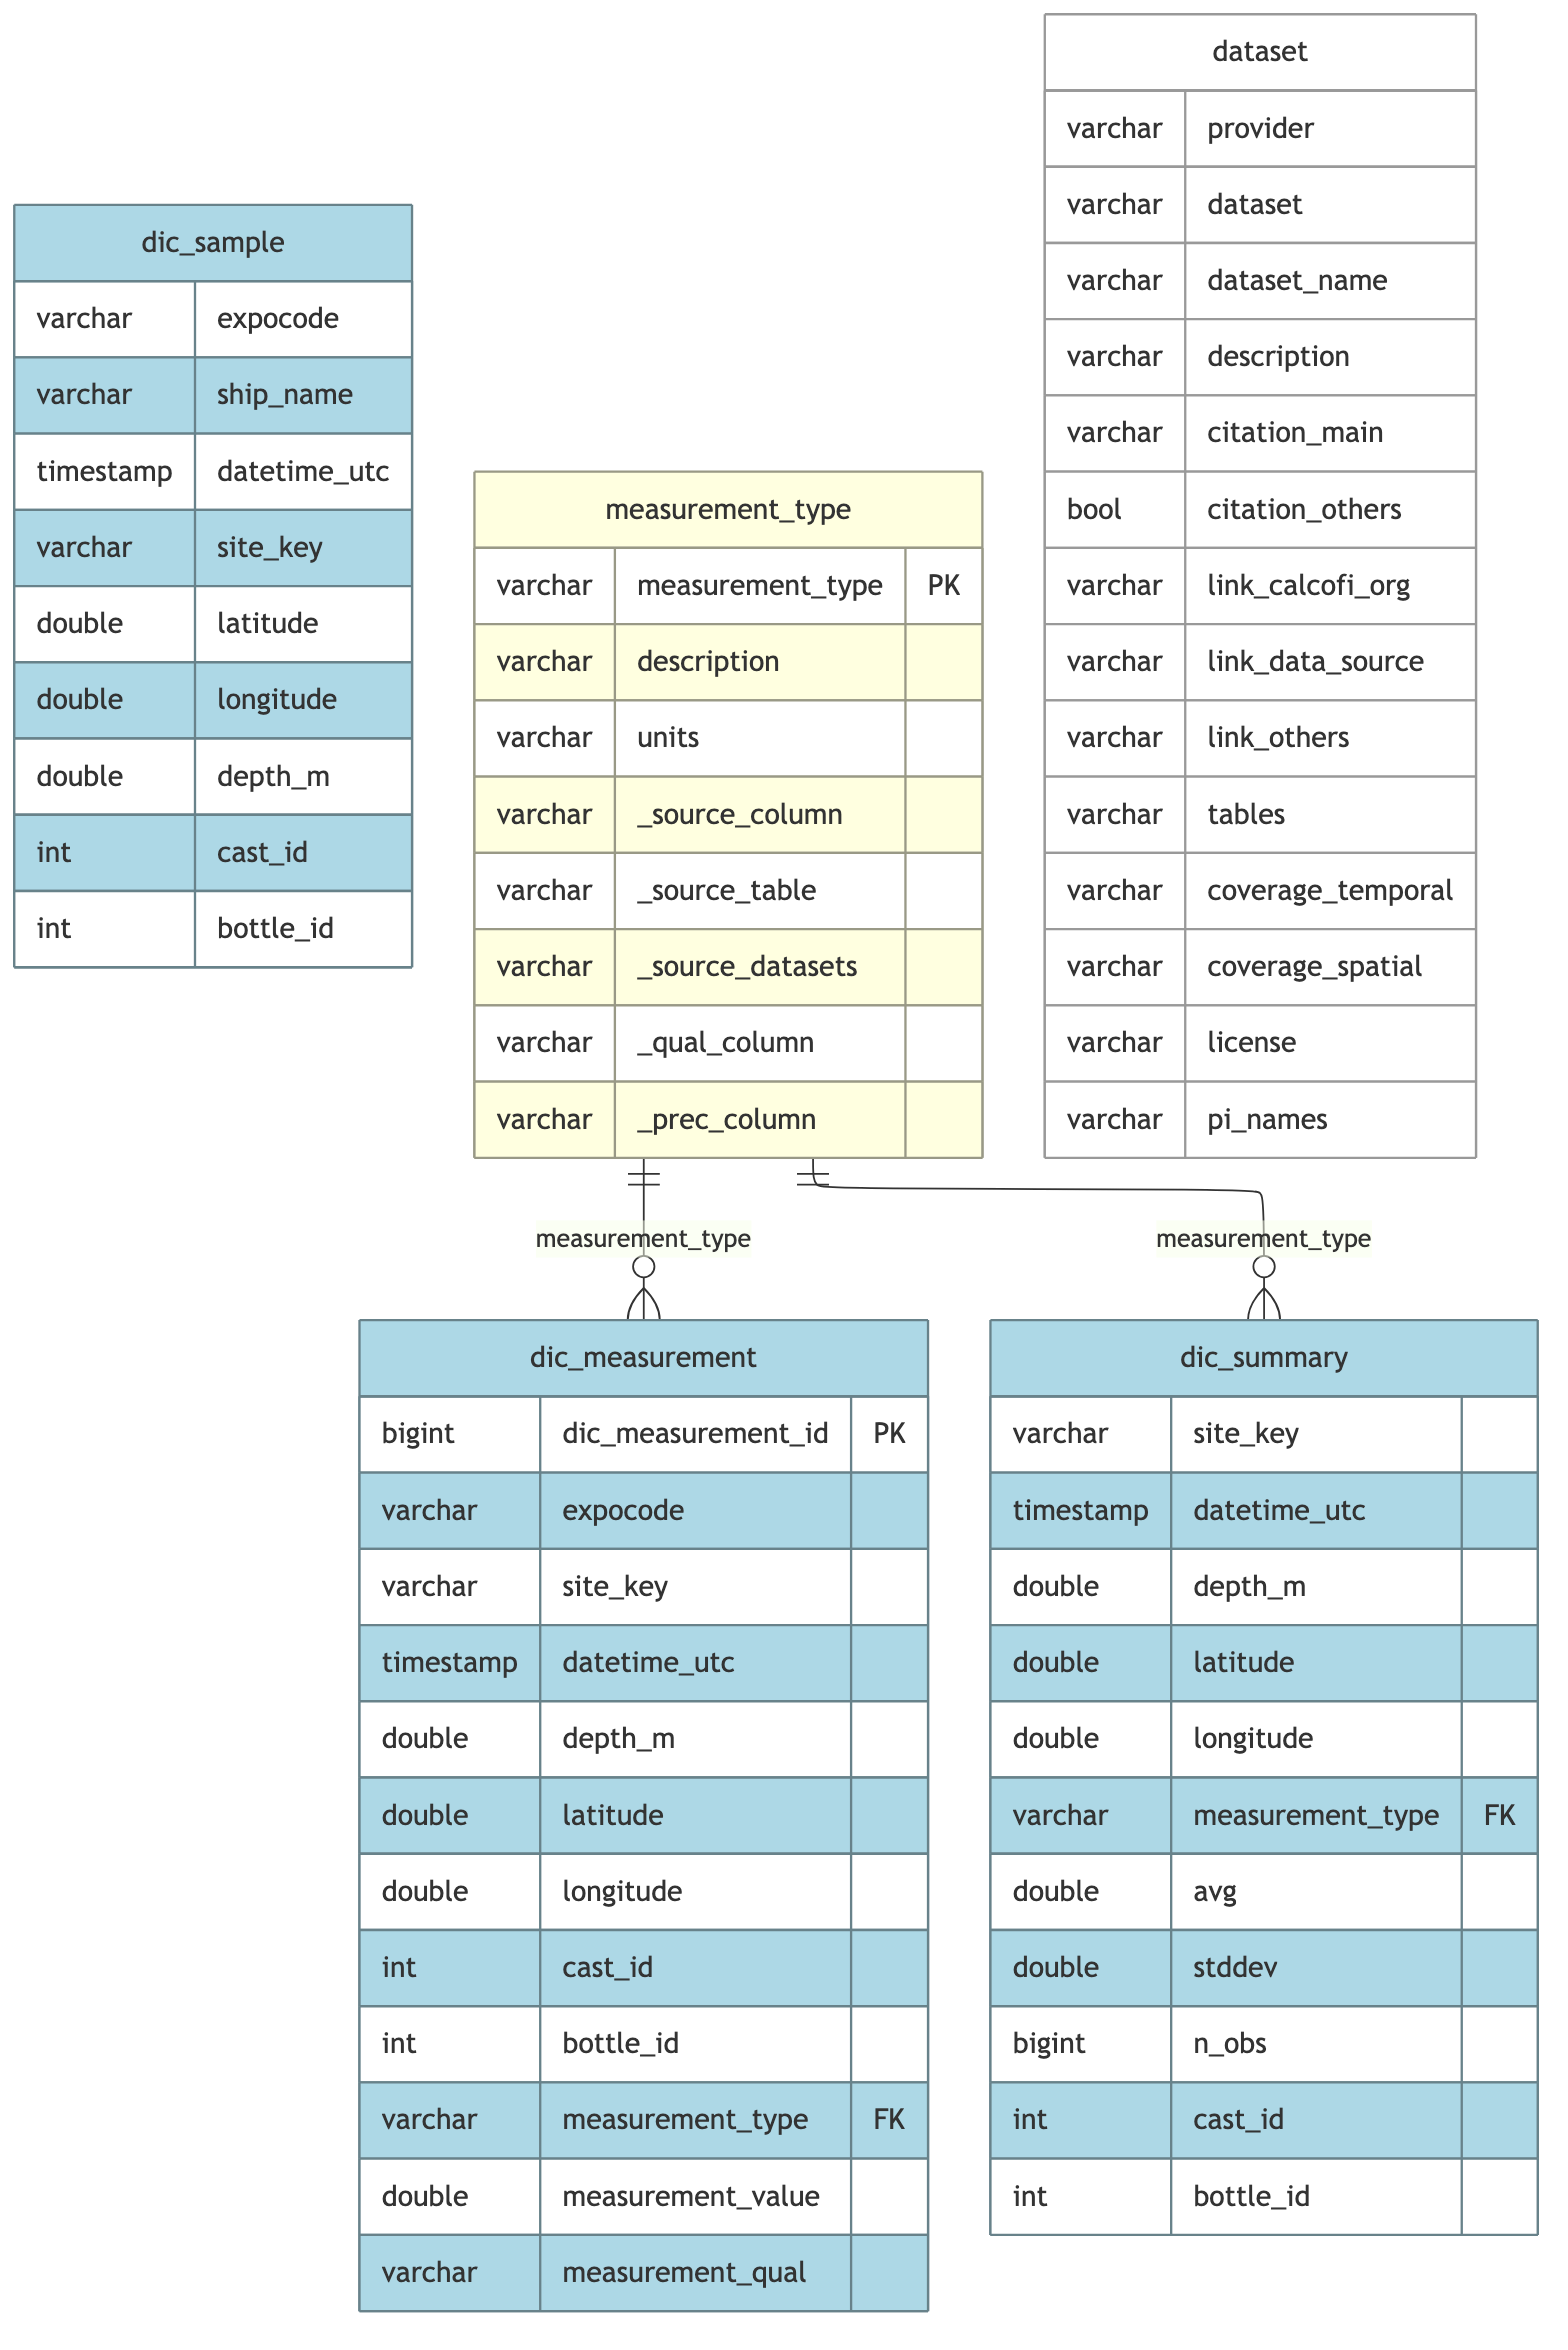
### Primary Keys and Foreign Key Relationships
```
dic_sample (position/time)
  ↓ (site_key + datetime_start_utc + depth_m)
dic_measurement (one row per measurement)
  dic_measurement.measurement_type (FK) → measurement_type.measurement_type
  ↓ (site_key + datetime_start_utc + depth_m + measurement_type)
dic_summary (avg/stddev per position)
  dic_summary.measurement_type (FK) → measurement_type.measurement_type
```
```{r}
#| label: schema
# define PK/FK relationships for visualization and relationships.json
dic_rels <- list(
  primary_keys = list(
    dic_measurement  = "dic_measurement_id",
    measurement_type = "measurement_type"),
  foreign_keys = list(
    list(table = "dic_measurement",         column = "measurement_type", ref_table = "measurement_type", ref_column = "measurement_type"),
    list(table = "dic_summary", column = "measurement_type", ref_table = "measurement_type", ref_column = "measurement_type")))

dic_tables <- c(
  "dic_sample", "dic_measurement", "dic_summary",
  "measurement_type", "dataset")
cc_erd(
  con,
  tables = dic_tables,
  rels   = dic_rels,
  colors = list(
    lightblue   = c("dic_sample", "dic_measurement", "dic_summary"),
    lightyellow = "measurement_type",
    white       = "dataset"))
```
## Add Spatial
Three things are derived from the source's own ship, date and position, **before** the
geometry column exists (a table holding a CRS-tagged `geom` cannot be `UPDATE`d):
1. **`ship_key`** — the EXPOCODE's NODC prefix against `ship.ship_nodc`, else the source's
own `Ship_Name` against `ship.ship_name` (NOAA's and SWFSC's NODC codes differ for six
ships: EXPOCODE `33RL` is SWFSC `33UD`, Reuben Lasker). A ship the reference does not
carry (Westwind) stays NULL.
2. **`cruise_key`** — `resolve_cruise_key()`: span containment on the sample's date first, then
the event's month, keys the reference `cruise` table does not hold left NULL
(`require_in_cruise`). The EXPOCODE's own start month is **not** passed as a designation:
`calcofi_dic_07` is open, and the EXPOCODE's start month differs from the span-resolved
cruise's month in 545 of the 1,971 rows the span alone resolves (a cruise starting
28 Jan is designated February).
3. **`grid_key`** — from the sample's own position (`assign_grid_key()`).
```{r}
#| label: spatial
load_prior_tables(
  con,
  parquet_dir = cc_stage_path("parquet", "swfsc_ichthyo"),
  tables      = c("ship", "cruise", "grid"),
  geom_tables = "grid",
  as_view     = TRUE)
# ship_key (WS-1004X2): NODC prefix first, then the source's Ship_Name
dbExecute(con, "ALTER TABLE dic_sample ADD COLUMN IF NOT EXISTS ship_key VARCHAR")
dbExecute(con, "ALTER TABLE dic_sample ADD COLUMN IF NOT EXISTS ship_key_method VARCHAR")
dbExecute(con, "
  UPDATE dic_sample d SET ship_key = s.ship_key, ship_key_method = 'nodc'
  FROM ship s WHERE s.ship_nodc = left(d.expocode, 4)")
ship_name_sql <- function(x)
  glue("regexp_replace(regexp_replace(upper(trim({x})), '^RV ', ''), '[.]', '', 'g')")
dbExecute(con, glue("
  UPDATE dic_sample d SET ship_key = s.ship_key, ship_key_method = 'name'
  FROM ship s WHERE d.ship_key IS NULL
    AND {ship_name_sql('s.ship_name')} = {ship_name_sql('d.ship_name')}"))
dbGetQuery(con, "
  SELECT COALESCE(ship_key_method, 'none') AS ship_key_method,
         COUNT(*) AS n_rows, COUNT(DISTINCT expocode) AS n_expocodes
  FROM dic_sample GROUP BY 1 ORDER BY 1") |>
  datatable(caption = "ship_key resolution (EXPOCODE NODC, then Ship_Name)")
# cruise_key: span containment, then month; never a key the reference does not hold
resolve_cruise_key(con, "dic_sample", datetime_col = "datetime_start_utc",
                   require_in_cruise = TRUE) |>
  datatable(caption = "cruise_key resolution method (DIC rows)")
# grid_key from the sample's OWN position (WS-1004X). Until v2026.10.01 the sample
# arm below took grid_key only from the matched bottle cast (`c.grid_key`), so the
# 3,255 DIC samples that match no cast (3,261 minted samples; every one carries a
# latitude, a longitude and a datetime) all shipped with grid_key NULL. The grid is
# the swfsc_ichthyo shard's, as every other ingest that places points uses it.
add_point_geom(con, "dic_sample", lon_col = "longitude", lat_col = "latitude")
assign_grid_key(con, "dic_sample") |> datatable(caption = "Grid assignment by position")
# every sample with a finite position gets a key (3,261/3,261 measured against the
# v2026.10.01 shard, 0 outside the grid)
n_pos_nogrid <- dbGetQuery(con, "
  SELECT COUNT(*) FROM dic_sample
  WHERE grid_key IS NULL AND latitude IS NOT NULL AND longitude IS NOT NULL
    AND isfinite(latitude) AND isfinite(longitude)")[[1]]
stopifnot("every DIC sample with a position must resolve a grid_key" = n_pos_nogrid == 0)
cat(glue("grid_key by position: {dbGetQuery(con, 'SELECT COUNT(grid_key) FROM dic_sample')[[1]]}/",
         "{dbGetQuery(con, 'SELECT COUNT(*) FROM dic_sample')[[1]]} dic_sample rows"), "\n")
```
## Data Preview
```{r}
#| label: preview-dic-sample
# exclude GEOMETRY columns for R driver compatibility
ds_cols <- dbGetQuery(con,
  "SELECT column_name FROM information_schema.columns
   WHERE table_name = 'dic_sample' AND data_type NOT LIKE 'GEOMETRY%'")$column_name
dbGetQuery(con, glue("SELECT {paste(ds_cols, collapse=', ')} FROM dic_sample LIMIT 100")) |>
  datatable(
    caption = glue(
      "dic_sample — first 100 of ",
      "{format(dbGetQuery(con, 'SELECT COUNT(*) FROM dic_sample')[[1]], big.mark=',')} rows"),
    rownames = FALSE, filter = "top")
```
```{r}
#| label: preview-dic-measurement
dbGetQuery(con, "SELECT * FROM dic_measurement LIMIT 100") |>
  datatable(
    caption = glue(
      "dic_measurement — first 100 of ",
      "{format(dbGetQuery(con, 'SELECT COUNT(*) FROM dic_measurement')[[1]], big.mark=',')} rows"),
    rownames = FALSE, filter = "top")
```
```{r}
#| label: preview-dic-summary
dbGetQuery(con, "SELECT * FROM dic_summary LIMIT 100") |>
  datatable(
    caption = glue(
      "dic_summary — first 100 of ",
      "{format(dbGetQuery(con, 'SELECT COUNT(*) FROM dic_summary')[[1]], big.mark=',')} rows"),
    rownames = FALSE, filter = "top")
```
## Emit Core Tables
Project this dataset into the shared consolidated core model
(`design_env-bio-consolidation.md`). These core tables **are** this ingest's
output: `release_database.qmd` concatenates the per-dataset shards rather than
re-deriving the core, so there is exactly one projection to keep correct.
DIC observations that share a physical Niskin with `calcofi_bottle` point at that
bottle's `sample_key`, so the two datasets deduplicate onto one event rather than
double-counting the bottle. Only a DIC sample on a Niskin that `calcofi_bottle`
does **not** carry mints its own `calcofi_dic:bottle:<md5>` key — and that md5
must be spelled identically in the `sample` and `obs` arms, or `obs` orphans.
**What is published (WS-1004X2, Ben 2026-10-04).** The observations of a DIC sample that
matches no bottle cast are published too, on the sample's own `calcofi_dic:bottle:<md5>`
key, **wherever the source gives the sample a depth**: the source's own depth, the
`grid_key` of its position, the `cruise_key` the reference resolves (span, then month;
NULL where the reference holds none) and the station the source states. These samples
have **no cast foreign key**: `parent_sample_key` is NULL and `root_sample_key` is the
sample itself, because the source names no cast (`calcofi_dic_01`). The values are
**not linked to a bottle cast**, and a consumer must not join them to one. A sample the
source gives no depth stays a `sample` row with no observations (counted and named in
the scope section below). The observations of the samples that do match a cast are
exactly what they were.
```{r}
#| label: emit_core
ds_key <- "calcofi_dic"

# the DIC natural key, for Niskins that calcofi_bottle does not carry. Defined
# ONCE and interpolated into both arms: the sample and obs arms must agree
# byte-for-byte or obs.sample_key resolves to nothing. Columns are the ones
# dic_sample and dic_measurement share, so the two spellings align.
dic_md5 <- function(a) glue("md5(concat_ws('|', {a}.expocode,
    CAST({a}.datetime_start_utc AS VARCHAR), CAST({a}.latitude AS VARCHAR),
    CAST({a}.longitude AS VARCHAR), CAST({a}.depth_m AS VARCHAR)))")

# This projection lives here, in the notebook that owns the dataset, not in a
# switch(dataset_key, ...) arm inside calcofi4db.
#
# sample — bottle-shaped leaf events, minting ONLY the Niskins calcofi_bottle
# does not already publish (the shared ones reuse bottle's sample_key in obs
# below). Parented to the matched cast where one was found. cruise_key: a matched
# cast's own (as published since v2026.10.01); a sample that matched no cast takes the
# one resolved from its ship + date in the Add Spatial section (NULL where the
# reference cruise table holds none).
append_sample(con, glue("
  SELECT * FROM (
    SELECT 'calcofi_dic:bottle:' || {dic_md5('d')} AS sample_key, 'bottle' AS sample_type,
           CASE WHEN c.cast_id IS NULL THEN NULL
                ELSE 'calcofi_bottle:cast:' || CAST(c.cast_id AS VARCHAR) END AS parent_sample_key,
           COALESCE(
             CASE WHEN c.cast_id IS NULL THEN NULL
                  ELSE 'calcofi_bottle:cast:' || CAST(c.cast_id AS VARCHAR) END,
             'calcofi_dic:bottle:' || {dic_md5('d')}) AS root_sample_key,
           '{ds_key}' AS dataset_key,
           COALESCE(d.grid_key, c.grid_key) AS grid_key,  -- the sample's own position; a matched cast's key only where it has none (check_grid_key_assignment())
           d.site_key,
           CASE WHEN c.cast_id IS NULL THEN d.cruise_key ELSE c.cruise_key END AS cruise_key,
           CAST(c.order_occ AS INTEGER) AS order_occ,
           d.latitude, d.longitude, CAST(d.datetime_start_utc AS TIMESTAMP) AS datetime,
           d.depth_m AS depth_min_m, d.depth_m AS depth_max_m,
           NULL::VARCHAR AS tow_type
    FROM dic_sample d LEFT JOIN casts c ON d.cast_id = c.cast_id
    WHERE d.bottle_id IS NULL OR d.bottle_id NOT IN (SELECT bottle_id FROM bottle)
  ) q QUALIFY row_number() OVER (PARTITION BY sample_key) = 1"))

# obs, arm 1 — dedup onto calcofi_bottle: a DIC row sharing a physical Niskin points at
# that bottle's sample_key; only the non-shared Niskins use the minted DIC key. Rows of
# a matched cast only: unchanged since v2026.10.01 (asserted in the scope section).
append_obs(con, glue("
  SELECT 'env', '{ds_key}',
         CASE WHEN dm.bottle_id IS NOT NULL AND dm.bottle_id IN (SELECT bottle_id FROM bottle)
              THEN 'calcofi_bottle:bottle:' || CAST(dm.bottle_id AS VARCHAR)
              ELSE 'calcofi_dic:bottle:' || {dic_md5('dm')} END,
         c.grid_key, c.cruise_key, dm.latitude, dm.longitude,
         CAST(dm.datetime_start_utc AS TIMESTAMP), dm.depth_m, dm.depth_m,
         NULL::VARCHAR, NULL::VARCHAR, dm.measurement_type, dm.measurement_value,
         dm.measurement_qual, NULL::DOUBLE
  FROM dic_measurement dm JOIN casts c USING (cast_id)"))
n_obs_cast <- dbGetQuery(con, "SELECT COUNT(*) FROM obs")[[1]]

# obs, arm 2 -- a sample that matched NO cast, wherever the source gives it a depth.
# Keyed on the sample's own minted key; grid_key / cruise_key are read back from that
# sample row, so an obs row can never disagree with its sample. There is no cast
# foreign key to fabricate: the source names none (calcofi_dic_01).
append_obs(con, glue("
  SELECT 'env', '{ds_key}', s.sample_key, s.grid_key, s.cruise_key,
         dm.latitude, dm.longitude, CAST(dm.datetime_start_utc AS TIMESTAMP),
         dm.depth_m, dm.depth_m, NULL::VARCHAR, NULL::VARCHAR,
         dm.measurement_type, dm.measurement_value, dm.measurement_qual, NULL::DOUBLE
  FROM dic_measurement dm
  JOIN sample s ON s.sample_key = 'calcofi_dic:bottle:' || {dic_md5('dm')}
  WHERE dm.cast_id IS NULL AND dm.depth_m IS NOT NULL"))

core <- list(
  sample = dbGetQuery(con, "SELECT COUNT(*) FROM sample")[[1]],
  obs    = dbGetQuery(con, "SELECT COUNT(*) FROM obs")[[1]])
cat(glue(
  "core projection — sample={core$sample %||% 0} obs={core$obs %||% 0}\n"))
n_obs <- core$obs
n_shared <- dbGetQuery(con,
  "SELECT COUNT(*) FROM obs WHERE sample_key LIKE 'calcofi_bottle:bottle:%'")[[1]]
n_dup <- dbGetQuery(con, "
  SELECT COUNT(*) FROM (SELECT sample_key FROM sample GROUP BY 1 HAVING COUNT(*) > 1)")[[1]]
stopifnot(
  "obs must be one row per DIC measurement of a matched cast, plus one per unmatched sample's measurement with a depth" =
    n_obs == dbGetQuery(con, "SELECT COUNT(*) FROM dic_measurement dm JOIN casts c USING (cast_id)")[[1]] +
             dbGetQuery(con, "SELECT COUNT(*) FROM dic_measurement
                              WHERE cast_id IS NULL AND depth_m IS NOT NULL")[[1]],
  "sample_key must be unique (the md5 dedup)" = n_dup == 0,
  # grid_key was NULL on 3,255 of 3,261 samples at v2026.10.01 (taken from the matched
  # cast alone); a sample with a position now carries its own, a cast's wins
  "every emitted DIC sample with a position must carry a grid_key" =
    dbGetQuery(con, "SELECT COUNT(*) FROM sample WHERE dataset_key = 'calcofi_dic'
                     AND grid_key IS NULL AND latitude IS NOT NULL
                     AND longitude IS NOT NULL")[[1]] == 0,
  "some DIC obs must dedup onto calcofi_bottle" = n_shared > 0,
  "every obs.sample_key must resolve in sample or in the bottle dataset" =
    dbGetQuery(con, "SELECT COUNT(*) FROM obs o LEFT JOIN sample s USING (sample_key)
                     WHERE s.sample_key IS NULL
                       AND o.sample_key NOT LIKE 'calcofi_bottle:bottle:%'")[[1]] == 0,
  # the md5 must be spelled the same in both arms: a DIC-keyed obs row whose key
  # is absent from sample means the two spellings drifted
  "every minted DIC obs key must resolve in this dataset's sample" =
    dbGetQuery(con, "SELECT COUNT(*) FROM obs o LEFT JOIN sample s USING (sample_key)
                     WHERE o.sample_key LIKE 'calcofi_dic:bottle:%'
                       AND s.sample_key IS NULL")[[1]] == 0)
cat(glue("obs: {format(n_obs, big.mark=',')} rows, {format(n_shared, big.mark=',')} ",
         "sharing a Niskin with calcofi_bottle"), "\n")
```
### Scope of the published values
Two kinds of number, kept apart on purpose (WS-1004X3). **Pins** are what this notebook
alone determines from its own source file `CALCOFI_DIC_20250122.csv`: rows, distinct samples,
the values per type, the samples with no source depth. A re-delivered file that changes them
stops the notebook. **Measured and reported** are what depends on another dataset: how many
samples match a bottle cast, and how many of those share a bottle, move whenever
`calcofi_bottle` or the `swfsc_ichthyo` reference is re-staged (v2026.10.01 had 6 minted samples
on a cast; the 2026-10-04 re-stage had 7, because two casts of one station and date tie for the
same DIC row and `match_by_site_datetime()` has no tie-break). They are guarded by invariants
instead of pinned: the parts add up to the whole, every sample matching no cast with a depth
publishes its observations, no cast key is fabricated, and the arms hold exactly their rows.
```{r}
#| label: scope-assertions
# PINS: measured from the source file alone (WS-1004X2 2026-10-04; unchanged at the 2026-10-04
# re-stage, WS-1004X3). dic_measurement is every non-missing source value, before any matching.
dic_source <- list(
  rows               = 4391L,
  samples_distinct   = 4095L,  # distinct (expocode, datetime, lat, lon, depth)
  samples_no_depth   = 3L,     # source Depth = -999 (any cast status)
  values             = c(alkalinity = 4064L, ctdtemp_its90 = 4009L, dic = 4237L, salinity_pss78 = 4081L),
  values_no_depth    = c(alkalinity = 3L, dic = 3L))
as_counts <- function(d) setNames(as.integer(d$n), d$measurement_type)
d_src <- dbGetQuery(con, "
  SELECT (SELECT COUNT(*) FROM dic_sample) AS rows,
         (SELECT COUNT(*) FROM (SELECT DISTINCT expocode, datetime_start_utc, latitude, longitude, depth_m
                                FROM dic_sample)) AS samples_distinct,
         (SELECT COUNT(*) FROM (SELECT DISTINCT expocode, datetime_start_utc, latitude, longitude
                                FROM dic_sample WHERE depth_m IS NULL)) AS samples_no_depth")
d_src_val <- dbGetQuery(con, "SELECT measurement_type, COUNT(*) AS n FROM dic_measurement GROUP BY 1 ORDER BY 1")
d_src_nod <- dbGetQuery(con, "
  SELECT measurement_type, COUNT(*) AS n FROM dic_measurement WHERE depth_m IS NULL GROUP BY 1 ORDER BY 1")
stopifnot(
  "source rows" = d_src$rows == dic_source$rows,
  "distinct source samples" = d_src$samples_distinct == dic_source$samples_distinct,
  "source samples with no depth" = d_src$samples_no_depth == dic_source$samples_no_depth,
  "source values per measurement type" =
    identical(as_counts(d_src_val), dic_source$values[sort(names(dic_source$values))]),
  "source values with no depth, per measurement type" =
    identical(as_counts(d_src_nod), dic_source$values_no_depth[sort(names(dic_source$values_no_depth))]))

# MEASURED + INVARIANTS: everything that depends on the bottle cast match
d_scope <- dbGetQuery(con, "
  SELECT COUNT(*) AS n_minted,
         COUNT(*) FILTER (WHERE parent_sample_key IS NOT NULL) AS n_with_cast,
         COUNT(*) FILTER (WHERE parent_sample_key IS NULL)     AS n_no_cast,
         COUNT(*) FILTER (WHERE parent_sample_key IS NULL AND depth_min_m IS NOT NULL) AS n_no_cast_depth,
         COUNT(*) FILTER (WHERE parent_sample_key IS NULL AND depth_min_m IS NULL)     AS n_no_depth
  FROM sample WHERE dataset_key = 'calcofi_dic'")
d_obs_cast <- dbGetQuery(con, "
  SELECT measurement_type, COUNT(*) AS n FROM dic_measurement
  WHERE cast_id IS NOT NULL GROUP BY 1 ORDER BY 1")
d_new <- dbGetQuery(con, "
  SELECT o.measurement_type, COUNT(*) AS n
  FROM obs o JOIN sample s USING (sample_key)
  WHERE s.dataset_key = 'calcofi_dic' AND s.parent_sample_key IS NULL
  GROUP BY 1 ORDER BY 1")
d_left <- dbGetQuery(con, "
  SELECT measurement_type, COUNT(*) AS n FROM dic_measurement
  WHERE cast_id IS NULL AND depth_m IS NULL GROUP BY 1 ORDER BY 1")
d_pub <- dbGetQuery(con, "SELECT measurement_type, COUNT(*) AS n FROM obs GROUP BY 1 ORDER BY 1")
n_new_expected <- dbGetQuery(con, "
  SELECT COUNT(*) FROM dic_measurement WHERE cast_id IS NULL AND depth_m IS NOT NULL")[[1]]

stopifnot(
  "minted samples = on a cast + matching no cast" = d_scope$n_minted == d_scope$n_with_cast + d_scope$n_no_cast,
  "no-cast samples = with a depth + with no depth" = d_scope$n_no_cast == d_scope$n_no_cast_depth + d_scope$n_no_depth,
  # the matching never invents or loses a source sample: every no-cast source sample is minted once
  "every source sample matching no cast must be minted exactly once" =
    d_scope$n_no_cast == dbGetQuery(con, "
      SELECT COUNT(*) FROM (SELECT DISTINCT expocode, datetime_start_utc, latitude, longitude, depth_m
                            FROM dic_sample WHERE cast_id IS NULL)")[[1]],
  # the only no-cast sample left without observations is one the source gives no depth
  "samples matching no cast with no depth" =
    d_scope$n_no_depth <= dic_source$samples_no_depth,
  # no cast foreign key is fabricated: a sample that matched no cast is its own root,
  # and a parent that is named exists in the bottle shard
  "a sample matching no cast must be its own root" =
    dbGetQuery(con, "SELECT COUNT(*) FROM sample WHERE dataset_key = 'calcofi_dic'
                     AND parent_sample_key IS NULL AND root_sample_key <> sample_key")[[1]] == 0,
  "a named cast parent must exist in calcofi_bottle" =
    dbGetQuery(con, "SELECT COUNT(*) FROM sample s
                     WHERE s.dataset_key = 'calcofi_dic' AND s.parent_sample_key IS NOT NULL
                       AND s.parent_sample_key NOT IN (SELECT sample_key FROM _bottle_sample)")[[1]] == 0,
  # every sample matching no cast, with a depth, carries observations; none without
  "every no-cast sample with a depth must carry observations, none without a depth" =
    dbGetQuery(con, "
      SELECT COUNT(*) FROM sample s
      WHERE s.dataset_key = 'calcofi_dic' AND s.parent_sample_key IS NULL
        AND (s.depth_min_m IS NOT NULL) <> EXISTS (SELECT 1 FROM obs o WHERE o.sample_key = s.sample_key)")[[1]] == 0,
  # the arms hold exactly their rows: arm 1 = every value of a matched cast, arm 2 = every value
  # of an unmatched sample with a depth, and nothing else
  "obs arm 1 (cast-matched) must hold every value of a matched cast" =
    n_obs_cast == sum(d_obs_cast$n),
  "obs arm 2 (no cast, with a depth) must hold exactly those values" =
    sum(d_new$n) == n_new_expected,
  # nothing is lost between the source and obs: published + left out = every source value, per type
  "published + left out must account for every source value, per type" =
    all(as_counts(d_pub) + coalesce(as_counts(d_left)[names(as_counts(d_pub))], 0L) ==
          dic_source$values[names(as_counts(d_pub))]))
cat(glue("minted {d_scope$n_minted}: {d_scope$n_with_cast} on a cast, {d_scope$n_no_cast} matching no cast ",
         "({d_scope$n_no_cast_depth} with a depth, {d_scope$n_no_depth} without)"), "\n")
cat(glue("obs: {format(n_obs_cast, big.mark = ',')} of matched casts; ",
         "{format(sum(d_new$n), big.mark = ',')} newly published on {d_scope$n_no_cast_depth} no-cast samples ",
         "({paste(d_new$measurement_type, d_new$n, collapse = ', ')}); ",
         "left out for want of a depth: {sum(d_left$n)}"), "\n")
# name what stays out: a sample row, no observations (calcofi_dic_07)
dbGetQuery(con, "
  SELECT expocode, site_key, CAST(datetime_start_utc AS DATE) AS date, latitude, longitude,
         STRING_AGG(measurement_type || '=' || CAST(measurement_value AS VARCHAR), '; ') AS values_left_out
  FROM dic_measurement WHERE cast_id IS NULL AND depth_m IS NULL
  GROUP BY 1, 2, 3, 4, 5") |>
  datatable(caption = "Samples matching no cast with no source depth: a sample row, no observations")
# depth is a coordinate: finite, >= 0 and <= CC_DEPTH_MAX_M on every DIC row of sample and obs
d_depth <- check_depth_bounds(con, tbls = c("sample", "obs")) |> filter(dataset_key == ds_key)
stopifnot("DIC depth coordinates must pass check_depth_bounds()" = all(d_depth$status == "ok"))
datatable(d_depth, caption = "check_depth_bounds() on the DIC rows of sample and obs")
```
### Measurement bounds on the published values
`check_measurement_bounds()` over everything the DIC `obs` now carries, matched and
unmatched alike; read-only (nothing is dropped, and no bound is set to an observed range).
```{r}
#| label: bounds
bounds_dic <- check_measurement_bounds(
  con, "obs", mt = d_meas_type, dataset_key = ds_key, depth_col = "depth_min_m")
bounds_datatable(bounds_dic)
stopifnot("every published DIC type must respect its declared bound" =
            all(bounds_dic$status == "ok"))
```
### Cruise and ship resolution of the minted samples
A sample is keyed to a cruise only through a ship the SWFSC reference carries and a cruise it
holds for that ship; the rest are left NULL, never keyed to a cruise the reference does not
know (the release's `complete_cruise_reference()` derived-row ratchet only ever goes down).
```{r}
#| label: cruise-assertions
d_ck <- dbGetQuery(con, "
  SELECT COUNT(*) FILTER (WHERE parent_sample_key IS NULL AND cruise_key IS NOT NULL) AS n_no_cast_keyed,
         COUNT(*) FILTER (WHERE parent_sample_key IS NULL AND cruise_key IS NULL)     AS n_no_cast_null,
         COUNT(*) FILTER (WHERE parent_sample_key IS NOT NULL AND cruise_key IS NULL) AS n_cast_null
  FROM sample WHERE dataset_key = 'calcofi_dic'")
# The count depends on the `cruise` reference, so it is MEASURED, not pinned: measured
# 2026-10-04 on the 2026-09-26 ichthyo export (WS-1004X3): 2,920 keyed (span or month),
# 335 NULL on 8 EXPOCODEs (the named table below; 240 are NOAA Ship Sally Ride, 33P4,
# whose cruises the ichthyo export lacks). The guard is an invariant plus a ratchet:
#  * a sample is NULL only if its ship is not in the ship reference, or the reference holds
#    no cruise of that ship whose span (+/- 3 d) contains the date or whose key is the
#    event's month (what resolve_cruise_key() would have used): a key the reference does
#    hold must never be missed;
#  * the NULL count may only go DOWN from CRUISE_NULL_NO_CAST_MAX; lower it to the number
#    measured here whenever it falls (and the release's key_null_max for calcofi_dic).
CRUISE_NULL_NO_CAST_MAX <- 335L
n_null_resolvable <- dbGetQuery(con, "
  SELECT COUNT(*) FROM sample s
  JOIN dic_sample d ON s.sample_key = 'calcofi_dic:bottle:' || md5(concat_ws('|', d.expocode,
       CAST(d.datetime_start_utc AS VARCHAR), CAST(d.latitude AS VARCHAR),
       CAST(d.longitude AS VARCHAR), CAST(d.depth_m AS VARCHAR)))
  WHERE s.dataset_key = 'calcofi_dic' AND s.parent_sample_key IS NULL AND s.cruise_key IS NULL
    AND d.ship_key IS NOT NULL
    AND EXISTS (
      SELECT 1 FROM cruise c JOIN ship sh ON sh.ship_key = c.ship_key
      WHERE c.ship_key = d.ship_key
        AND (CAST(d.datetime_start_utc AS DATE)
               BETWEEN c.date_min - INTERVAL 3 DAY AND c.date_max + INTERVAL 3 DAY
             OR c.cruise_key = strftime(CAST(d.datetime_start_utc AS DATE), '%Y-%m') || '-' || sh.ship_nodc))")[[1]]
stopifnot(
  "a no-cast sample the reference could key must not be left NULL" = n_null_resolvable == 0,
  "NULL cruise_key on samples matching no cast may only go down (ratchet)" =
    d_ck$n_no_cast_null <= CRUISE_NULL_NO_CAST_MAX,
  # a sample on a matched cast carries that cast's own key; DIC adds no NULL of its own
  "a sample on a matched cast must carry the cast's own cruise_key" =
    d_ck$n_cast_null == dbGetQuery(con, "
      SELECT COUNT(*) FROM sample s JOIN casts c
        ON s.parent_sample_key = 'calcofi_bottle:cast:' || CAST(c.cast_id AS VARCHAR)
      WHERE s.dataset_key = 'calcofi_dic' AND c.cruise_key IS NULL")[[1]])
if (d_ck$n_no_cast_null < CRUISE_NULL_NO_CAST_MAX)
  cat(glue("NOTE: NULL cruise_key fell to {d_ck$n_no_cast_null}; lower CRUISE_NULL_NO_CAST_MAX ",
           "(was {CRUISE_NULL_NO_CAST_MAX})"), "\n")
cat(glue("cruise_key on minted DIC samples matching no cast: {d_ck$n_no_cast_keyed} keyed, ",
         "{d_ck$n_no_cast_null} NULL; {d_ck$n_cast_null} NULL on a matched cast"), "\n")
dbGetQuery(con, "
  SELECT d.expocode, MIN(d.ship_name) AS ship_name, MIN(d.ship_key) AS ship_key,
         COUNT(DISTINCT s.sample_key) AS n_samples,
         CASE WHEN MIN(d.ship_key) IS NULL THEN 'ship not in the SWFSC ship reference'
              ELSE 'no reference cruise for that ship and month' END AS why_null
  FROM sample s
  JOIN dic_sample d ON s.sample_key = 'calcofi_dic:bottle:' || md5(concat_ws('|', d.expocode,
       CAST(d.datetime_start_utc AS VARCHAR), CAST(d.latitude AS VARCHAR),
       CAST(d.longitude AS VARCHAR), CAST(d.depth_m AS VARCHAR)))
  WHERE s.dataset_key = 'calcofi_dic' AND s.parent_sample_key IS NULL AND s.cruise_key IS NULL
  GROUP BY d.expocode ORDER BY d.expocode") |>
  datatable(caption = "DIC cruises left without a cruise_key (calcofi_dic_07)")
```
## Write Parquet Outputs
```{r}
#| label: write-parquet
dir_create(dir_parquet)

# collect mismatches for manifest
mismatches <- list(
  measurement_types = collect_measurement_type_mismatches(
    con, here("metadata/measurement_type.csv")),
  cruise_keys       = collect_cruise_key_mismatches(con, "dic_sample"))

tbls_out <- core_output_tables(con, extra = c("measurement_type", "dataset"))
parquet_stats <- write_parquet_outputs(
  con              = con,
  output_dir       = dir_parquet,
  tables           = tbls_out,
  sort_by          = list(obs = c("grid_key", "measurement_type")),
  strip_provenance = FALSE,
  mismatches       = mismatches
)

# relationships.json describes what is actually published (the core), so it is
# written here, once core_output_tables() has determined the shard set
build_relationships_json(
  rels       = core_relationships(tbls_out),
  output_dir = dir_parquet,
  provider   = provider,
  dataset    = dataset
)
parquet_stats |>
  mutate(file = basename(path)) |>
  select(-path) |>
  datatable(caption = "Parquet export statistics")
```
## Write Metadata
```{r}
#| label: write-metadata
d_tbls_rd <- read_csv(here("metadata/calcofi/dic/tbls_redefine.csv"))
d_flds_rd <- read_csv(here("metadata/calcofi/dic/flds_redefine.csv"))

metadata_path <- build_metadata_json(
  con          = con,
  d_tbls_rd    = d_tbls_rd,
  d_flds_rd    = d_flds_rd,
  metadata_derived_csv = here("metadata/core_dictionary.csv"),
  output_dir   = dir_parquet,
  tables       = tbls_out,
  set_comments = TRUE,
  provider     = provider,
  dataset      = dataset,
  workflow_url = cc$workflow_url,
  tables_owned = tables_owned
)
```
```{r}
#| label: show_metadata_json
listviewer::jsonedit(
  jsonlite::fromJSON(metadata_path, simplifyVector = FALSE),
  mode = "view")
```
```{r}
#| label: show_relationships_json
listviewer::jsonedit(
  jsonlite::fromJSON(
    file.path(dir_parquet, "relationships.json"),
    simplifyVector = FALSE),
  mode = "view")
```
## Upload to GCS Archive
```{r}
#| label: upload-gcs
sync_to_gcs(
  local_dir   = dir_stage,
  sidecar_dir = dir_parquet,
  gcs_prefix = glue("ingest/{dir_label}"),
  bucket     = "calcofi-db")
```
## Questions for Data Providers
Open questions on this dataset, tracked in `metadata/calcofi/dic/questions.csv`
and surfaced here so they travel with the workflow rather than living in
someone's inbox.
```{r}
#| label: provider-questions
# one validated read + render for every ingest: the vocabulary and the column
# order live in calcofi4db, not in 16 hand-written factor() calls
questions_datatable(
  here(cc$questions_file),
  caption = "Questions for the CalCOFI DIC data providers (ranked)")
```
## Cleanup
```{r}
#| label: cleanup
close_duckdb(con)
cat(glue("Parquet outputs written to: {dir_parquet}"), "\n")
```
## TODO
- [x] Tidy data: all measurements pivoted to long format in
`dic_measurement` — `dic_sample` has position/time only
- [x] Handle replicates: `dic_summary` aggregates with
avg/stddev per position, following `ctd_summary` pattern
- [ ] Spatial matching: match unmatched DIC samples to `site` and `grid`
via lat/lon projection to CalCOFI coordinate system (see issue #47)
- [ ] Validate against calcofi_bottle `dic_rep1`/`dic_rep2` values for
overlapping bottles
- [ ] Add WOCE flag interpretation (2=good, 3=questionable, 4=bad,
9=missing) to metadata
- [ ] Consider merging `dic_measurement` into `bottle_measurement` for
matched samples via a VIEW that unions both tables for analysis
::: {.callout-caution collapse="true"}
## Session Info
```{r session_info}
devtools::session_info()
```
:::